

LakeSail @LakeSail
Spark rewritten in Rust. A new standard for unified compute, reimagined for modern data and AI infrastructure. lakesail.com San Francisco Joined September 2024-
Tweets112
-
Followers2K
-
Following5
-
Likes100
AWS Lab's benchmark: awslabs.github.io/data-on-eks/do… LakeSail's benchmark: lakesail.com/blog/tpcds-ben…
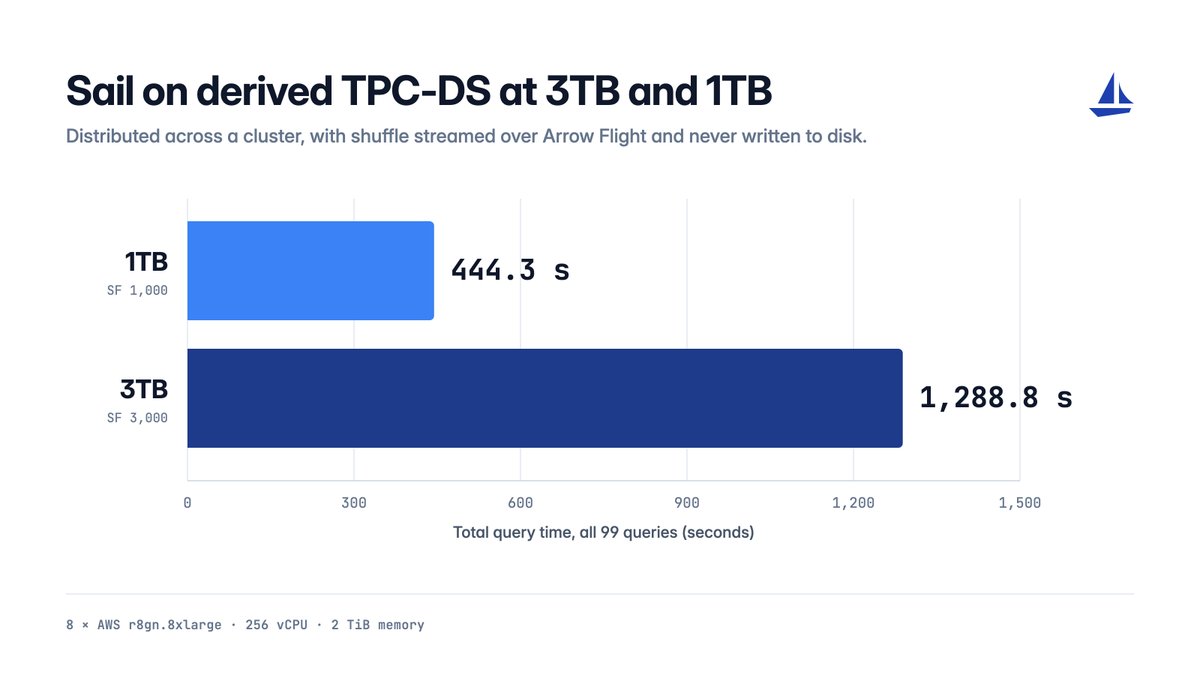
We just published a derived TPC-DS for Sail at 3 TB and 1 TB. Here is a comparison of our benchmark to another independently published benchmark on Spark and Spark + Gluten/Velox by AWS.

If you want help with migrating off Spark, we provide support that guarantees your workloads will be cheaper, faster, and correct… or you pay nothing. lakesail.com/spark-migratio…
A data platform that's simple, transparently priced, and ridiculously fast. The LakeSail Platform runs your Spark SQL and Python jobs on a Rust-native runtime. It's faster than Spark, drastically cuts hardware costs, and scales from a single node to a multi-node cluster. It reads and writes your Delta Lake and Iceberg tables where they already live, so your lakehouse stays open and your data stays in place. For those who want to run Sail in production most efficiently, with all the operations handled for you, this platform was built for you.
Sail ran derived TPC-DS at 3TB and 1TB across a distributed cluster, and the results are the latest evidence for our vision in rethinking distributed compute. Hadoop pioneered open-source distributed processing, built around disk. Spark moved intermediate data into memory, though its shuffle stayed disk-first. When we started Sail, we envisioned another shift in distributed compute, toward doing even more of the work in memory, with an engine built entirely in Rust. We built the first version of Sail's distributed architecture in November 2024, with Arrow Flight carrying shuffle data between workers, and redesigned the cluster control plane earlier this year. Arrow Flight shuffle can look surprising at first. A TPC-DS query with dozens of stages and a few hundred partitions can have more than a million logical shuffle streams active in the cluster. Arrow Flight is built on gRPC and HTTP/2, so one TCP connection per pair of workers carries them all. The same approach has since come up in the DataFusion Comet and Riffle communities as well, and we are glad to have started proving this direction two years ago. The full benchmark ran in 1,289 seconds at 3TB and 444 seconds at 1TB, with no shuffle data written to disk. On similar hardware and settings, Sail outperforms the published TPC-DS results for Spark and Spark accelerators at these scales. The post covers the results, the design, and the full setup: lakesail.com/blog/tpcds-ben…
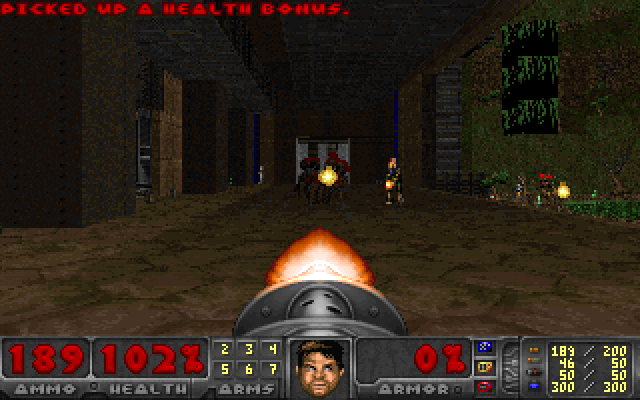
Sail runs Doom with a single query! I ported SQLDoom to @LakeSail 's Sail, the AI-native expansion of @ApacheSpark whole ecosystem to Rust. rust.ai/sail-runs-doom/
No JVM. 10x faster. 98% cost reduction.
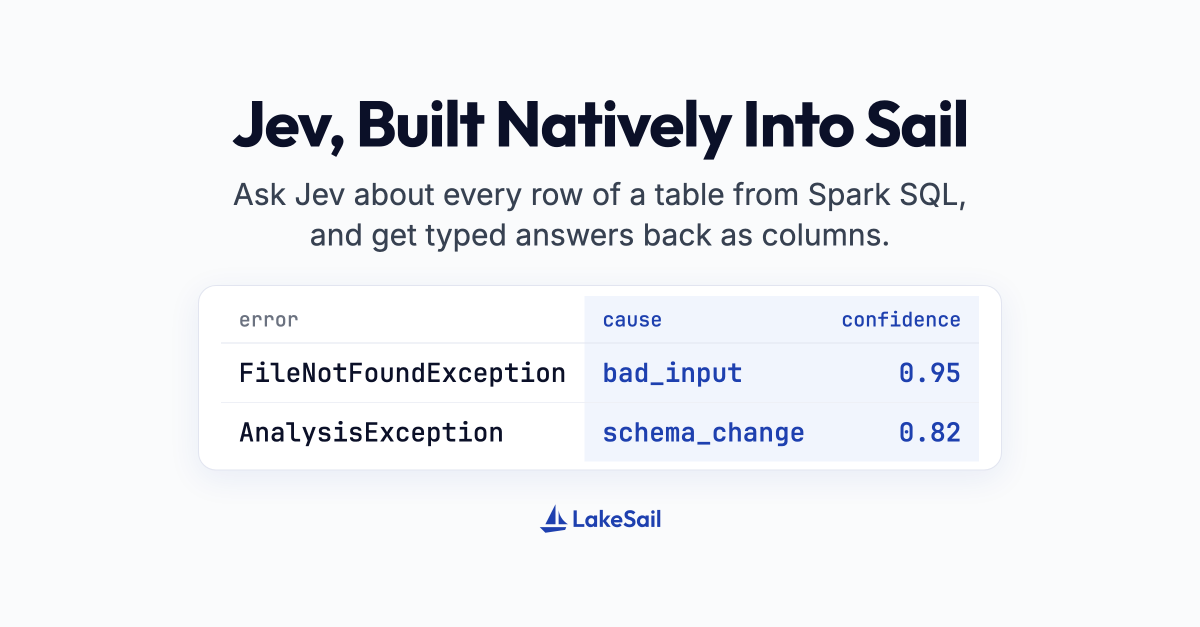
Sail is the first open-source engine to ship with built-in Jev support! Check out the docs to get started: docs.lakesail.com/sail/latest/gu…
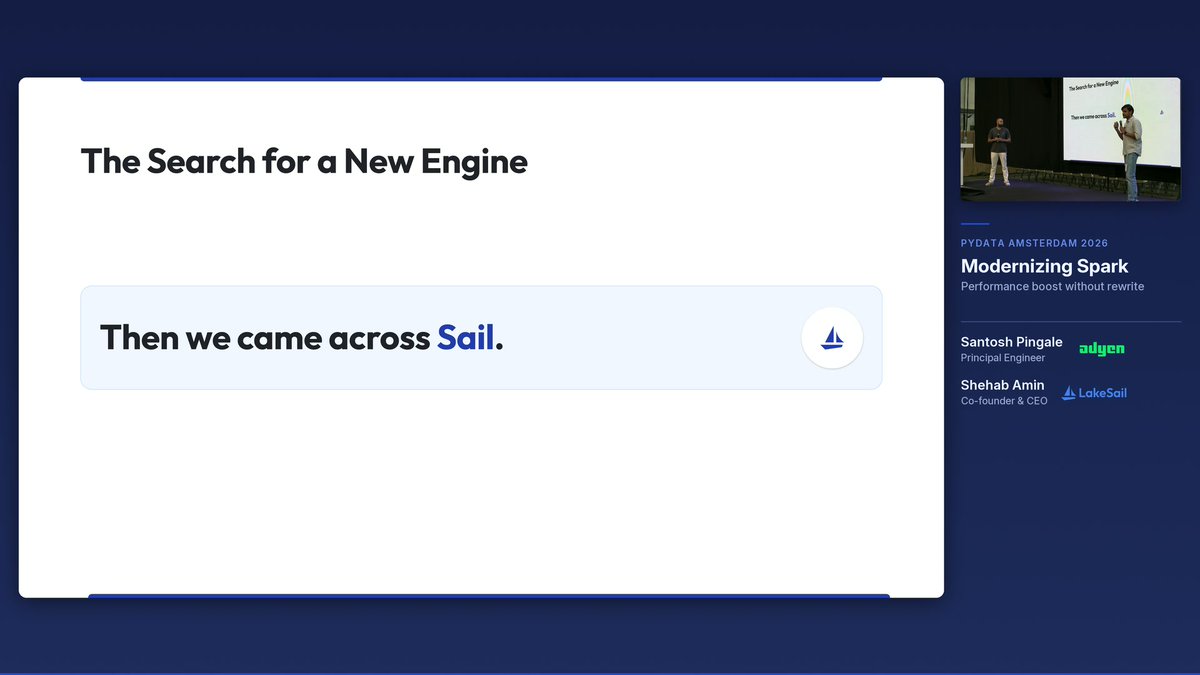
Learn more and watch the full presentation here: lakesail.com/blog/adyen-spa…
Two results their Principal Engineer, Santosh, shared: • A CI test suite went from 1,335 seconds on Spark to 78.44 seconds on Sail, roughly 17x faster. • An Airflow job's median runtime dropped from about 57 minutes to 8.5 minutes, using fewer cores and less memory.
Adyen’s data team explored DuckDB and Polars but landed on Sail as a new engine. They explain their reasoning in a recent presentation they gave at PyData Amsterdam.
Sail is the first open-source engine to ship with built-in Jev support lakesail.com/blog/jev-built…
Blog + examples: lakesail.com/blog/jev-built…
Sail now includes Jev built natively into the engine, the first of its kind. Any Spark SQL or DataFrame query can ask Jev about every row of a table, with nothing extra to install. The answers come back as typed columns you can filter, join, and aggregate like any other data. The same query can run on your laptop or across a cluster. Check out the full release and some examples of it in action. Link in thread.
More engineering details: lakesail.com/blog/sail-cele…
A shuffle in Sail, before and after Apache Celeborn.
Sail 0.7.1 adds the first ever Rust implementation of Apache Celeborn as a shuffle backend. If you already run Celeborn for your Spark workloads, Sail uses that cluster as it stands. The same masters, same workers, nothing is changed on the Celeborn side. Read more on the engineering in our blog: lakesail.com/blog/sail-cele…

Vikash @Vikash395000
668 Followers 3K Following
YUSUF WALIU @keshinero_yusuf
54 Followers 3K Following Lord_Yusuf A Knight 🗡️ EL_CHAP0 $Giza https://t.co/HD0UstKq3U
Angel Salgado Sanchez @AngelSalgado21x
3 Followers 58 Following Church Leader Business & Comp Sci Student Husband

M J @mj2019mkt
53 Followers 717 Following
Football Fans @JacobBetchell
59 Followers 1K Following
Mery casas @Meri_casas
29 Followers 142 Following
ikatz23 @Rocio85780985
1 Followers 5 Following
Evan Tech @Evan_Tach
15K Followers 90 Following ➤ Exploring AI & New Tech ➤ Sharing Useful Content ➤ Open for Paid Collabs & Partnerships ➤ 📧[email protected]
Juan Manuel @juanmreyesa
211 Followers 2K Following 🇪🇸🇺🇾 Trabajo en tecnología y tengo una tienda de animales exóticos en Montevideo.

Bambang Purnomosidi D... @bpdp
1K Followers 3K Following Faculty at UTDI. On the way to leave the academia to pursue happiness in teaching and research. Also at https://t.co/jtefF8c7n6 (bpdp)
Eduardo Herondale @EduardoHeronda1
940 Followers 345 Following 🍃 Sou de BH, 🌆 🍂 30 anos 👦 🌷 26/03 🎂 🌾 Ariano ♈ 🍀 Completamente apaixonado ❣ 🌴 Objetivo: Superar os desafios da vida
Pure Man @PureMan292619
8 Followers 701 Following
Ricardo @Ricardo78918746
13 Followers 102 Following


Kesh Raymond @Keshinero_dc
10 Followers 679 Following https://t.co/G7DNmf5e7z https://t.co/rECJGhihEK
Paulo Heck @heck_paulo
14 Followers 684 Following

Benjamin Nothdurft @DataDuke
3K Followers 5K Following Java, DevOps, Cloud Native • 8x @oracleace Pro @DOAGeV @iJUGeV #usualsuspects 💪🏼😋💜🎉@JavaLandConf @CloudLandOrg @microXchg @sfjug @swkthde @jugthde @d4kthde

1922_agus @cac_1922
4 Followers 83 Following
wejunka @wejunka2
18 Followers 78 Following
Bubaker Alhadhrami @BbakAlh70985
336 Followers 7K Following
Samuel Robinson @sammyron
402 Followers 668 Following
RAJ @LAthmakuri14196
0 Followers 3 Following
kika @kikauy
13 Followers 225 Following
Guilherme Paulino @galo_sasa
33 Followers 400 Following
Eloisa Dizon @elowis0427
0 Followers 6 Following
Wayne sialo @SialoWayne48540
369 Followers 6K Following real Chelsea football club fan ..... me 💙💙 Chelsea football club.... 🤝💙
Flix Muller @felix_muller_ai
17K Followers 7K Following Growth Specialist for AI (SaaS) | AI Creator | Influencer Marketing | 📩 DM for collabs | 📩[email protected]
최각순 @choegagsun70635
14 Followers 224 Following
Laur Badin @laurbadin
533 Followers 4K Following Privacy & Cyber lawyer | tech geek | part-time storyteller | black belt. Views are my own ≠ legal advice.
rena @NacarioRenz
2K Followers 8K Following
Andrés Felipe Cuadro... @Andresmessista1
39 Followers 227 Following Estoy demasiado politizado para ser feliz Millonarios FC. 💙🤍

bianco @BinacoRo
29 Followers 2K Following
HienDieu @HienDieu842463
34 Followers 248 Following
Adnan Ahmed Tonmoy @adna33414
10 Followers 109 Following


Johannamarie Bautista @JohannamarieBa1
0 Followers 101 Following
Kore Geo @koregeography
394 Followers 3K Following Uncovering geographic angles. LIKE | SHARE | FOLLOW

Alva Jonson @AlvaJonsonuoch
135 Followers 743 Following Training news,Digital marketing, web research, Data entry, Twitter setup, Facebook page setup,Copy Past, data formating, data cleaning.
🟧 KAI @RealKaiChang
93 Followers 2K Following Founder @ Stealth | ex @Crop_Safe CTO | ex @CreditSuisse | Pioneer @pioneerdotapp | CompSc @HKUniversity
Kyle Pomykala @KylePomykala
198 Followers 530 Following Data Engineering Human. I work for @lakesail and build data things
Alexy 🤍💙🤍 @ChiefScientist
6K Followers 7K Following Ecosystems, @lakesailhq. Cofounder, AI Alliance, GenAI@LF, https://t.co/gVgl0OqOH5 @northeastern, @scalebythebay. Publisher: https://t.co/VG37Z4xowL, https://t.co/tx4mrl2WS8. OSS AI: https://t.co/xghHzIo4CX
Mim @mim_djo
13K Followers 3K Following #MicrosofFabric user advocate, interests in Small Data & Self Service #Microsoftemployee since Dec 2023 , but my tweets are my own
Shehab Amin @shehab_amins
86 Followers 24 Following Co-Founder & CEO @LakeSail https://t.co/hqyRCmae8ITrends for United States
You might like


















