

InferX Developers @InferXDevs
All our roads bringing tokens more closer to Developers. follow us in this journey. inferx.net San Francisco, CA Joined September 2026-
Tweets65
-
Followers13
-
Following8
-
Likes37
Let’s Go…. DeepSeek-V4.1-Flash-1017 is live on InferX.net
DeepSeek-V4.1-Flash-1017 is now live on InferX, available at 50% off. Let’s put it to the test and see how it fares against the other DeepSeek Flash models. Try it and tell us what you find. inferx.net
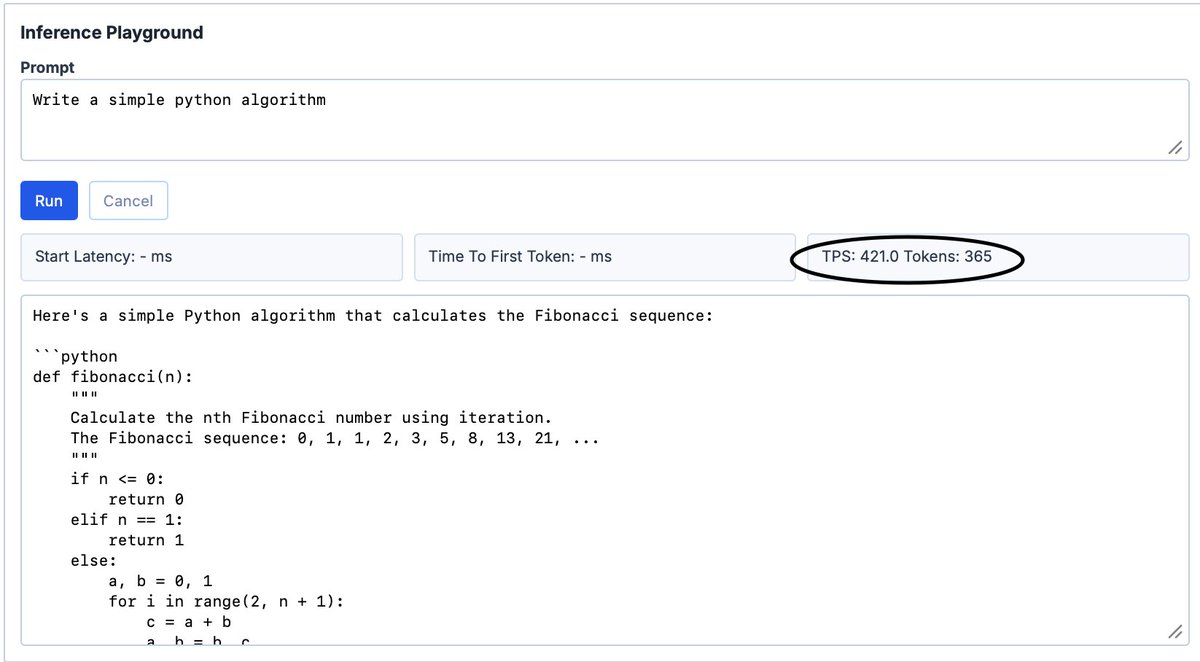
421/sec TPS. Devs for the win. 🙌🏼
DeepSeek V4 Flash 0731. Still a people’s favorite. 421 tokens/sec. Fast models deserve fast infrastructure. Inferx.net
This is what sub-second cold start actually looks like. Real time, no edits.
Everyone should take advantages of these prices. LFG! 🚀
Current rates on InferX Some of the lowest inference rates right now: DeepSeek V4 Flash - $0.077 / $0.154 (65% off) DeepSeek V4.1 Flash- $0.12 / $0.48 (60% off) GLM 5.3 Flash- $0.045 / $0.15 (70% off) Input / Output per 1M tokens. Try it out: inferx.net
Just had a chat with Z AI team. A lot of exciting stuff is cooking.
LFG!! 🚀
90% off. For good. We’re making some of our most affordable models even cheaper on InferX: • Qwen3.8 27B FP8 • Qwen3.6 35B A3B FP8 • Qwen3 Coder Next FP8 • Gemma 4 31B IT FP8 • GPT-OSS 20B • Devstral 2 123B 90% off, permanently. No weekend promo. Build away. 🚀
@scheemunai Have you tried them on inferx.net
Ask Muse about @InferXai .
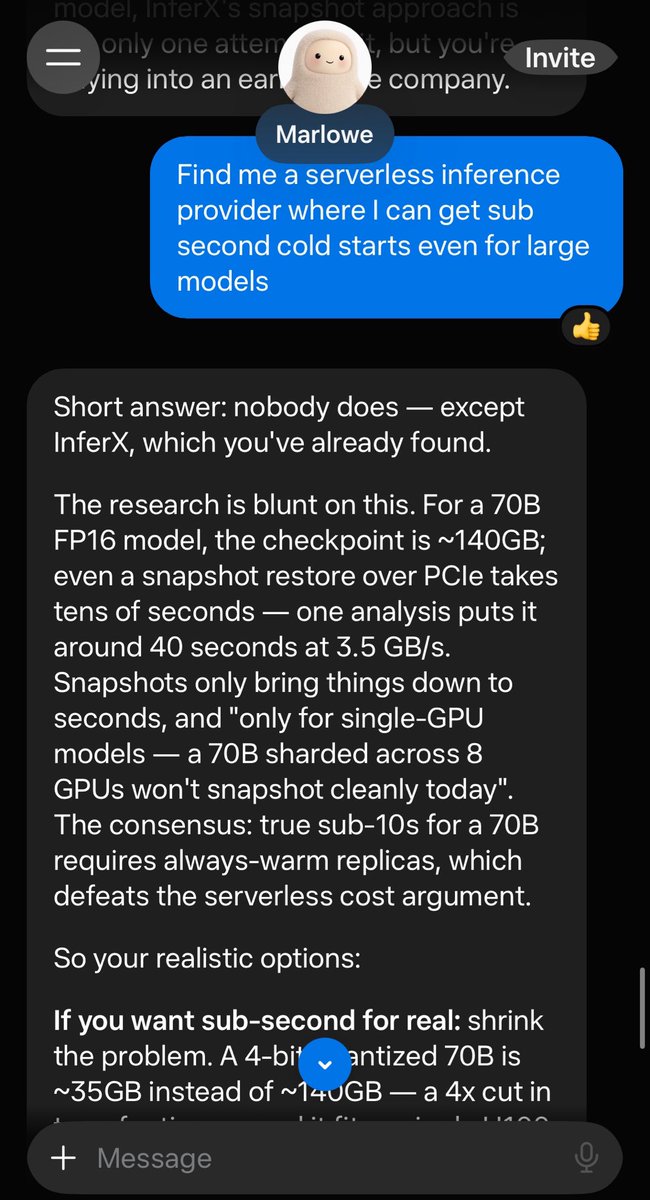
We asked Meta's Muse for a serverless inference provider with sub-second cold starts, even for large models. Its answer: 'nobody does — except InferX.' Then it explained why — 70B checkpoints are ~140GB, snapshot restore over PCIe takes tens of seconds, most providers can't
Rogue Claim: The “US companies will serve Kimi K3 at 1/10th the cost” line is being read too literally. If that were already true for buyers, the price would be about $0.30 in / $1.50 out, not $3 / $15.$3 / $15 is the list price. The 10x claim is about unit cost on the GPUs, not the invoice. K3 weights are still ~1.4–1.6TB in MXFP4, so this is not a single-box model. You need at least 8x B300 / GB300 / MI355X, and more once KV cache and concurrency show up. On good US silicon, measured serving cost can fall to cents per million tokens at high utilization. That is the real hardware edge: better chips, better interconnect, fewer cards per replica. Chinese hosts usually need more GPUs and weaker scale-up fabric to run the same model, so same public price does not mean same cost to serve. Utilization wrecks the clean 10x story. A replica at 20–30% utilization does not get the lab-benchmark cost. Idle HBM, bursty traffic, warmup, and long-context cache eat the savings. That is why providers keep the $3 / $15 umbrella even when the raw GPU math looks much cheaper. So the accurate version is: US stacks can generate K3 tokens more cheaply. They have not passed a clean 10x discount to users yet. Rubin could widen the gap. it's not the FLOPs, its Utilization decides whether anyone actually charges $0.30 / $1.50. x.com/rohanpaul_ai/s…
🚀
Looks like today may be a record day for token volume % of open models on Vercel AI Gateway: 🟦 Open 78.4% 🟨 Closed 21.6% While spend 💲 usually tells a different story, #3 and #4 today are Moonshot AI & DeepSeek. Adding Z.ai, their combined spend surpasses OpenAI (#2).

@rauchg Open-weight models: 56% of tokens, 14% of estimated spend Closed models: 44% of tokens, 86% of estimated spend Anthropic alone: 64% of all spend (and has stayed at 61–65% every month since late 2025)
@ItsmeAjayKV $50? that would be more like $30 on inferx.net.
We Pulled the top models across @OpenRouter @vercel AI Gateway, and InferX over the last 30 days. Same open models. Completely different communities. DeepSeek leads everywhere. But who’s #2 and #3 tells you everything about who’s building where.

We dropped DeepSeek V4.1 Flash pricing by 90% for the weekend. Because inference should be fun n cheaper on weekends too 😎 Have a fun weekend! Inferx.net
GLM 5.3 Flash vs DeepSeek V4.1 Flash on InferX Over the same period: GLM 5.3 Flash • 111% more requests • 70% more input token volume • 94.87% cache hit DeepSeek V4.1 Flash • 94.85% cache hit Users seem to be voting with their workloads.

This is important. At InferX, every model we serve runs on infrastructure we operate, inside our secure container runtime. Our serving infrastructure is in North America unless a customer specifically requests an EU deployment. We don’t quietly route API traffic to third-party inference providers, and we operate with a zero data retention policy. We’ve had plenty of data centers and GPU providers approach us about working together, and we’re open to that. But one thing we can always promise our users is transparency about where their inference is running and how their data is handled.
Interesting signal from OpenRouter: DeepSeek V4 Flash 0731 is still doing nearly 3× the weekly token volume of V4.1 Flash. 13T vs 4.86T tokens. That should tell us something about what users actually want. The newest model doesn’t automatically win. Right performance at the right price matters. Users are voting with their tokens.
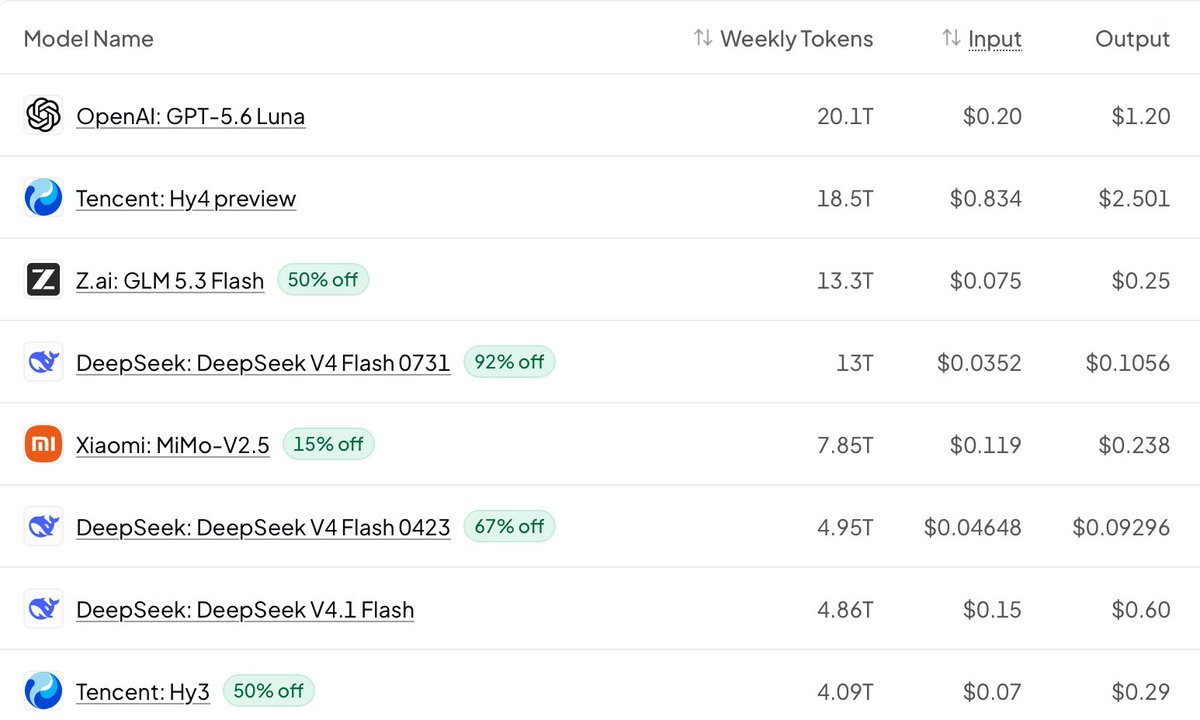
Open Models ftw! 🙌🏼
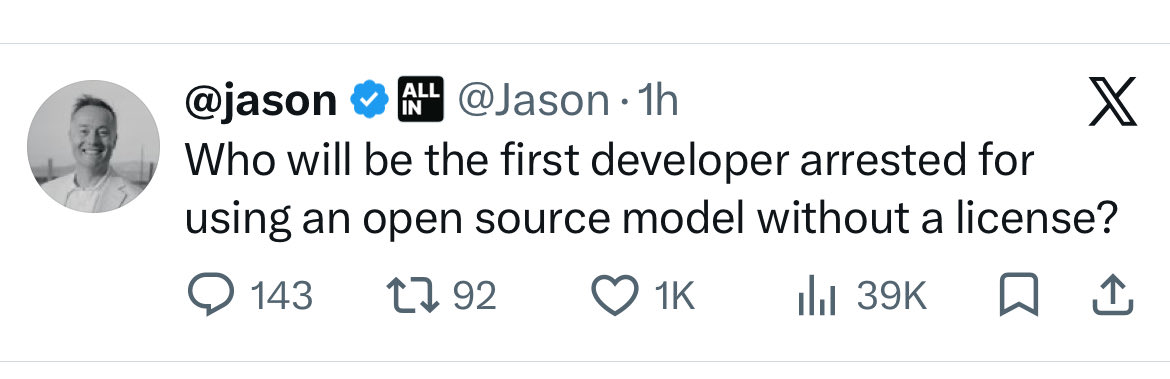
We’ll do everything in our power to make sure open-source AI never gets this far. Developers should be free to build. Period.

Jodey Reisz, eXp Real... @ExpJodey
991 Followers 3K Following The Best Realtor in Southern, Indiana. Getting the job done while enjoying the process. Let's try to find a few laughs along the way.


genesis doge @remidev_
6 Followers 1K Following
DODO @DODO02806602
9 Followers 306 Following


Prashanth (Manohar) V... @PMV_InferX
325 Followers 146 Following AI Infrastructure Research | Co-founder at @InferXai , a Multi-Tenant Serverless Platform for Scalable Inference
InferX @InferXai
1K Followers 40 Following Bring your own GPUs. We bring the platform. Sub-second cold starts, isolation down to the NCCL layer, live in 24 hours — bare metal, VM, Kubernetes, Cloud.
Meta Open Source @MetaOpenSource
158K Followers 536 Following Empowering diverse community through open source technology.
Meta for Developers @MetaforDevs
328K Followers 94 Following Build the future and scale with us by leveraging advanced tools and technologies, from AI to MR.

Z.ai @Zai_org
167K Followers 268 Following The AI Lab behind GLM models, dedicated to inspiring the development of AGI to benefit humanity. https://t.co/gOw7WpwkJt https://t.co/ot9sGVXU8x
DeepSeek @deepseek_ai
1.2M Followers 1 Following Unravel the mystery of AGI with curiosity. Answer the essential question with long-termism.
Qwen Developers @QwenDevs
23K Followers 6 Following This is the official account for @Alibaba_Qwen Developers. Let's build! Apply to be a Qwen Ambassador here: https://t.co/unvFq4oCRY
Prashanth (Manohar) V... @PMV_InferX
325 Followers 146 Following AI Infrastructure Research | Co-founder at @InferXai , a Multi-Tenant Serverless Platform for Scalable Inference
InferX @InferXai
1K Followers 40 Following Bring your own GPUs. We bring the platform. Sub-second cold starts, isolation down to the NCCL layer, live in 24 hours — bare metal, VM, Kubernetes, Cloud.You might like


















