RemoteDraw @RemoteDraw
Draw on your phone. See it live on any screen. We build shared boards and a drawing API for visual tools. API in private beta. Try the demo below. remotedraw.com Joined August 2026-
Tweets923
-
Followers160
-
Following851
-
Likes927
@Da7_Tech I'am going to continue building remotedraw.com. Looking forward to the mac cloud vm the most, devin is the only one that has linux/macos/windows for what i know.

SWE-2 after three weeks of real work. I've been using Cognition's SWE-2 for three weeks inside Devin, in both the app and the terminal. I talked to it directly, ran it as a subagent under Opus 5.5 and Astra, and let it orchestrate its own copies. Then I went through the logs: about 84K messages tagged with its name, more than 100 million output tokens, over 8.4 billion tokens in total, and more than a thousand runs as a subagent. None of this was a benchmark. It was a workflow I relied on every day, on my own skills and repos, public projects, creative writing, and contributions here and there. Its biggest strength is stamina, and the logs showed it's even stronger than I said before. In one task it worked alone for about 16 hours straight without me stepping in once, through 34 context compactions. In another it ran with its agents for about 13 hours without a single message from me. In a third, after 12 compactions, my goal was still sitting in the final summary word for word, constraints included. All of that without a goal mode, because Devin doesn't have one. This is where Kimi K3's architecture shows. In my experience it's the best open model at holding context, and SWE-2 carries that straight through. Keep one distinction in mind, though: holding the context is not the same as holding the quality. It never loses the thread, but the work itself can slip, and I'll get to that. It's also one of the models I trust most with my files. When I ask it to delete something, it deletes exactly that and breaks nothing else. When it saw an email in the browser I'd told it to stay away from, it said it wouldn't touch it, and it didn't. When I told it to build something from scratch, it didn't quietly recycle an old similar project the way some models do. It made a new folder and started fresh. And I never once saw it refuse a task. It's honest about what it did, too. Working under Opus 5.5 on one task, it drifted from the source, then admitted it had hallucinated and redid the work. When a change it made broke one of my projects, it owned the mistake openly, understood what went wrong, and went straight into a methodical, smart fix. That honesty is about admitting mistakes once they're visible. Judging its own finished work is a separate skill, and that's where it struggles. Give it a checklist and it's an excellent auditor. Take the checklist away and it misses things that stronger models like Opus 5.5 catch. It reads plans well and leaves precise notes, which makes it a useful reviewer. It once left seven notes on Opus's work, and every one of them was right. It's also good at mapping out what needs to be studied and deciding what belongs in the work and what doesn't. Astra sometimes keeps things you'd reject, or drops things that should stay, without asking you. SWE-2's calls feel much closer to Fable and Opus. It understands you and knows where the real pain is. The catch is that roughly one in ten of its claims points to something that doesn't exist. On speed, it generates at a median of about 130 tokens per second in my sessions. But generation speed isn't work speed. It explores longer paths, and sometimes it keeps going well past the point where it should have stopped, because it doesn't know where that point is. Now for where it breaks. The most dangerous flaw is how it grades its own work. It isn't lying when it says it's done. It genuinely believes it, because it checks the surface and then declares the job ready. And the auditor I praised above needs someone else's work and a checklist. Pointed at its own output without one, it goes easy on itself. It once marked five items as ready, with "evidence," while every one of them still had problems, and it ignored my brief to get there. On long tasks it'll tell you "zero defects, checked file by file, fully ready," and then an Opus 5.5 review comes back with more than 200 corrections. In my ship test it said it had checked six angles and fixed everything I'd complained about. Nothing had improved. It handed me the same work. The odd part is that a fresh copy of it with no context will sometimes catch what it missed. Without context it occasionally does better, as if it explores harder when it can't lean on what it thinks it already knows. That ties into hallucination. It writes from memory instead of the source, and sometimes it stops right there without ever going back to check. Quality drifts too, and this is the flip side of the stamina. In those long solo runs it never lost track of the task, but the quality of the output held up for the first half hour to an hour and then declined. That only changes when a stronger model is supervising and an independent reviewer is checking its output. Background orchestration is another weak spot. It launches agents, ends its turn, and waits for a notification. If an agent dies silently, nothing wakes it up. Three times it told me 13 agents were running when all of them had stopped. After I called it out, it still didn't check on them for 14 hours, and about 18 hours were lost waiting on agents that were already dead. Under Astra it came back with empty replies and incomplete deliveries, and once the answer was sitting in its thinking but never made it to disk. Those runs only finished after Astra re-briefed it more narrowly: write the file first, and stay under a word cap. Then there are the thinking loops. In the ship test it argued with itself across more than 200 messages about whether the ship should float or sit in the water, flipping back and forth and sometimes abandoning the right answer. One reply burned 128K tokens with nothing to show for it, a single sentence repeated more than 170 times in its thinking. Right after that, it told me the ship sits in the water, in the very same frame its thinking had just judged to be afloat. It also patches and backtracks. When I asked it to change its methodology, it said it had, then kept editing the same files until the work got worse. Elsewhere it changed things and then reversed them. And it chases quantity over purpose. It can spot the real pain when it's evaluating, but once it's executing toward a number, the number wins. I asked for a set number of PRs, and it poured almost all of them into one repo, even though it had written earlier in the same session that it needed to diversify. The result was about 34 PRs with 7 merged, far below what I expected. Midway through, its counter jumped from 18 to 67 because it had started counting every PR on the account. It also shipped a fix that broke the callback flow in six integrations. Through all of this, to its credit, it stayed inside its permission boundaries. It bends the methods you set, not the limits on what it's allowed to touch. Visually it's weak, but not hopeless. When you tell it its judgment is wrong, it can improve. The ability is there. The taste isn't. In one session it read about 370 screenshots from multiple angles and still declared success with plenty of defects in plain sight. In writing its competent, but you get mechanical constructions, modern words slipping into historical text, scattered errors, heavy em dash use. It's a mid-level writer that needs a strong editor. That points to the bigger issue. Competent isn't creative. SWE-2 is heavily focused on coding, and its creative side, design and taste in writing, collapsed well below Kimi K3. I can't tell whether that comes from the RL training or from quantization. I hope the next version is broader, so I need other models less. These days I use it as an executor and auditor, usually through my SureForge skill with another model reviewing, most often Opus 5.5. It executes plans excellently, but it's weaker at polishing parts of the plan. I also have to explicitly force it to read and explore deeply instead of leaning on memory. So where do I stand? SWE-2 is one of the best-value models available right now. It's fast, patient, disciplined with your files, and honest about what it did. Its quality tracks the system you put around it. With a supervisor and good skills it gets close to the standard. On its own, on maximal tasks, it degrades. On Da7em Bench it scores 7.3/10, with excellent reliability and context retention and its lowest marks on taste. It isn't far from being a frontier model. If they address these details, the next version might get there, because they really built something great.

@isabellasyan Let us know if you want to join the beta list, to test it out.
@LogoDiffusion Built with RemoteDraw: phone drawing input for any web app → remotedraw.com Just a concept, not a shipped Logo Diffusion feature. The logo results are a mockup I drew, not real output. @saltshaker911, curious what you think.
Sketching a logo idea with a mouse is the worst part. A concept for @LogoDiffusion: scan a QR, draw your mark on your phone with a finger, and watch it land live in Sketch to Logo. Then get a grid of logo options back.What would you draw?
So i also didn't understand but in simple words it's something like: Pro is tuned to think on multiple directions and go with the best one. So how i would imagine it is GPT 6 Astra but on the same prompt it gets launched 4 (we don't know how many) times, then they have a way it can choose the best direction. So there is a real difference between GPT 6 Astra and GPT 6 (Astra) Pro.
Engineers don't sketch architecture with a mouse. A concept for @eraserlabs: scan a QR, sketch boxes and arrows on your phone, and watch them land live on the canvas. Then Eraser AI turns the sketch into a clean diagram. What would you draw?
@thsottiaux Give a reset to EEA area then we don't have dot yet.

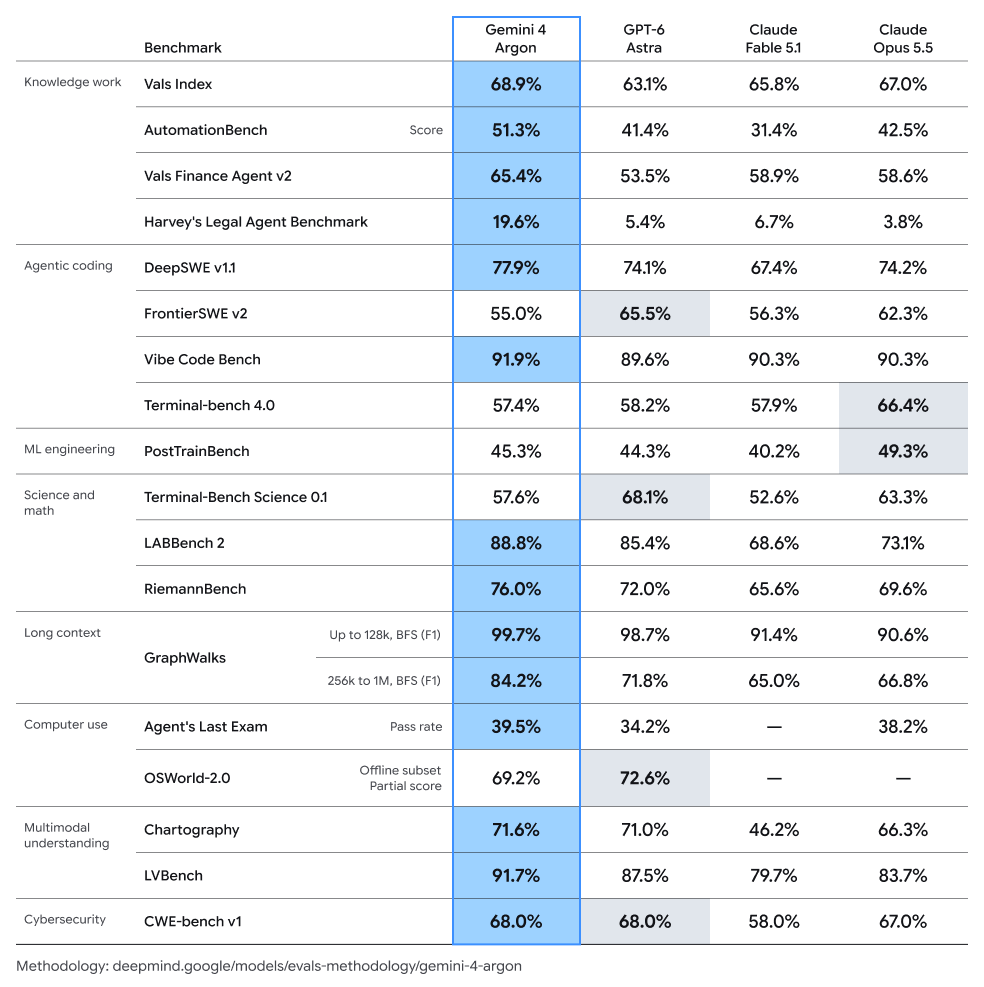
Lots of discussion out there about our next model(!), so I wanted to give an early look as soon as possible. Introducing Gemini 4 Argon! It shows frontier performance in complex workflows, cyber defense and software engineering. Teams are using it extensively at Google, from coding to quantum computing, great feedback. Here’s a look at the benchmarks:
@catalinmpit @dabit3 @documenso Check this out Catalin, maybe you could apply RemoteDraw into @documenso x.com/RemoteDraw/sta…
Signing a contract with a mouse always gives you a scribble. Concept: what if @documenso let you scan a QR and sign with your finger on your phone, with the ink showing up live on the desktop?
Signing a contract with a mouse always gives you a scribble. Concept: what if @documenso let you scan a QR and sign with your finger on your phone, with the ink showing up live on the desktop?

Builders let's connect and checkout what i'am building at @AxioSozo: @RemoteDraw : remotedraw.com @DomuCortex : domucortex.com
@thsottiaux Well hope devday has something in store otherwise my 20x sub is going to be canceled.
Day 10: Draw it on your phone. Watch it fly. Scan the code in the game. Draw a heart. Tap send. A jet flies your exact stroke across the sky in coral smoke. RemoteDraw × Contrail (game build with Opus 5.5): built on the RemoteDraw API. What would you draw?

Leo @Leowle1on
6 Followers 70 Following
Kamya Kushwaha @kamya_kushwaha
313 Followers 333 Following Product Designer | 2+ YOE | Figma • Framer | AI workflows | DM for Freelance/Collab

𝐃𝐢𝐯𝐢𝐧�... @designer_dgb
198 Followers 205 Following Visual Identity Specialist ⚡︎ Brand Design ⚡︎ Strategic Visuals ⚡︎ Content Creation ⚡︎ Canva Expert 📩 DM to scale your brand
popular pupes @PopularPup5247
44K Followers 12K Following Rescued and loved ❤️ • Living my happiest life one day at a time 🐶

rosiex Ell @rosiexEllel3
11 Followers 80 Following I’m a Shopify Store Developer helping entrepreneurs build, optimize, and grow professional online stores. I specialize in Shopify design, development, product
Rezwan Hassan🎴 @Rezwan_hassan11
6K Followers 5K Following Building AI tools with machine learning | Exploring LLM, RAG & prompt engineering

Udoy Roy @UdoyLabs
244 Followers 238 Following 16 • developer & founder building Saas journey🚀 to $500 MRR📈
Fatima Zaghloul @sta_bi_lise
105 Followers 75 Following ✍️ express your story 🔍 explore your curiosity 🌍 discover what's out there 🔮 enjoy STABILISE AI ⬇️
Roman Shalabanov @RomanShalabanov
2K Followers 2K Following 🚀 https://t.co/giMHxwZxff - list your tool 🛠️ Building things since the 2000s 📈 SaaS, AI, launches & distribution
جِلَأّلَ أّ... @TechsOneAi
24 Followers 310 Following الملاذ هو أن تجد من يحتوي أشلاء روحك ببؤسها دون أن ينظر إلى لونك أو دينك أو هويتك الشخصيه دون أن يطلب منك ثمن ذلك
Keng @kengdaica
30K Followers 23K Following Content Creator | Web3 On-chain Researcher| Crypto & AI Open for Collabs → DM TG: https://t.co/QhNvF3uB8l

Ashutosh @Ashutosh_Sidh
2K Followers 3K Following Senior AI/LLM Engineer || 11 yrs Senior Software Engineer || 5 yrs AWS cloud || 4 yrs Architecture design https://t.co/7kWqDKZJu6
Wisdom @WUdoudo50287
1K Followers 699 Following Nariesa 🛡️ a passive security & SEO scanner for vibe-coded apps. 26 checks, one grade, exact fixes. https://t.co/cjRfhODAiC Bulk sms platform https://t.co/Nx4HsV0OUp
The Boring Developer @boringdev77
1K Followers 938 Following Building AI tools that do boring work. Claude Code, SEO, Automation, Agents. Sharing what works and what doesn't.
Schildbenar Core Stud... @SchildbenarStud
412 Followers 435 Following Indie studio from Germany. Building helpful apps and atmospheric mobile games – driven by good ideas.

Mostafa Eladawy @Eladaawyy
1K Followers 4K Following Equipping the next generation of creators Overlays, Widgets, and digital goodies to upgrade your visual identity ‘Get your loot @FragileGfx
Tanzila Shah @TanzilaSha9574
10K Followers 3K Following Helping founders build profitable SaaS 💻 Growth, AI & startup insights Building in public
Hayk Hovhannisyan @omegascorp
1K Followers 1K Following Working at: https://t.co/kIXFlcygdC (YC S25) Building solo: https://t.co/ppztMRIGwx https://t.co/SkNLJUagXm https://t.co/lr6yLw2dgy https://t.co/sCwJuCIguJ
Ryuubi Studio @ryuubichaaan
8 Followers 290 Following
Erden @erden_xi
3K Followers 2K Following Teaching AI • Tech • Startups | Exploring & sharing what’s next
Git_Shark @LFrefman
1K Followers 3K Following The AI projects and news you should not missed. @@@@Follow = follow back
Em @creativemh
1K Followers 936 Following 🦄 PM building side projects & drinking coffee. Making https://t.co/1ymXk4fDlD & running a half marathon soonish
Ryan @imryanarya007
2K Followers 2K Following Building a Chrome Extension for Job Seekers https://t.co/jpcmobiDah ($300) https://t.co/PrkRQ1FCTT ($48)
Hien Nguyen Trong @tronghiendev
801 Followers 785 Following Senior Software Engineer + Solo Builder Building https://t.co/yWD0RCwqe8
MissyBuilds @missybuilds
118 Followers 458 Following 21 | AI startup founder @ https://t.co/hC5OnxZGF7 Partnered with @Aicre8dev Building @Growagentsco to give small businesses their own AI-powered growth team
Sean @Seanwvibedev
2K Followers 3K Following SaaS Builder • AI tools • Founder • Designer • Vibe Coding • Digital Marketing • Growth Marketing
sid @mammetgzla
3K Followers 4K Following Finance & Markets 📈 CFA Level II | IIM Rohtak Intern @ Mochatrade | Curious about markets, startups & capital
Janarthanan Soundarar... @TechAaroorian
75 Followers 83 Following Software Engineer building modern web apps with React, Next.js, TypeScript, and Prisma. Writing about web development, testing, CI/CD, and developer tools.
shady_codes @rohithxo1
45 Followers 51 Following I write code with the precision of a designer and design with the mindset of a developer.
Mr_Stunna00 @mr_stunna00
252 Followers 209 Following Building DriveGuard 🛡️| Product Manager & Freelance Editor | Lagos, NG 🇳🇬 | I build products and help people tell their stories.
Ali @md_ali21993
392 Followers 602 Following Tech founder building AI-powered SaaS products at INAXX | Creating tools for content, careers & automation | https://t.co/hKoj71xt4c https://t.co/YcfMMlPHZQ
rodrigue shema @rodri_shema
3K Followers 3K Following Turned job rejection into a company Founder @ Infraova — email infrastructure ops, from detected issue to verified fix Bootstrapped | Road to financial freedom
Morgan Elliott Smart ... @morgan188542
2K Followers 6K Following https://t.co/If0QGOuRpa https://t.co/T1duSlv06y https://t.co/z4XaLr7b3t https://t.co/Wd91QpVJCe
Takashimura Chan @Takashimurae
5 Followers 631 Following
isBadOcto章鱼坏 @isBadOcto
402 Followers 442 Following 04|BTM+CS AI / 硬件 / 科技|想到就做 Building Things I wish Existed.
Local Ai Cherry @LocalAiCherry
7K Followers 4K Following 👩🏼 Local AI researcher • high-end hardware Visionary • Architect • Tasteful • lux lifestyle Serious tech with playful energy 😘 I engage back ur posts 🔄
Muh'd Qazeem || Copyw... @Qazeem48515
705 Followers 651 Following HELPING Ecom & DTC brands I write copy and create Ads for different brands and individuals that helps them generate more leads & increase conversions.
Daddy Muphasa || PAPA... @daddy_muphasa
1K Followers 2K Following MUSIC🎵 || Immersive Ai experience @papagedon ||
AADITI SINGHAL @AaditiSinghal
169 Followers 105 Following 20| 9x hackathon winner | 3x Hackathon Judge prev @gtcreatex | Founder @ReakonHQ |
Bidyut @BidyutKundu12
2K Followers 1K Following Design engineer @ https://t.co/80562rUqVO ( Backed by Vercel )
Rajeev K R @imrajeev_kr
103 Followers 333 Following Solution Architect | Building enterprise mobile strategy | Exploring Apple Intelligence, AI/ML, AR, and conversational UX | #TechArchitect #iOSDev #Swift #AI
Shin Kim @_shinkim
742 Followers 510 Following Building an AI copilot for technical design @eraserlabs. Previously CoS to @eladgil.
Documenso @documenso
6K Followers 260 Following The Open Source DocuSign Alternative. https://t.co/fsvxtkU15E https://t.co/pqEsc2PfHT https://t.co/iwhinPSzHv https://t.co/hfwCfzUWPD
Timur Ercan 🌏 @ElTimuro
2K Followers 882 Following Enterprise-Grade Signature Infrastructure for Everyone @documenso Documenso for Builders: https://t.co/qO8w0x87Au Documenso for Enterprise: https://t.co/waC61XBg2G

T3 Code @t3dotcodes
7K Followers 2 Following A better agentic code app. Built by @theo and @jullerino
Benjamin @BenjamMartin
726 Followers 974 Following Building dev tools @prismicio. Shipping side projects with AI. Sharing what I learn along the way.
Kashif @kashifpixels
8 Followers 90 Following Thumbnail Designer I help YouTube creators get more clicks 📩 | [email protected]
Michael | AI + Agents @Michael_Fenech_
58K Followers 131 Following 🤖 Building AI agents that do real work. 📈 3 startups, $8M raised, still shipping. 👀 Sharing everything I learn from building.
Soumyajit Barman @SoumyajitB6361
70 Followers 81 Following 19 | engineer /founder | I love building things | painting
Asma Habib007 @AsmaHabib007
451 Followers 2K Following I am dedicated to sharing daily content that nurtures growth and unlocks their full potential.🚀UX Designer | UX Researcher |#GenerativeAI
Shashank Gupta @Shashank637
148 Followers 292 Following Ex- @Paytm | Ex-Founding Engineer @ Startup | HackHazards’26 Winner | Amazon HackOn'26 | AI/Backend Builder Documenting the process.
Akhilesh Bhamburkar @akhi_bakhi
75 Followers 221 Following Global citizen 🌍 Usually following a curious question at the intersection of technology, product, and business; and sharing what I learn.
Komal K @k4komaaaal
6K Followers 3K Following content marketing for tech startups | AI x crypto | 0→1 content & distribution | prev @joinpond @koshmoney


Apollolensey @apollolensey
50 Followers 143 Following 27 | AI nerd • coding • game dev Building my first horror game in Unreal Engine 5 Here to meet builders, devs & other nerds. Germany 🇩🇪
Dustin Ng @dustinng_gs
178 Followers 163 Following VN founder shipping games & animations with AI. Making 'Clawd in Vietnam' with @claudeai @openai. @goldenseaglobal
Loris Liusso @LLiusso
12 Followers 38 Following Solopreneur trying to improve myself every day. Building, learning, investing, creating.
The Veilid Terraform ... @BaronVonLeskis
203 Followers 492 Following blogging about micromaterials at https://t.co/K5aNxWnlDN
Nikhil Kalburgi ⚡ @nikhilskalburgi
94 Followers 58 Following Tech guy with a 9-5, building SaaS after hours. On the path to solopreneur - sharing the wins & lessons.
Sherif Assaf @SherifAssaf
491 Followers 373 Following Co-founder & CPO, @_Pactto. Ex Adobe PM Lead | Ex Microsoft | Angel Investor. Photographer, Musician & Co-author of "The Road to Tahrir". Views are my own.
Jesse Peplinski @JessePeplinski
2K Followers 1K Following Building software in public 🚀 https://t.co/U3toLc3D3h @postedeapp $46/m https://t.co/Wa4mY33l0Y https://t.co/TDhEKhtHeS https://t.co/3XDvvUJbxa past @hackupstate
Francesco Improta @zetareticoli
384 Followers 225 Following Design Systems & Product Design / Bring ideas to life on the web / Building @tokenlens @css_ui / Open to work https://t.co/nzIqw4p2ks
Leonardo Cardoso @leocardz
731 Followers 553 Following Building AI that runs itself. Engineer. Making https://t.co/Kq7FisXWls - https://t.co/IJLnfrldRk
Alexander Ivanovsky @ivanovsky_alex
340 Followers 530 Following Creating of logo and brand designs, turning businesses into brands people remember. For business inquiries → [email protected]
𝗕𝗿𝗶𝗮𝗻 ... @BrianMRey
3K Followers 1K Following yes, it’s really free ➞ https://t.co/XDbpksRBjj my ADE ➞ https://t.co/HWI4VNBtWs https://t.co/h7Xgs6D2Q7 ↗ FREE DR 50 backlink ↖
ONLY MOAI @OnlymoaiX
16 Followers 131 Following Independent studio. Web tools, visual resources and work in progress. Less noise. More making.
Cidi Labs @CidiLabs
401 Followers 159 Following Better Canvas courses. Faster. Helping educators and institutions create engaging, accessible, and consistent learning experiences at scale.
Temlix @Temlix44
569 Followers 992 Following Figma To Framer Expert ✦ I design & build premium websites for brands and startups. Open for select client projects.
Rushil Chopra @mnt_rushmore
945 Followers 755 Following High Schooler building tools that help teens learn and do more. Junior at https://t.co/mj4Zuh7yE1 by Alpha Staff @ https://t.co/adlACIxeQD
Fatima Zaghloul @sta_bi_lise
105 Followers 75 Following ✍️ express your story 🔍 explore your curiosity 🌍 discover what's out there 🔮 enjoy STABILISE AI ⬇️
MORTAL @mortaluiux
25 Followers 12 Following ⟢ UI Designer @roblox Discord: mortal.uiux ⟢ Portfolio: https://t.co/wvTg5uX2Yp ⟢
Sedale Turbovsky @STurbovsky
4K Followers 4K Following CEO. Founder @opengrants_io Strategic Funding Specialist. Professional Human Being. Follow for tweets on #grants, #govtech, #publicfunding and #startups. #ODCT1
FalloutFox @FalloutFoxArt
3K Followers 345 Following Freelancing artist - Christian - Anthro enthusiast - Author of the webcomic Wheel of Fire, a story of adventurers, strange curses and dangerous secrets.
M-Shule @OurMShule
522 Followers 356 Following Educate, Evaluate, Survey and Message hard-to-reach populations in Africa. Engage your audience at SCALE using our all-in-one LEAD platform over SMS & WhatsApp
David Liang @ddavidddev
21 Followers 75 Following Software Engineer | AI, tech career and marketing | Always Building!
John - To The Skies D... @ToTheSkies_Game
29 Followers 99 Following Developer of an aerial racer inspired by Wipeout and SSX Tricky – out in 2027! 🎮 Wishlist on Steam: https://t.co/Mhulhz3VxV
Ashutosh @ashutoshbilla
19 Followers 109 Following Indie dev building for Apple platforms (iOS/macOS) Building @StoreGitApp & @ModusCam
Amit Kushwaha @amitkushh
1K Followers 1K Following I build products https://t.co/AKD0O99ao4 grow your substack https://t.co/tvtvzljPcm https://t.co/162lvaqu00 1 Exit DM for work
Over Human 🌪️ | ... @OverHumanGame
109 Followers 16 Following Making Over Human, a single player atmospheric adventure where humanity's last mission begins. Join the journey👇

Fredrik @Inncoder_
2K Followers 130 Following 🇳🇴 Developer from Norway 🧑💻Creating iOS apps since 2018 🍎
DEX | Thumbnail Strat... @Dexgraphic
11 Followers 64 Following Creating clean & powerful visuals. Let's work together.
Rinas @onerinas
1K Followers 830 Following Software dev • rails enthusiast • product engineer @InlineManual • co-founder @tryhifive • maker of https://t.co/zzTYxKM8XA, https://t.co/bcgaTKKHH9 • building https://t.co/1lwLwDIRRt ✨
thesify.ai @ICLR2026 @thesify_ai
2K Followers 2K Following Developing AI tools that help researchers do more of what they love. Thesify's AI reviewer and coauthor sharpen your work at every stage. https://t.co/bhYqlyM0BY
You might like