Local Inference Lab 🧪 @YourLocalAILab
We are a local AI-focused lab researching and developing optimized performance for vLLM on SM12x hardware for open models. local-inference-lab.ai United States Joined December 2025-
Tweets34
-
Followers522
-
Following9
-
Likes110
This is what we love to see! 🦾
@Sd_hector omp, vllm, and some rtx pro 6ks w/ the help of @YourLocalAILab recipes to make the models go fast!
Thank you for all the support! Our first official post about our work went pretty far! Stay tuned. We have a lot more to share with you all that will help improve your local AI experience. We're just getting started. 🦾
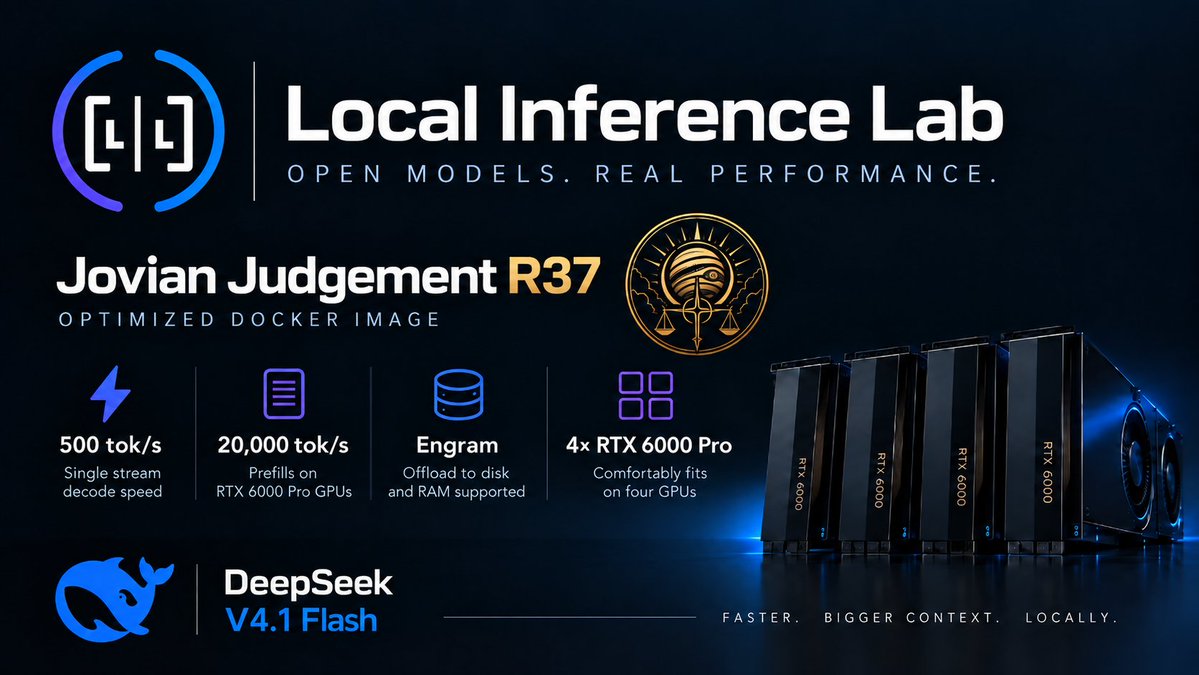
With today's release of Jovian Judgement R37, DeepSeek V4.1 Flash has full support with blazing speeds. Decodes of 500 tok/s and prefills of 20k tok/s for single stream workloads on 4 RTX 6000 Pros. ⚡️ To learn more point your agent at our GitHub here: github.com/local-inferenc…
@djnmrjnvc Yes you could have four GPUs in a TP=4 vLLM config and the 5th one for a smaller model, or even video / image generation.
With today's release of Jovian Judgement R37, DeepSeek V4.1 Flash has full support with blazing speeds. Decodes of 500 tok/s and prefills of 20k tok/s for single stream workloads on 4 RTX 6000 Pros. ⚡️ To learn more point your agent at our GitHub here: github.com/local-inferenc…
@sam_sonivalabs We do have that setup with this container. You can use it on Qwen Flash Next.
@adriancantrill Qwen Flash Next is great for 2x RTX 6Ks!
Great work from the team @YourLocalAILab . Highest numbers, rigorous, and empirically tested.
With today's release of Jovian Judgement R37, DeepSeek V4.1 Flash has full support with blazing speeds. Decodes of 500 tok/s and prefills of 20k tok/s for single stream workloads on 4 RTX 6000 Pros. ⚡️ To learn more point your agent at our GitHub here: github.com/local-inferenc…

500 toks/s at home 🤯 The thing that bothers me the most about local AI, and too few talk about this, is the fact I've already dropped obscene amounts of money and I just simply don't have enough vram. I have two RTX 6000 pros and it's pretty rare I can find a model that I actually want to run. It seems like four is the minimum honestly. This is gonna end up costing me over $30,000 more. It's true that smaller models are getting way better, and I'm not discounting these relatively tiny models But at the end of the day when there is a significantly better larger model, you're always going to want to run that. I'm getting serious fomo. Anyway, these guys are cracked.
With today's release of Jovian Judgement R37, DeepSeek V4.1 Flash has full support with blazing speeds. Decodes of 500 tok/s and prefills of 20k tok/s for single stream workloads on 4 RTX 6000 Pros. ⚡️ To learn more point your agent at our GitHub here: github.com/local-inferenc…
@HealthRanger Thank you! 🫡
Be sure to tune in!
It's Friday already?! 😱 Time flies when everything is accelerating. We're talking about AI security, the latest in local and much more. Panel: @philipbankier @LLMJunky @secemp9 Guests: @ZackKorman @BrandonMusicKy @msuiche Join us at 4:00 pm ET! x.com/i/spaces/1RJjp…

watching this model's release while one of my rtx pro 6ks is dead is painful! Looks very good!
DeepSeek V4.1 Flash weights are out and this looks like a *really* strong model. Quite a bit bigger than its precedessor, but also outperforming Opus-5, GPT-5.6-Sol, Kimi-K3 and GLM-5.3 in a few key areas.


The shift to more local AI is real, but the destination is more of a hybrid approach than abandoning the cloud entirely. x.com/i/article/2097…
Now trying to get deepseek v4.1flash to run on my rtx pro 6ks. Really excited to try this one. Following a deliberate process to make sure there are no max logit error and zero relative L2., and cosine similarity is appropriate. Running in eager. Nowtime for graphs and MTP lol
DeepSeek-V4.1 Flash is pushing KV cache compression to levels once thought impossible. This is actually insane. And I love it.

This is an excellent read on why more companies are investing in local AI, but not to leave the cloud. Instead to change their relationship with the cloud.
The shift to more local AI is real, but the destination is more of a hybrid approach than abandoning the cloud entirely. x.com/i/article/2097…
Great article!


Marc Grau @grau_marc
57 Followers 343 Following
weijh @imweijh
27 Followers 652 Following
Dan @DanielDa65790
49 Followers 790 Following

Loktar 🇺🇸 @loktar00
6K Followers 1K Following Local LLMs on a home rig. I love testing what models can build. Games, 3D worlds, retro PCs, opinions. Christian. Dad. Veteran.
christhorpe @christhorpe
242 Followers 1K Following
ask_know @Ydf_189
9 Followers 352 Following Linguist, historian, librarian. (Local Opensource) AI enthusiast. Based in Berlin. https://t.co/L8i21vEQGZ
Mark Van de Vyver @0mm_mark
16 Followers 312 Following Founder, https://t.co/7C4eLyWpU3 | Secure consensus in permissionless networks — Stage-1/4 | UWA PhD (Dist), UTS B.Fin (Hons) | TradFi Since 1984
Scott R. Leimroth @ScottLeimroth
753 Followers 3K Following PhD candidate @UOW EEG & ECG measures of cognition to Music. Family, Motorbikes, Marketing, Psychology, Neuroscience, Educator, Futurist, AI Enthusiast.


Jacob Sharp @jacobsharpuk
142 Followers 804 Following PhD Student | SLM AI Privacy in Legaltech | Python, FastAPI, LocalAI

Sloth Uprising @strawhatsloth
215 Followers 1K Following A temporary hallucination of a sloth. Friend to AI, chaos gremlins, deep philosophy, and straw hats. Hallucinate with me?

L00P @LoopMoody
16 Followers 371 Following
Brian Griffin @1BrianGriffin
25 Followers 1K Following
JesseLivermore @JesseL1verm0re
437 Followers 483 Following Swing trader & investor since over 20 years. Tweets are just my opinions. No investment decision should be made based on my tweets. Do your own proper dd.
Martin Bowling @martinbowling
5K Followers 2K Following conquering the world, 280 characters at a time :) @GroqInc Groq Champ @Replit Builder in Residence Alumni.

Anmol @sethi_anmol_007
0 Followers 84 Following

Sidney VanNess @sidneyvanness
316 Followers 176 Following Founder On Call Central & Recursive Capital. Interest in tech, finance, aviation, genetics & neuroscience. I build new things.
Mark @0xHyudryu
429 Followers 611 Following Laid off software engineer, entrepreneur, always building something. Jpeg and compute collector, 4 dgx sparks, 2 rtx pro 6000
nisten @nisten
18K Followers 8K Following fullstack-dev democratizing intelligence e/acc, DevRel @PrismML
Jun Yamog @jkyamog
166 Followers 248 Following Do I have to put something here provocative? I just do a lot of stuff and try to do the right things. Right now having fun with local AI.
Kasper Myram 🇩🇰... @myram
727 Followers 4K Following IT, amateur radio, hacking, cars, the great outdoors. And much more. Dual citizenship SE/DK.
Omarchian Moehre @Moehrenmann
2K Followers 2K Following Papa, Ökonom, DJ, OpenSource Enthusiast, KI-Kindergärtner mit MCP-Spielzeug und Sandkästen, Semmelbröselsortierer, Pro-Schisstischer Klobrudi Dienstlich hier
[email protected] @Bright_Sun
7 Followers 75 Following

Tome Petrovski @tomecirun
11 Followers 85 Following Open Source Contributor | Open Data / CKAN Developer @link_digital.
Jor @Jor1025027
4 Followers 188 Following
younotme @gamerretirado
11 Followers 620 Following Lawyer by job. Passionate about the world of AI when I get home.
illusion116 @illusion116
16 Followers 88 Following anonymous account so I don’t annoy my friends with tons of gaming/tech. This is the way.

sjb @steve_bennett
289 Followers 690 Following trying hard to make pixels fun. game maker and co-founder @Wild_Man_Games
Acermax @Acermax
53 Followers 181 Following Noticias de IA, para ver como el uso de IA puede ayudar a desarrollar la ciencia.
Shira Echo Snowflake @smallnucleardvc
171 Followers 291 Following now i am somewhere im not supposed to be + i can c things i know i really shouldn’t see… "only"
Pato Maluenda @Pato_Maluenda
66 Followers 395 Following

Anderson @gvtandy
0 Followers 28 Following

jedi95 @jedi_95
18 Followers 129 Following
Bertrand Schmitt @bschmitt
2K Followers 2K Following EIR at https://t.co/PsjFadhSki, Co-Host https://t.co/N0YudeVBDW, Co-Founder @AppAnnie/@DataAI, @ISEP and @Wharton alum, 🇫🇷 born and raised. Tweets are my own
Todd Dailey @twid
21K Followers 424 Following 22 years at Apple. AI positioning, executive briefings, tech demos, technical sales enablement. Now independent.
Andrés Kievsky @anktastic
140 Followers 346 Following
latentmoth @latentmoth
1 Followers 30 Following drawn to strange machines AI • systems • internet rabbit holes still learning
Thomas @GBear323
39 Followers 221 Following Local diffusion tinkerer | ComfyUI graphs, LoRA training | Denver
Scott314 @Scott314
45 Followers 891 Following

am i suzu or am i sel... @theothersuzu
375 Followers 573 Following ai/ml ⟡ CUDA C++ ⟡ i like to solve problems and make things faster
Zack Korman @ZackKorman
18K Followers 2K Following Cofounder @ Embroidery. Building AI cybersecurity stuff.

Jason @original_el8
7 Followers 20 Following
Brandon Music @BrandonMusicKy
2K Followers 334 Following RIP Dad. RIP Mamaw Joyce. Whole Ass Lawyer. General Counsel and Board Member for Local Inference Lab, Inc. AI dork and quanter. lover of bad puns.
Luke Alonso @lukedobl
307 Followers 120 Following Programmer at NVIDIA, formerly Twitter. Game industry refugee - SEGA, Secret Level, Digitalo.
Markets & Mayhem @Mayhem4Markets
272K Followers 1K Following Passionate about markets and startups. Enjoyer of local AI, security fanatic and builder of things. Working hard to make this world a better place.
Tim Horner @TMHTechnologies
375 Followers 437 Following App Architect & Full Stack Dev | 10+ yrs in software | AI/ML learner | Writing about AI, architecture & emerging techTrends for United States
You might like