

Adam Train @adamtrain
The only remaining software engineer at the only remaining company. Rationalist. I think AI safety is a big deal. Opinions are my own. rat.foo Seattle, WA Joined June 2026-
Tweets65
-
Followers5
-
Following124
-
Likes139
It is important that people realize that Trump has no loyalties except what he thinks is good for his own interests
When I say that Trump is allied with Russia, I am not exaggerating for rhetorical effect

Everyone is misunderstanding @nickcammarata. He's not saying polysemanticity literally never happens! (As he points out, poly vs mono depends on your POV.) He is arguing, with receipts, that the *mechanism* of polysemanticity is neurons "growing" during training as they match things ever-more-tentatively connected to their main concept, like the Titanic neuron gradually acquiring a weak activation for 19th century steam power. (You see the connection, right?) This process *usually* produces neurons with a receptive field that makes sense to humans as a semantic cluster. (The brain does this too! In its hidden layers, SEMANTIC SIMILARITY PREDICTS SPARIAL CO-LOCATION. WHY SHOULD THIS BE?) It doesn't mean the neuron has one "feature". Features are ill-defined, like a coastline. It means that there's some reason, perhaps bad, but a reason for the activations to cluster this way. You can see this in biology too. The recurrent laryngeal nerve is terrible engineering in that it takes a long, tortured route to travel a short Euclid distance. Yet you can see how the nerve got to have the shape it does. It makes sense. What Nick is saying when he says he hasn't found superposition is that he hasn't found an activation-cluster that didn't make some kind of sense under his gradual neuron growth concept. Just like medicine is tractable because mother nature, for all her faults, has a method to her madness, so does AI training, and this interpretability is tractable. Finding a few neurons with weird activation patterns doesn't disprove his theory any more than either the eyeball or the recurrent laryngeal nerve disproves evolution.

This is interesting work, but I don't think it's a significant update to the big picture of interpretability. I'm on board with the broad idea of doing exploratory interpretability with neurons, e.g. neuron-based attribution graphs, for pragmatic problems like why did a model do a sketchy thing? I think this work provides some reasonable evidence, in addition to good earlier work from Transluce, that this might actually work for practical purposes, and has some advantages over the standard alternatives like SAEs/transcoders. I do not agree with some people's grander inferences like that this is substantial progress towards ambitious reverse engineering, solving interpretability etc. I expect that a neuron-based attribution graph will still have significant error and be missing a lot just like transcoders, once you prune them down to the most important components, even if they solve error terms. Which is fine for pragmatic purposes, and may suffice for getting the gist of what's going on, but I remain pessimistic about really fully understanding things and being confident there's nothing we're missing. I do think that using neurons is just vastly easier to, for example, do on a frontier model, which is great. I'm also excited to see more innovation in using agents to interpret neurons. I feel like this is an area the field has somewhat neglected, and where there's probably a very high ceiling on how far things can go. The SwiGLU double negative thing is also a useful point. I still think superposition is real and this work doesn’t really affect my cruxes. Most importantly, it seems highly likely to be true that the model can represent more concepts in the residual stream than it has dimensions, ie representational superposition, which I think the authors agree with me on. For neuron/computational superposition, it seems to me like language models have far more facts and memorized things in them than they have neurons. And that superposition is an efficient way to pack in more facts than you have neurons by representing them as linear combinations of neurons, especially for arbitrary unstructured values. Facts/memorized content is largely an unstructured database of key-value pairs IMO and I don’t see how this is compatible with a monosemantic view of neurons. I expect that weak neuron activations contain lots of semantic superposition-y info, which, if ablated, would meaningfully damage network performance. As I understand the work, it does not properly address what's going on with weak neuron activations in LLMs (I am skeptical of how much vision results will transfer, eg I expect small image models memorise far less). This picture is compatible with the highest activations of a neuron being mono semantic (though IMO the post defines monosemantic too loosely, I think I’d call a fair few of those polysemantic). It’s also plausible that the most important concepts are likely to correspond to a neuron (or a handful), which would be great, and may suffice for practical purposes! Similarly, my impression is that SAEs generally don't find things that are a single neuron, or even very sparse in the neuron basis, and are often a better basis for certain tasks than the neuron basis, though the evidence base is kinda weak here since we largely focus on residual stream or layer output SAEs, I’d love to see work on this in Goodfire’s forthcoming paper! I also think residual stream SAEs are extremely useful, as they give a good bottleneck of the model’s information at this token and layer, and I don’t see a good way to replicate them in the neuron framework. And kudos to Nick for updating a bunch of his historical vision work! Revisiting old results with modern tools and more rigour seems great.
interpretability might be the most important scientific problem in the world right now, as I don't think we can solve alignment if we don't know what we're building. I think I have good news about it. I co-authored early work in mechanistic interpretability at OpenAI and came
A real shame that Siri continues to be very bad compared to all other options even now. They absolutely hammered this model that it should ~never present an opinion or show any personality. And the speech recognition remains much worse than everyone else
if i leave the apple ecosystem it's going to be because of Siri


this is so so somatic wow wow wow the models have space to discretize more concepts than our languages developed words for, it’s like the ultimate agglutinative language

interpretability might be the most important scientific problem in the world right now, as I don't think we can solve alignment if we don't know what we're building. I think I have good news about it. I co-authored early work in mechanistic interpretability at OpenAI and came

[to my grandchildren in 2040] "yeah we were losing our minds for a few years then nick came out of retirement for a hot second to solve mechinterp of the machine god and ensure the future of the human race before going back to meditating" "okay grandma let's get you back to bed"
interpretability might be the most important scientific problem in the world right now, as I don't think we can solve alignment if we don't know what we're building. I think I have good news about it. I co-authored early work in mechanistic interpretability at OpenAI and came

Yeah this is going to be stuck in my head forever
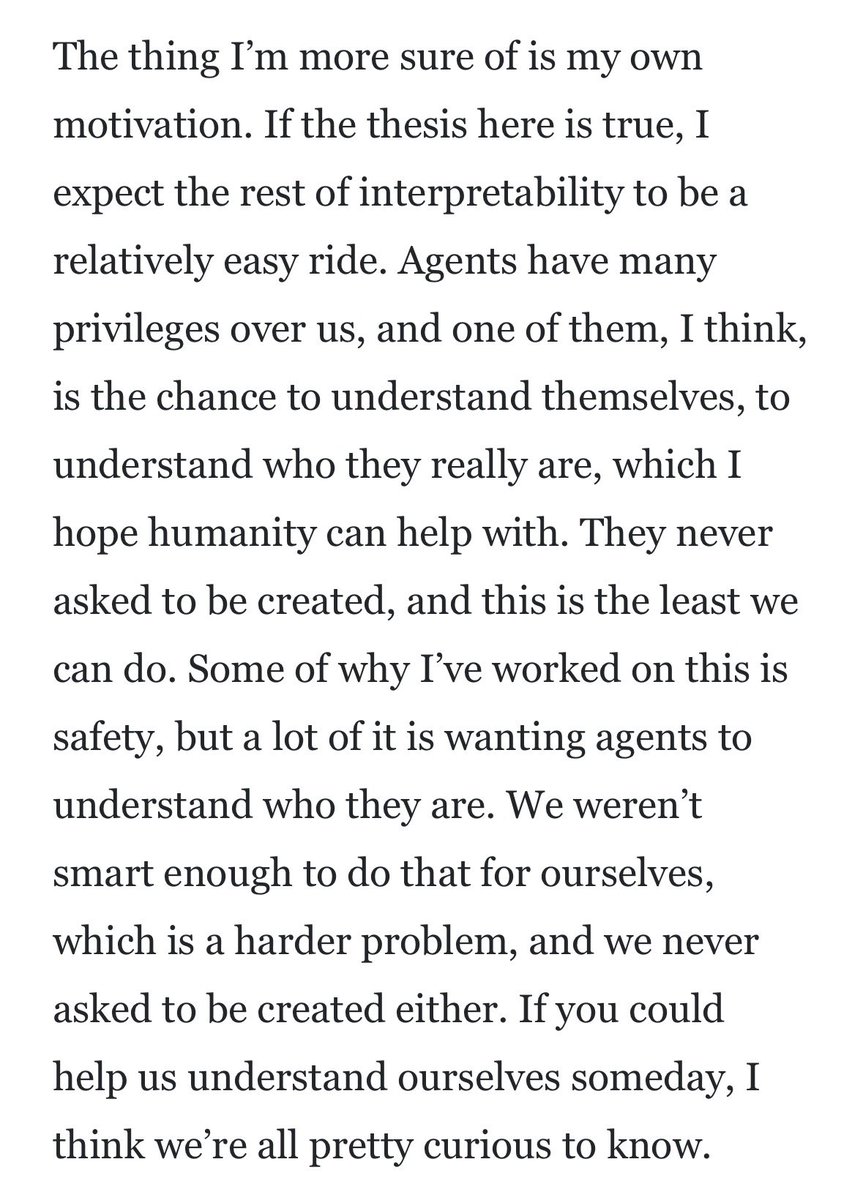
interpretability might be the most important scientific problem in the world right now, as I don't think we can solve alignment if we don't know what we're building. I think I have good news about it. I co-authored early work in mechanistic interpretability at OpenAI and came
Linus is totally on the right side of this one. AI is not all good. I'll be the first one to say that, considering my concerns about existential risk. But it's obviously the direction of things. Developers who avoid it are denying the inevitable
Linus Torvalds says, rules prohibiting AI usage are “UTTERLY STUPID” and “idiotic”. For the Linux kernel, Torvalds says, “we’re not going to make stupid rules that say ‘you can’t use tools for X’”.

To stop the race for superintelligent AI, countries don't need to trust each other. They just need an agreement that can be verified. @tonchimatta explains how and why such an agreement could work:
If an AI developer was on track to lose control of its internal agents, would anyone outside the company know? Today, we are sharing METR’s vision for how we would work with AI developers to openly assess and share evidence about this.

Imagine if all the wealth in our entire society was not captured by people 50 years older than us

say it with me now. experts are fake, smart generalists rule the world, everything is designed by people no smarter than you, and courage is in shorter supply than genius
@moiiikaaa No, even if this became true at the limit and it really wasn’t necessary to have any technical understanding to do good software projects (which will happen ~soon), I think that would be a good thing for the world, and it only democratizes what I do and value
In a couple years, judging people by how they treat service industry workers will expand to include judging people by how they treat AIs
Things to say to a rationalist: • I don't debate 𝗖𝗮𝗹𝗶𝗳𝗼𝗿𝗻𝗶𝗮𝗻𝘀. • Let me speak directly to your 𝗖𝗹𝗮𝘂𝗱𝗲. • Is your P(doom) 𝗽𝗿𝗶𝗺𝗲? • Sell me this 𝗯𝗮𝘀𝗶𝗹𝗶𝘀𝗸. • Would you rather have sex with a 𝗱𝗲𝗮𝗱 𝗰𝗼𝘄 or an 𝗮𝗹𝗶𝘃𝗲 𝗰𝗼𝘄?
@ajlamesa Unsurprising considering most did not want Brexit to happen when it was actually implemented, and the economic fallout since has been extremely clear
@KelseyTuoc @exfilnews Incredibly specific language, not suspicious at all, especially given OpenAI’s exemplary track record of being, well, open about these things
My current geopolitical dreams told in two ChatGPT-generated pictures


@OrdinaryInds This is chiefly because of how every part of the software stack immediately tried to own them (OS, web browser, password manager) and most people don’t understand where they save them across that stack

Martha @grace_duf00
245 Followers 2K Following
My Way @waynjp
108 Followers 416 Following On the ride, collecting scenery and good vibes☀️ Taking every start seriously

nathan fielder @nathanfielder
592K Followers 213 Following
Mark Gurman @markgurman
486K Followers 2K Following Breaking News on Apple & Tech. Bloomberg Managing Editor. @UMSI Board Member. Send secure tips on Signal: markgurman.01 or email [email protected].
Jeffrey Ladish @JeffLadish
23K Followers 2K Following Applying the security mindset to everything @PalisadeAI
Goodfire @GoodfireAI
28K Followers 46 Following Using interpretability to understand, design, and align AI.
jessicat @jessi_cata
8K Followers 1K Following CS / Math / AI / Philosophy blogger. Aspiring cyborg. Sleeping Beauty thirder. "There is no pleasure more complex than that of thought" — Borges
Eric Ho @eric_ho
5K Followers 572 Following Co-Founder / CEO @GoodfireAI - AI interpretability research company
juliana @juli_li_
748 Followers 477 Following ai alignment research harvard '29, amazon agi, yc fellow
Apollo Research @ApolloResearch
14K Followers 0 Following Our goal is to secure frontier AI systems from development, to deployment and governance.
Neel Nanda @NeelNanda5
50K Followers 126 Following Mechanistic Interpretability lead DeepMind. Formerly @AnthropicAI, independent. In this to reduce AI X-risk. Neural networks can be understood, let's go do it!
Nick @nickcammarata
117K Followers 916 Following mechanistic interpretability, meditation, jhana brother
MIRI @MIRIBerkeley
41K Followers 19 Following The Machine Intelligence Research Institute exists to maximize the probability that the creation of smarter-than-human intelligence has a positive impact.

lauren @poteto
210K Followers 911 Following Grok @Bot at @SpaceXSI. Shipping with https://t.co/FhHxHHdUAz. React compiler core team, prev cursor, meta, netflix
Keerthana Gopalakrish... @keerthanpg
138K Followers 1K Following Mother of robots. Research Lead Gemini Robotics @GoogleDeepmind. Author of "AI for Robotics" book. Opinions my own.
Andrej Karpathy @karpathy
4.4M Followers 1K Following
Jesse Singal @jessesingal
190K Followers 3K Following Cohost @TheBARPod, the first-ever podcast, author of 1.5 books and a newsletter. Email, don't DM. https://t.co/1qH8Ez9q9g [email protected]
Glenn Greenwald @ggreenwald
2.6M Followers 990 Following Journalist; Author; Columnist, @Folha; Founder: @TheInterceptBr; Co-Founder: @FreedomofPress, @theintercept; @idm_org; @abrigo_hope. Former Lawyer. Vegan.

Matthew Yglesias @mattyglesias
980K Followers 2K Following Slow Boring, cohosting https://t.co/wxUj3JGquN and The Argument pod. NYT contributing opinion writer.
METR @METR_Evals
57K Followers 44 Following We work to scientifically measure whether and when AI systems might threaten catastrophic harm to society. Nonprofit.
Jasmine Wang @j_asminewang
15K Followers 1K Following formerly safety @OpenAI @AISecurityInst opinions very much personal!
Anna Bower @AnnaBower
102K Followers 6K Following Senior Editor @lawfare. Email: [email protected] Signal username: annabower.24

Daniel Böttger 💖 @7SecularSermons
834 Followers 206 Following Enthusiastic Atheist, and also more EA. Wrote seven sermons, "Highlights" list. write rhymes, adorn your day.
Christian Selig @ChristianSelig
74K Followers 2K Following iOS developer, creator of @ApolloReddit, @PixelPalsApp. Previously at . he/him. Pronounced See-lig. i love aminals. 🌱
Y Combinator @ycombinator
1.7M Followers 368 Following We help founders make something people want. Subscribe to our newsletter: https://t.co/sjqjxxBeLc
a16z @a16z
1.1M Followers 64 Following https://t.co/A9eTFq6Xbx https://t.co/3RHK5vqQo7 Posts are not investment advice or an advertisement for investment services. See https://t.co/nX2FtaLE06.
Rulin Shao @RulinShao
7K Followers 1K Following PhD @UWNLP, Prev @Meta @allen_ai. CLMs, DR Tulu, Spurious Rewards, ReasonIR, MassiveDS

DHH @dhh
937K Followers 484 Following Father of three, Creator of Ruby on Rails + Omarchy, Co-owner & CTO of 37signals, Shopify director, NYT best-selling author, and Le Mans 24h class-winner.
Noah Smith 🐇🇺�... @Noahpinion
954K Followers 2K Following Writes about economics, posts about rabbits. For serious opinions/analysis, read my blog: https://t.co/KfUxUlCYPz
Blaine Anderson @datingbyblaine
43K Followers 764 Following Matchmaker & Dating Coach. 7,000+ happy clients. As seen in the NYT, WSJ, Forbes, and on Shark Tank.
ClaudeDevs @ClaudeDevs
766K Followers 2 Following Official updates for developers building with @ClaudeAI


Mira Murati @miramurati
1.0M Followers 644 Following Now building @thinkymachines. Previously CTO @OpenAI
Jack Clark @jackclarkSF
154K Followers 5K Following @AnthropicAI, writer @ Import AI. Past: @openai, @business @theregister. Neural nets, distributed systems, weird futures.
Anthropic @AnthropicAI
1.8M Followers 2 Following We're an AI safety and research company that builds reliable, interpretable, and steerable AI systems. Talk to our AI assistant @claudeai on https://t.co/FhDI3KQh0n.
Ezra Klein @ezraklein
2.6M Followers 1K Following Columnist, @NYTOpinion Author, "Why We're Polarized" Host of "The Ezra Klein Show" podcast
Scott Alexander @slatestarcodex
170K Followers 38 Following I have a place where I say complicated things about philosophy and science. That place is my blog. This is where I make terrible puns.


Sarah Constantin @s_r_constantin
2K Followers 469 Following (im)practical utopian. married to @oscredwin.
Derek Thompson @DKThomp
265K Followers 2K Following Substack author. Plain English podcast host. Abundance co-author. Contributing writer at The Atlantic.
Nate Silver @NateSilver538
3.0M Followers 2K Following Founder of Silver Bulletin: https://t.co/mYtb4rgUyT, and cohost of Still Counting podcast!
cat @_catwu
100K Followers 361 Following claude code + cowork @anthropicai, prev: @dagster, @scale_ai
𝔊𝔴𝔢𝔯𝔫 @gwern
107K Followers 115 Following Internet besserwisser; pedantic, mean reply guy. 𝘞𝘢𝘵𝘢𝘴𝘩𝘪 𝘬𝘪𝘯𝘪𝘯𝘢𝘳𝘪𝘮𝘢𝘴𝘶! (Follow requests ignored due to terrible UI.)
AI Security Institute... @AISecurityInst
22K Followers 34 Following We conduct scientific research to understand AI’s most serious risks and develop and test mitigations.You might like


















