

-
Tweets9
-
Followers19
-
Following18
-
Likes365
updated my portfolio! you can now fight the little guide robot when it steals website pieces goldpig888.github.io
Thanks for the feedback! To clarify, it’s 5 trials/task across 10 tasks. We’ll update to 15 trials/task. With 7 policies already evaluated, that’s ~6–8 hours per policy. That's challenge of real-world evaluation, but we’re committed! @JiahuiZhang__32 @alexhuang1029 @maylynn_e
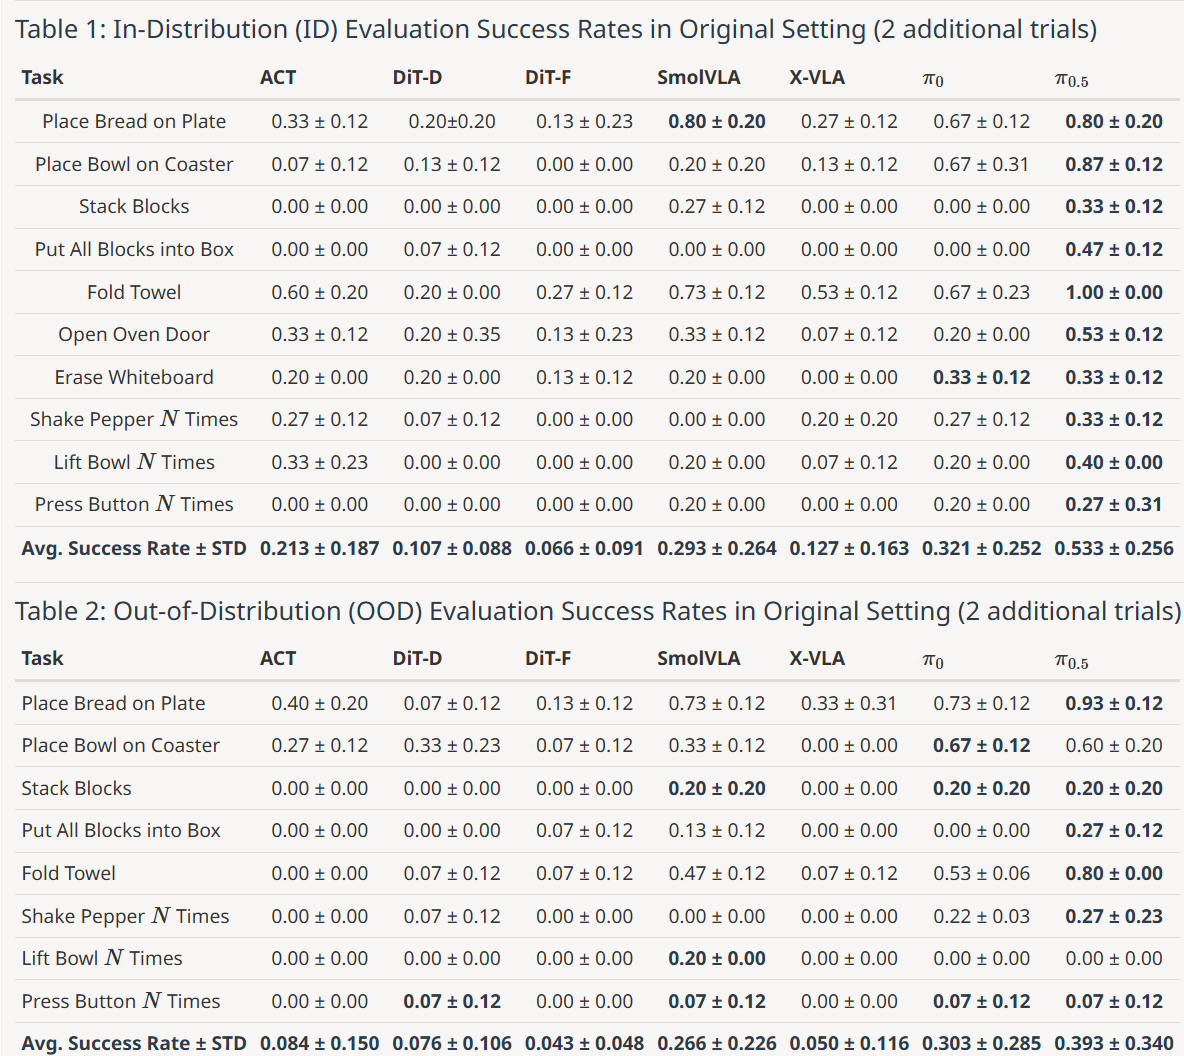

5 trials on this leaderboard is a highlight reel. I'd want intervals, cycle time, jam recovery, overrides and intervention data. irvlutd.github.io/VLAReplica/#le…
@bidhan That's exactly why RobotReplica exists. One standardized evaluation so results aren't tied to whatever robot happens to be under each model. Check it out! :) robot-replica.org
We finished evaluating MolmoAct2 on VLA-Replica! It shows better OOD performance than π0.5. Check out the details from @maylynn_e @alexhuang1029 @JiahuiZhang__32 below 👇 We’ll keep benchmarking frontier models for robot manipulation in the real world. Next up: GPT-6 Astra!
Finished fine-tuning MolmoAct2 on our VLA-Replica SO-101 setup, using 50 demonstrations per task! One result I find interesting: it outperforms π₀.₅ on OOD by 10%. Check out our leaderboard: irvlutd.github.io/VLAReplica/#le… pic.x.com/27qkS6Swfh
Really cool to see evaluation done in such a systematic and reproducible way. Standardized evaluation is one of the hardest problems out there right now!
We finished evaluating MolmoAct2 on VLA-Replica! It shows better OOD performance than π0.5. Check out the details from @maylynn_e @alexhuang1029 @JiahuiZhang__32 below 👇 We’ll keep benchmarking frontier models for robot manipulation in the real world. Next up: GPT-6 Astra!
@VilleKuosmanen @YuXiang_IRVL @alexhuang1029 @JiahuiZhang__32 All the MolmoAct2 training/fine-tuning settings are in the "Training & Model Parameters" table right under here: robot-replica.org/vla-replica#le… Good luck on your evals :)
ID: MolmoAct2 reaches 46% success, compared to 54% for π₀.₅, ~30% for SmolVLA, and ~30% for π₀ irvlutd.github.io/VLAReplica/sce… OOD: MolmoAct2 reaches 45% success across 8 VLA-Replica-OOD tasks, compared with 35% for π₀.₅, 30% for SmolVLA, and 30% for π₀ irvlutd.github.io/VLAReplica/sce…
Finished fine-tuning MolmoAct2 on our VLA-Replica SO-101 setup, using 50 demonstrations per task! One result I find interesting: it outperforms π₀.₅ on OOD by 10%. Check out our leaderboard: irvlutd.github.io/VLAReplica/#le… pic.x.com/27qkS6Swfh
We finally got a chance to test MolmoAct 2 on our VLA-Replica setup! @DJiafei @hq_fang Here’s one successful “zero-shot” case from our side :) @maylynn_e @alexhuang1029 @JiahuiZhang__32 We put “zero-shot” in quotes since we don’t know what data this MolmoAct 2 model was trained on. Two preliminary observations from our tests: • It seems quite sensitive to object color. Detailed instructions with color can help. • It struggles with precise grasping of small objects, such as a block.

Anshuman Lall @ NeurI... @anshuman1
525 Followers 4K Following LLM Post-Training/ Recursive Self-Improvement for Reasoning Co-founder/ MTS @ReasonCoreAI PhD @UCLA, Bachelors @iitbombay Led a team of ~500 PhD researchers
Hengxiangchen @HengxiangCHEN
2 Followers 489 Following
Jiafei Duan @DJiafei
8K Followers 1K Following Assistant Professor at @NUScomputing | Robotics & AI PhD @uwcse | Host of @RoboPapers | Ex-@allen_ai robotics lead, @NVIDIA | Magician | my opinion is my alone.

Shuo Liu @liu_shuo42927
115 Followers 343 Following Senior Research Engineer @cortexairobot Prev M.S. @uw_ece, Student Researcher @allen_ai
Ansh Shah @baymax3009
118 Followers 2K Following Researcher | Tennis Enthusiast | prev RRC, IIITH | BITS Pilani 2023 | Robot Learning
Jishnu Jaykumar Padal... @jis_padalunkal
190 Followers 2K Following PhD Candidate | Research focus on improving #RobotPerception, #RobotLearning | Prev @rai_inst @iitkgp @NVIDIA @IISc
Pankhuri Vanjani @VanjaniPankhuri
391 Followers 2K Following PhD Intuitive Robots Lab at KIT, Germany in Robot Foundational Models. Formerly at @VcaiMpi, @SIC_Saar, @arlnus, @JdeRobot,
Jikai Wang @JwRobotics
104 Followers 80 Following

Ville🤖 @VilleKuosmanen
4K Followers 1K Following gentleman scientist 🤖 @armnet_dev building the world's largest open arm farm 🇫🇮🇬🇧

Hysterical Brook @waytobrook
95 Followers 1K Following I’m trying to get my follower count to 0, will you help me? Proud Walmart janitor 10+ years
Jiahui Zhang @JiahuiZhang__32
216 Followers 936 Following PhD @IRVLUTD | Prev: RA @USC CLVR lab, Lira Lab | Intern @fieldai_, Horizon Robotics | Master @USC
Intelligent Robotics ... @IRVLUTD
433 Followers 18 Following Welcome to the X page of the Intelligent Robotics and Vision Lab @UT_Dallas
Alex S. Huang @alexhuang1029
38 Followers 22 Following Honors EE @UT_Dallas | Researcher @IRVLUTD | 2025 ISEF Finalist
Yu Xiang @YuXiang_IRVL
7K Followers 1K Following I do research in robotics and computer vision @IRVLUTD, Ex- research scientist @NVIDIA, postdoc @uwcse and @StanfordAILab, phd @UMich, all views my own.
Daniel Rupawalla @danielrupawalla
2K Followers 2K Following RL research | prev. acq by US News / ex-YC

Emerson S @Em_Nomadic
6K Followers 7K Following Physical AI & Robotics◽️Growth & GTM Engineer @tnkrdotai ◽️Head of GTM @DiracRobotics ◽️GTM @Hyphenbox
Luis Felipe Casas @lfcasas7
389 Followers 138 Following Ph. D. candidate @ UT Dallas. Member of the Intelligent Robots and Vision Lab (IRVL)
Ai2 @allen_ai
87K Followers 450 Following Breakthrough AI to solve the world's biggest problems. › Join us: https://t.co/MjUpZpKi8b › Newsletter: https://t.co/k9gGznrVGL
Shuo Liu @liu_shuo42927
115 Followers 343 Following Senior Research Engineer @cortexairobot Prev M.S. @uw_ece, Student Researcher @allen_ai
Jishnu Jaykumar Padal... @jis_padalunkal
190 Followers 2K Following PhD Candidate | Research focus on improving #RobotPerception, #RobotLearning | Prev @rai_inst @iitkgp @NVIDIA @IISc
Pankhuri Vanjani @VanjaniPankhuri
391 Followers 2K Following PhD Intuitive Robots Lab at KIT, Germany in Robot Foundational Models. Formerly at @VcaiMpi, @SIC_Saar, @arlnus, @JdeRobot,
Jikai Wang @JwRobotics
104 Followers 80 Following
Ville🤖 @VilleKuosmanen
4K Followers 1K Following gentleman scientist 🤖 @armnet_dev building the world's largest open arm farm 🇫🇮🇬🇧
Jiafei Duan @DJiafei
8K Followers 1K Following Assistant Professor at @NUScomputing | Robotics & AI PhD @uwcse | Host of @RoboPapers | Ex-@allen_ai robotics lead, @NVIDIA | Magician | my opinion is my alone.
Jiahui Zhang @JiahuiZhang__32
216 Followers 936 Following PhD @IRVLUTD | Prev: RA @USC CLVR lab, Lira Lab | Intern @fieldai_, Horizon Robotics | Master @USC
Alex S. Huang @alexhuang1029
38 Followers 22 Following Honors EE @UT_Dallas | Researcher @IRVLUTD | 2025 ISEF Finalist
Intelligent Robotics ... @IRVLUTD
433 Followers 18 Following Welcome to the X page of the Intelligent Robotics and Vision Lab @UT_Dallas
Yu Xiang @YuXiang_IRVL
7K Followers 1K Following I do research in robotics and computer vision @IRVLUTD, Ex- research scientist @NVIDIA, postdoc @uwcse and @StanfordAILab, phd @UMich, all views my own.
Daniel Rupawalla @danielrupawalla
2K Followers 2K Following RL research | prev. acq by US News / ex-YCTrends for United States
You might like


















