Mutian He @mutiann_
PhD student at @EPFL & @Idiap_ch, working at the crossroads of LLM and speech understanding mutiann.github.io Joined April 2025-
Tweets31
-
Followers17
-
Following94
-
Likes92
@yzhang_cs @nathancgy4 @Xinyu2ML @Yulun_Du It is certainly THE Sputnik moment for a lot more than OSS!
hybrid linear attn is scalable!!

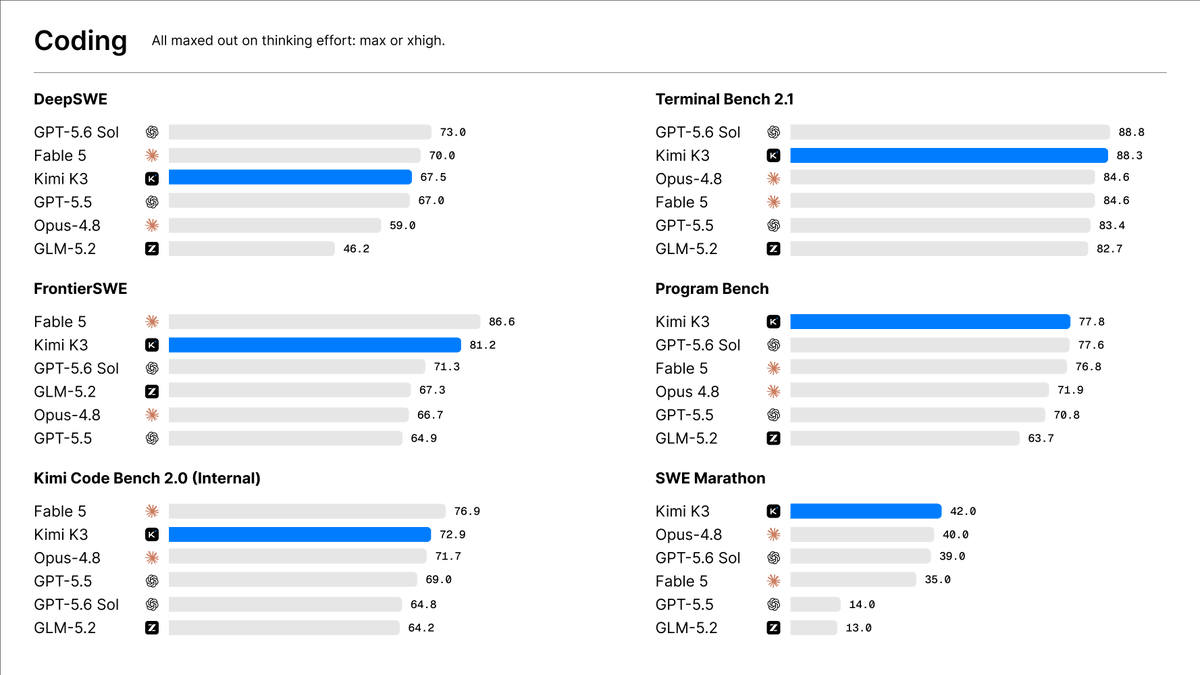
Introducing Kimi K3: Open Frontier Intelligence 🔹 2.8 Trillion Parameters, 1 Million Context, Native Multimodal 🔹 Kimi Delta Attention enables up to 6.3x faster decoding in million-token contexts 🔹 Attention Residuals deliver ~25% higher training efficiency at <2% additional


Today, we are introducing Inkling. Inkling reasons efficiently across text, image, and audio modalities. We are making the full weights available. thinkingmachines.ai/news/introduci… Available today for fine-tuning on Tinker. Play with it in the Inkling Playground. 🧵
To beast Oblivionis we need the many-headed beast...

Excited to share our work on hybrid linear-sparse attention at ICLR MemAgents (Rm 205, 2:50pm, 4.27)! Alleviating Forgetfulness of Linear Attention by Hybrid Sparse Attention and Contextualized Learnable Token Eviction arxiv.org/abs/2510.20787 Code: mutiann.github.io/papers/laLTE

TLDR: With a Learnable Token Eviction CNN to drop KVs from memory based on past&future context, a hybrid Gated DeltaNet+sparse attention is as fast as pure GDN and hybrid GDN+SWA, but forgets much less, and performs close to std transformer and GDN+NSA (which uses full KV cache)
Excited to share our work on hybrid linear-sparse attention at ICLR MemAgents (Rm 205, 2:50pm, 4.27)! Alleviating Forgetfulness of Linear Attention by Hybrid Sparse Attention and Contextualized Learnable Token Eviction arxiv.org/abs/2510.20787 Code: mutiann.github.io/papers/laLTE
TLDR: With a Learnable Token Eviction CNN to drop KVs from memory based on past&future context, a hybrid Gated DeltaNet+sparse attention is as fast as pure GDN and hybrid GDN+SWA, but forgets much less, and performs close to std transformer and GDN+NSA (which uses full KV cache)
@LLMenjoyer @kamesh_ai @leonlufkin Agree. Hybrid attn in a more ''integrated'' way so that the linear attn layers interact with/guide sparse attn should be a really promising direction! BTW we've also built a variant of the learned router: x.com/i/status/20223…
I always firmly believe that hybrid attn (w/ linear attn for locality & sparse attn for retrieval) IS the next gen LLM architecture. It's so exciting to see such a model at a seriously large scale! Also check our previous work on this topic! arxiv.org/abs/2510.20787


immensely proud to share 2 of my bros' work, Hybrid Associative Memories by @kamesh_ai and @leonlufkin It's basically SSM and Attention merged into one layer, where the attention is also sparse like DSA. Except you pretrain with the sparsity. It's lowkirk based (1/N) 👇

@OpenBMB I always firmly believe that hybrid attn (w/ linear attn for locality & sparse attn for retrieval) IS the next gen LLM architecture. It's so exciting to see such a model at a seriously large scale! Also check our previous work on this topic! arxiv.org/abs/2510.20787


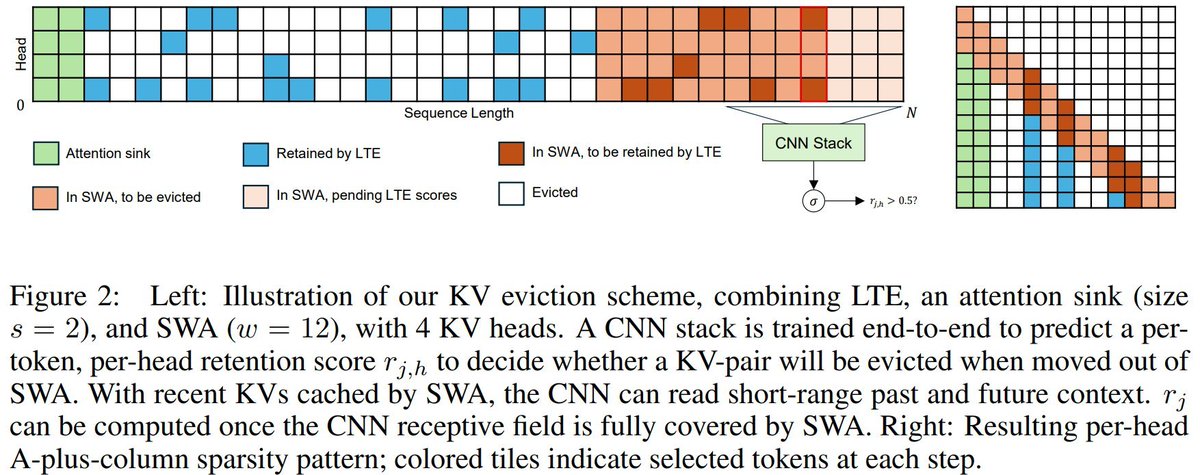
I always firmly believe that hybrid attn (w/ linear attn for locality & sparse attn for retrieval) IS the next gen LLM architecture. It's so exciting to see such a model at a seriously large scale! Also check our previous work on this topic! arxiv.org/abs/2510.20787


@XingweiQu48400 @GeZhang86038849 Thanks for the reply! Actually my question is, when the KV-pair of a concept is replicated, say, for m times, will it receive m times pre-softmax attention weight for each query? Also I wonder what exactly is S in Sec 3.5.1? Thanks in advance!
@GeZhang86038849 Wonderful work! While I'm still a bit confused by the repeat_interleave approach: As KVs are replicated/upsampled, will it be no longer equivalent to the original cross-attn? Or there is some impl. tweak to ensure the equivalence?
Kimi Linear Tech Report is dropped! 🚀 huggingface.co/moonshotai/Kim… Kimi Linear: A novel architecture that outperforms full attention with faster speeds and better performance—ready to serve as a drop-in replacement for full attention, featuring our open-sourced KDA kernels! Kimi Linear offers up to a 75% reduction in KV cache usage and up to 6x decoding throughput at a 1M context length. Key highlights: 🔹 Kimi Delta Attention: A hardware-efficient linear attention mechanism that refines the gated delta rule. 🔹 Kimi Linear Architecture: The first hybrid linear architecture to surpass pure full attention quality across the board. 🔹 Empirical Validation: Scaled, fair comparisons + open-sourced KDA kernels, vLLM integration, and checkpoints. The future of agentic-oriented attention is here! 💡
When we put lots of text (eg a code repo) into LLM context, cost soars b/c of the KV cache’s size. What if we trained a smaller KV cache for our documents offline? Using a test-time training recipe we call self-study, we find that this can reduce cache memory on avg 39x (enabling 26x higher tok/s and lower TTFT) while maintaining quality. These smaller KV caches, which we call cartridges, can be trained once and reused for different user requests! Github: HazyResearch/cartridges

Today Thinking Machines Lab is launching our research blog, Connectionism. Our first blog post is “Defeating Nondeterminism in LLM Inference” We believe that science is better when shared. Connectionism will cover topics as varied as our research is: from kernel numerics to prompt engineering. Here we share what we are working on and connect with the research community frequently and openly. The name Connectionism is a throwback to an earlier era of AI; it was the name of the subfield in the 1980s that studied neural networks and their similarity to biological brains. thinkingmachines.ai/blog/defeating…

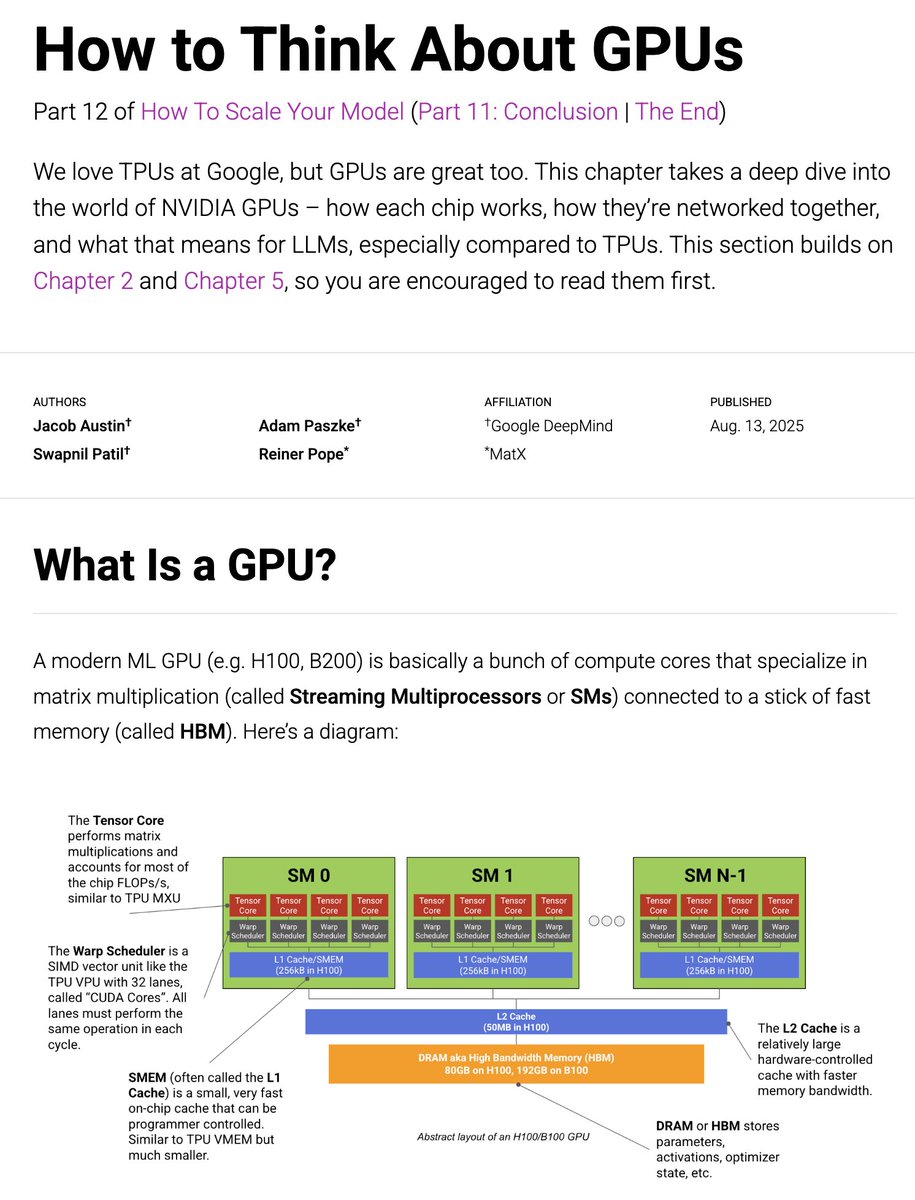
Today we're putting out an update to the JAX TPU book, this time on GPUs. How do GPUs work, especially compared to TPUs? How are they networked? And how does this affect LLM training? 1/n
A distributed conference....
NeurIPS is pleased to officially endorse EurIPS, an independently-organized meeting taking place in Copenhagen this year, which will offer researchers an opportunity to additionally present their accepted NeurIPS work in Europe, concurrently with NeurIPS. Read more in our blog

Highly recommended! The historical development of attention mechanisms is tightly coupled with the evolution of mainstream model architectures in AGI. A lot insights and bitter lessons buried inside the blog!

The Linear Attention Odyssey: From Imitation to Innovation and Back kexue.fm/archives/11033

Emma tiny menace @semmay250
126 Followers 2K Following sweet like sugar, soft in dms 🧁 follow back always


Mo Li @limoquan
91 Followers 294 Following Ph.D. candidate at THU @tsinghua_uni | INTP Understanding the universe
Yueqian Lin @YueqianL
142 Followers 951 Following ECE PhD Candidate @DukeEngineering | Committer of @vllm_project Omni | Prev. intern @Adobe

Kamesh Krishnamurthy @kamesh_ai
36 Followers 102 Following AI research. Prior: Princeton PHY (CV Starr & CPBF Fellow), Simons Fellow @ Berkeley
Ge Zhang @GeZhang86038849
4K Followers 1K Following M-A-P, https://t.co/rx1DkC89v4 Prev. Seed, 01, BAAI MERT, MAP-Neo, MMMU, MAmmoTH, MMLU-pro, Yi, COIG, YuE Series, SGPQA, Ouro, Eval@Seed, Concept Model, NL2Repo,
Skkkscl @Aliparlak0089
0 Followers 268 Following
Damien Teney @DamienTeney
3K Followers 626 Following Research Scientist @ Idiap Research Institute. @Idiap_ch Adjunct lecturer @ Australian Institute for ML. @TheAIML Occasionally cycling across continents.
Caglar Gulcehre @caglarml
5K Followers 1K Following Scientist MAI, Prof @ EPFL, Ex-research scientist @ DeepMind, MSR, IBM Socials: https://t.co/qYmpvyUf0u, https://t.co/LZ5sWt7Asj
Xinyu Yang @Xinyu2ML
18K Followers 2K Following Building open frontier intelligence. Opinions are my own. They/Them
Songlin Yang @SonglinYang4
19K Followers 3K Following pretraining @thinkymachines. Prev. PhD @MIT_CSAIL. INTP 🐱. she/her/hers.
Imperial NLP @imperial_nlp
2K Followers 1K Following We are the Natural Language Processing community at @imperialcollege
Ashwin Sankar @_iunravel
792 Followers 288 Following MS student @iitmadras || Researcher @AI4Bharat || 侘び寂び (wabi sabi)
Optimal Intelligence @optimal_intel
120 Followers 709 Following Mapping the future of intelligence. AI breakthroughs, science, and the systems shaping tomorrow.


flyingpetals @flyingpetal472
885 Followers 253 Following A frustrated researcher in AI for efficient scaling and pretraining. We are bound to go to an unpredictable future. Opinions are my owns.
typedfemale @typedfemale
48K Followers 565 Following a really exciting new account "advanced pytorch user" - @cHHillee alt: @typedalt
Horace He @cHHillee
53K Followers 614 Following @thinkymachines Formerly @PyTorch "My learning style is Horace twitter threads" - @typedfemale
熊师傅 weight deca... @bigeagle_xd
12K Followers 1K Following a person living with @mianmoe, opinions are my own
Yao Fu @Francis_YAO_
24K Followers 2K Following Prev. Grok 4.5/4.6 pretraining scaling @xAI; Gemini 3 perception and project Astra @GoogleDeepMind
Xinyu Zhou @zxytim
13K Followers 1K Following
Yulun Du @Yulun_Du
8K Followers 950 Following
Xiuyu Li @sheriyuo
14K Followers 2K Following Researcher @StepFun_ai | Working on long-horizon tasks | Prev @RUC1937 | Opinions are my own
Neko · 絢香猫 aya... @ayakaneko
12K Followers 2K Following You can call me Neko! Now working on AI Companion @proj_airi https://t.co/cMCndYRTWY | Core member of @moeru_ai | AI Infra | Memory | Literally Fullstack
Jiayuan Mao @maojiayuan
2K Followers 223 Following Applied Scientist @ Amazon FAR / Incoming assistant professor @CIS_Penn / PhD from @MIT_LISLab and @MITCoCoSci Learning, Reasoning, and Planning with Concepts
Mo Li @limoquan
91 Followers 294 Following Ph.D. candidate at THU @tsinghua_uni | INTP Understanding the universe
Yueqian Lin @YueqianL
142 Followers 951 Following ECE PhD Candidate @DukeEngineering | Committer of @vllm_project Omni | Prev. intern @Adobe
InclusionAI @TheInclusionAI
2K Followers 23 Following AI Lab @AntGroup, we envision AGI as humanity's shared milestone. Our Language Model @AntLingAGI and LLaDA, Embodied AI @robbyant_brain, OSS projects @AReaL_AI.
Ant Ling @AntLingAGI
13K Followers 5 Following MoE model series with foundation (Ling), reasoning (Ring) and any-to-any (Ming) from Ant Group’s AGI initiative, @TheInclusionAI. https://t.co/6LEkFlo2cq
Kamesh Krishnamurthy @kamesh_ai
36 Followers 102 Following AI research. Prior: Princeton PHY (CV Starr & CPBF Fellow), Simons Fellow @ Berkeley

Quasar @QuasarModels
3K Followers 27 Following Bittensor subnet built to crush the long-context barrier | SN24 | Owners : @yousseffarahat0 and @troyquasar Backed by @const_reborn
Alessandro Suglia @ale_suglia
1K Followers 1K Following Lecturer @EdinburghNLP; Ex Head of Visual Dialogue at @helloalana; PhD @EDINRobotics; Ex Research Intern @MetaAI and @AmazonScience.
Aviv Bick @avivbick
680 Followers 25 Following CS PhD @ CMU https://t.co/tCKYiUbOdr | https://t.co/zdDNelFVJO
You Jiacheng @YouJiacheng
12K Followers 2K Following
OpenBMB @OpenBMB
11K Followers 384 Following OpenBMB (Open Lab for Big Model Base) aims to build foundation models and systems towards AGI. Connect with us: https://t.co/N9pevTnoOa
MiniCPM @MiniCPM
157 Followers 4 Following A GPT-4o Level MLLM for Vision, Speech and Multimodal Live Streaming on Your Phone
Sakana AI @SakanaAILabs
140K Followers 0 Following Building Frontier AI in Japan Try Sakana Chat, Translate, Marlin, Namazu, Fugu 🐡 https://t.co/stLdPSz1Y7
augustus odena @gstsdn
12K Followers 3K Following Something new. Previously: AI research at TBD Labs / Meta; cofounder at @AdeptAILabs; Invented Scratchpad / Chain-of-Thought; Google Brain
François Fleuret @francoisfleuret
55K Followers 480 Following Research Scientist @meta (FAIR), Prof. @Unige_en, co-founder @neural_concept_. I like reality.
Nino Scherrer @ninoscherrer
1K Followers 3K Following Research Scientist at @Google | Interested in Language Model Architectures & Pre-Training Evaluations
kyutai @kyutai_labs
28K Followers 14 Following
Damien Teney @DamienTeney
3K Followers 626 Following Research Scientist @ Idiap Research Institute. @Idiap_ch Adjunct lecturer @ Australian Institute for ML. @TheAIML Occasionally cycling across continents.
Caglar Gulcehre @caglarml
5K Followers 1K Following Scientist MAI, Prof @ EPFL, Ex-research scientist @ DeepMind, MSR, IBM Socials: https://t.co/qYmpvyUf0u, https://t.co/LZ5sWt7Asj
Luke McDermott @lukemcdermotttt
231 Followers 802 Following PhD student @UCSanDiego researching attention, currently interning at Cartesia
Zhihu Frontier @ZhihuFrontier
12K Followers 187 Following 🚀Bringing China's AI & tech trends, voices and perspectives to the global stage. ⚡️Powered by 知乎/https://t.co/OkIemRYFmL, China's leading knowledge community.

Wenhao Chai @wenhaocha1
4K Followers 2K Following PhD @PrincetonCS. prev @GoogleDeepMind. AI for AI R&D.
Arshia Afzal @rshia_afz
628 Followers 286 Following Ph.ding @ EPFL. Cooking linear stuff | ex. pre-trainer @MistralAI | Bronze IPHO 2018

JingyuanLiu @JingyuanLiu123
4K Followers 582 Following https://t.co/D7zLeTZRMh is all you need | I am not Jianlin, just love his work... | Opinions are my own
Xinyu Yang @Xinyu2ML
18K Followers 2K Following Building open frontier intelligence. Opinions are my own. They/Them
Ge Zhang @GeZhang86038849
4K Followers 1K Following M-A-P, https://t.co/rx1DkC89v4 Prev. Seed, 01, BAAI MERT, MAP-Neo, MMMU, MAmmoTH, MMLU-pro, Yi, COIG, YuE Series, SGPQA, Ouro, Eval@Seed, Concept Model, NL2Repo,
Guangxuan Xiao @Guangxuan_Xiao
5K Followers 848 Following Pretraining @thinkymachines | Ph.D. @MITEECS
Tri Dao @tri_dao
45K Followers 661 Following Asst. Prof @PrincetonCS, Chief Scientist @togethercompute. Machine learning & systems.
Xin Eric Wang @xwang_lk
22K Followers 1K Following Professor @ucsantabarbara. Head of Research @SimularAI. Director @ucsbcrml @UCSB_AI. Build the Science of Multimodal AI Agents. AI for Humanity in the long run.
Tilde @tilderesearch
6K Followers 6 Following We build foundational understanding of models to advance the frontier of intelligence.
Liliang Ren @liliang_ren
4K Followers 748 Following Pretraining @thinkymachines | Prev. Microsoft Superintelligence | UIUC CS PhD | Scaling Efficient LLM | NLP
Yu Zhang 🐙🌘 @yzhang_cs
7K Followers 939 Following @Kimi_Moonshot; working on efficient methods for LLMs; disciple of parallel programming; INTP; 🐈
Han Guo @HanGuo97
4K Followers 4K Following PhD Student @MIT_CSAIL | Past: @togethercompute @LTIatCMU @MITIBMLab @UNCNLP, @SFResearch, @BaiduResearch | Machine Learning, NLP.Trends for United States
You might like