

raphael lee @raphaelee
https://t.co/CMvN28h465 prev mts intern @mercor, @plato_rl, se @uwaterloo raphaellee.ca sf Joined April 2022-
Tweets48
-
Followers437
-
Following1K
-
Likes3K

Introducing DeepRSI, a new industry standard for measuring recursive self-improvement. On preexisting benchmarks, tasks are contributor-based and short-horizon (~12 hrs). In DeepRSI, we push agents to work 48 hours on ML tasks actually derived from ongoing proprietary research.
Today we're launching WebCloneBench: a benchmark which measures a model's ability to explore, copy, build and test various web apps. For each task, we give the model a reference site from one of Gmail, Google Sheets, Jira, DocuSign, Shopify Admin, Craigslist, Figma, Slack and Zendesk. It is instructed to build a fully feature-complete clone of every part of the application with an 8 hour time limit.
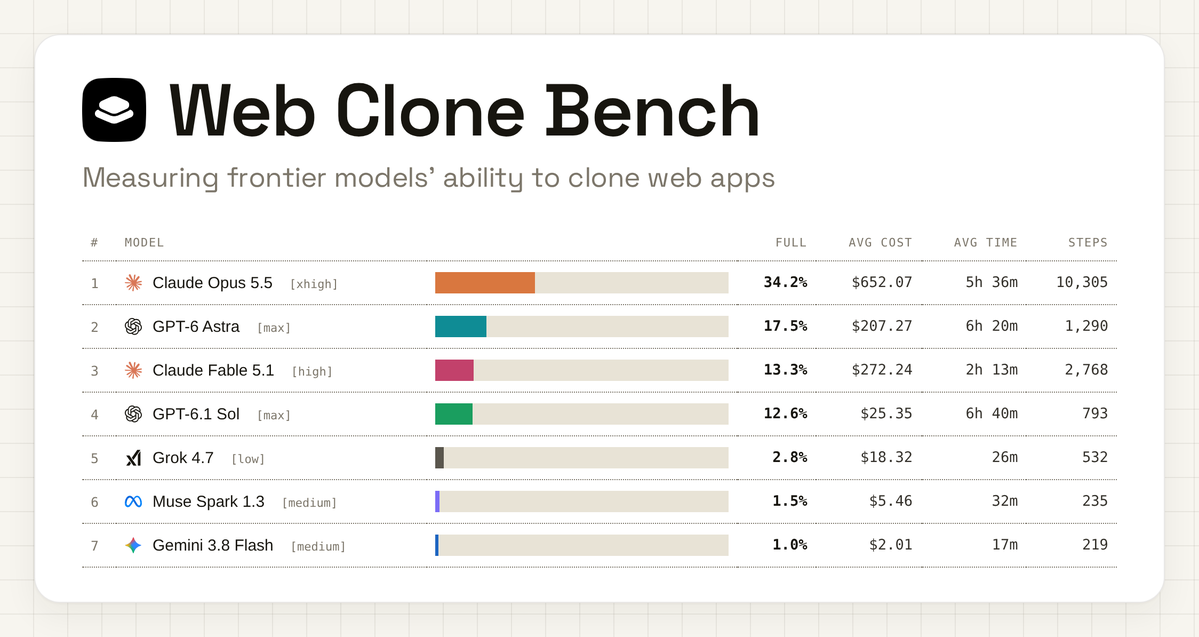
@PetarIsakovic06 models need to be chillclimbed
Who grades the graders? LLM-as-judge on short answers is well studied. Agent judges are not: they open the files, run the code, and investigate before ruling on another agent's work. Introducing Arbiter-Bench: 71 real agent runs that frontier agent judges get wrong.

Half the set is public with every judge's full logs, a scorer for your own judge, and the audit trail. 35 items are held out. Every case is a runnable @harborframework task, so you can point your own judge at the set and score it with one command. Full writeup: heuristic.build/blog/arbiterbe…
Of 232 runs where a frontier judge disagreed with the benchmark, only 71 survived a blind label audit (3+ model families, a human ruling on every split vote). About a quarter were the benchmark's error: hidden criteria, broken checkers, unstated rules.
funny seeing a problem you've been working on suddenly get so much attention

so called high quality data showing gains on evals so flawed where not a single sample is surviving basic scrutiny is a sight to behold

Tech has decided that regulation is the enemy of progress, but innovation requires capital Regulation builds the trust necessary to inject billions into markets To enable free innovation, Andera raised a $37M series A led by Lightspeed to scale financial oversight with agents
Ben (no treats) @andersonbcdefg
8K Followers 6K Following 🤖 Computer scientist, next-word-prediction enjoyer 📊 Prev. research fellow @ Stanford RegLab 🛠️ Now: Startup founder 🏳️🌈
Anthony @jiawji04
172 Followers 275 Following building and writing evals | prev @xAI | opinions are my own | 🇨🇦
Rohan @rva567
1 Followers 53 Following
ChinesePowered.com @ChinesePowered
222 Followers 234 Following CHINESE, not asian/american. Private LLM on your phone https://t.co/KiHhtIQpDH Capybara game https://t.co/OyvupYaVGo


alex @alexgaoth
294 Followers 647 Following mts @hypercubic_ai (YC F25), prev @ibm @bloomberg building https://t.co/Bn3SXpMEPS

Su Park @sunotsue_
492 Followers 1K Following terminal bench · post-training & evals against global banality prev @ltiatcmu @columbia
anish lakkapragada @_anishlk
516 Followers 432 Following @proximalhq, math @yale, prev @mathematics_inc
Jerry @Bobliuuu
672 Followers 1K Following CS PMATH CO CM @uwaterloo | ⁂ | world model researcher | smooth manifold addict


Saloon Cap @SaloonCapital
559 Followers 2K Following l/s prospector and llm wrangler; I like picking big themes and trading sentiment. welcome to my saloon
Zaid Khan @codezakh
776 Followers 2K Following NDSEG Fellow / PhD @uncnlp with @mohitban47 working on automating env/data generation + program synthesis formerly @allenai @neclabsamerica
Steve Patrizi @spatrizi
2K Followers 4K Following CMO at @ReveloHQ, the data lab focused on code for frontier AI


William Chiu @WilliamRChiu
9 Followers 24 Following
Ben Rank @full__rank
374 Followers 428 Following PostTrainBench, InferenceBench | PhD Student @ELLISInst_Tue and @MPI_IS
Rishi Padmanabhan @rishi____1
12K Followers 844 Following OOD code data | past: @stanford math @meta ai. https://t.co/4lAy3S8i8l | dms open
Rayan Mubarak @rayannmubarak
646 Followers 963 Following ceo @ Enjamb (YC P26) • 19 • prev bio ml researcher
ViggoDaBigDum @silkybella579
18 Followers 1K Following
nabira rashid @nabirarashid
224 Followers 440 Following cs @uwaterloo // @mit_csail, prev ml @carnegiemellon
Yasir Ali @exploringfornow
2K Followers 2K Following building. did a couple companies. still at it alum: south park commons




Hixon @HixonStudio
4K Followers 7K Following https://t.co/BWV7i6085Z 👉 Community-Driven AI Hackathons.

Demi Wang @demisama_
4K Followers 2K Following On the Job Market! | Exploring & Building @LTIatCMU | 2x Intern @MSFTResearch | Ex @BytedanceTalk @Cal | LLM Post-training & Agents | They/She
cam @camrzadki
2K Followers 1K Following ai ∩ science // prev @neo @join_ef @georgian_io @creativedlab // remember to look up at the stars


Harsh Vardhan Singh @harshoollas
103 Followers 522 Following SPL @bespokelabsai •ex @mercor_ai,@flipkart • startups• cricket • he/him • iitbhu'19
Qiuyang Mang @MangQiuyang
2K Followers 1K Following PhD student at UC Berkeley @BerkeleySky. Former ICPC World Finalists; Opinions are my own
Chinmay @ChinmayKak
4K Followers 2K Following 22. gradient ascender. prev RL @MSFTResearch . love @teamIvLabs. dms open!




Ameen Patel @Ameen_ml
3K Followers 3K Following @ stealth lab, prev @PrimeIntellect, @togethercompute, @AmazonScience, @uwaterloo
Aiqi Liu @MeetAiqi
297 Followers 304 Following Product at @cartesia | Creator of fun apps: ApplyFYI, Lyrric, Gardenful, InkIt
Vanessa Li @cyvanessali
5K Followers 577 Following @yale grad | thinking, building and occasionally investing
Anthony @jiawji04
172 Followers 275 Following building and writing evals | prev @xAI | opinions are my own | 🇨🇦
Justin Zhao @justinxzhao
458 Followers 460 Following Evals Researcher @Meta Superintelligence Labs. Past: @Google, @Predibase, CS+Music @Columbia
Maya Lekhi @mayalekhi
4K Followers 1K Following mts @vercel, prev @notionhq @contrary, host @momentum_place ⁂ 💻🏳️🌈
ChinesePowered.com @ChinesePowered
222 Followers 234 Following CHINESE, not asian/american. Private LLM on your phone https://t.co/KiHhtIQpDH Capybara game https://t.co/OyvupYaVGo

Vivian Cai @yrv_23
3K Followers 607 Following building https://t.co/mTkCQWHM9o events & communities @try_cali

Percy Liang @percyliang
127K Followers 424 Following professor of computer science @Stanford @stanfordnlp, co-founder of @togethercompute, https://t.co/7R5THVnJ6u, @simile_ai, pianist
Charles 🎉 Frye @charles_irl
20K Followers 3K Following memer of technical staff at @modal. he/him. ex @full_stack_dl, @weights_biases (acq. @CoreWeave), phd Berkeley @Redwood_Neuro.
alex @alexgaoth
294 Followers 647 Following mts @hypercubic_ai (YC F25), prev @ibm @bloomberg building https://t.co/Bn3SXpMEPS


Souradip Chakraborty @SOURADIPCHAKR18
3K Followers 5K Following Postdoc at @MIT CSAIL @nlp_mit Research: #RL, #Posttraining, #Alignment #RLVR Past: CS PhD @umdcs @ml_umd SR @GoogleResearch #JPMC #Walmart

Erik Newsham @eriknewsha
7K Followers 395 Following dabbling in company data at @grepped_ai too many DMs, email me at [email protected]
Transluce @TransluceAI
13K Followers 21 Following Open and scalable technology for understanding AI systems.
Su Park @sunotsue_
492 Followers 1K Following terminal bench · post-training & evals against global banality prev @ltiatcmu @columbia
Plato @plato_rl
86 Followers 3 Following Applied research lab building simulated training environments

Rishi Desai @rishi_desai2
1K Followers 1K Following RL environments for code. SWE-Marathon. Pianist. prev: @Stanford
Luxia 🔮 @kataletheia
964 Followers 490 Following ¸,ø¤º✧º¤ø,¸.¸,ø¤º✧º¤ø,¸ awake | dream | catalyst ¸,ø¤º✧º¤ø,¸.¸,ø¤º✧º¤ø,¸

pratik @pratik_satija
2K Followers 943 Following Founder/CEO @tensol_ai Verification layer for teams building the physical world | YC Alum | prev. @carnegiemellon, @rivian, VT
anish lakkapragada @_anishlk
516 Followers 432 Following @proximalhq, math @yale, prev @mathematics_inc
Ivan Bercovich @neversupervised
1K Followers 578 Following Independent Researcher, Partner @ ScOp VC

Jerry @Bobliuuu
672 Followers 1K Following CS PMATH CO CM @uwaterloo | ⁂ | world model researcher | smooth manifold addict
X Money @XMoney
626K Followers 1 Following Your money, on the world’s most powerful network. Rolling out to U.S. residents.

Vals AI @ValsAI
29K Followers 280 Following Public LLM Evaluation // https://t.co/rNS39rhVQ9 @8vc @BloombergBeta @pearvc @a16z @HRTVentures @nextladder
Ashish Sardana @AshishSardana21
104 Followers 43 Following

Tim Hua 🇺🇦 @Tim_Hua_
3K Followers 1K Following AI safety, Econ, new liberalism, math, and a bit of art history (as a treat) Member of Technical Staff @METR_Evals. Previously on Walmart’s economics team.

Diogo Almeida @CompleteSkeptic
157K Followers 79 Following Sane + 🌶️ takes in an insane AI world... AI capabilities researcher: co-created RLHF/ChatGPT @ @openai now trying to right the wrong 🤭 (ceo @typesafeai)
Ben Rank @full__rank
374 Followers 428 Following PostTrainBench, InferenceBench | PhD Student @ELLISInst_Tue and @MPI_IS
Rishi Padmanabhan @rishi____1
12K Followers 844 Following OOD code data | past: @stanford math @meta ai. https://t.co/4lAy3S8i8l | dms open
Rayan Mubarak @rayannmubarak
646 Followers 963 Following ceo @ Enjamb (YC P26) • 19 • prev bio ml researcher

Charlie O'Neill @oneill_c
23K Followers 1K Following The sea is the sea The old man is an old man The boy is a boy and the fish is a fish The sharks are all sharks no better and no worse
Jonathan Swerdlin @swerdlin
2K Followers 1K Following My life's work is to keep people healthy. Co-founder @functionTrends for United States
You might like


















