

Kvn @spnova05
Joined October 2021-
Tweets126
-
Followers5
-
Following96
-
Likes86
@AkitaOnRails Finalmente um br na minha timeline. Opinião minha: LLM local no momento só faz sentido o strata com qwen uncensored para algumas requisições que modelos fechados negam o resto roda em assinatura ou API, hardware local além do custo, tem energia e também degrada. pra BR mt caro.

Clearly, I will not be getting sleep tonight huggingface.co/MiniMaxAI/Mini…
@0xSero Calm down mate, you are the 0.001% that has a 75k usd rig, still far hit for most of commom users
@ItsmeAjayKV I was thinking: maybe we should always test a model via the API before trying quants. People tend to see the promising benchmarks of the full model, then test it on a heavily quantized version. Let's try the same prompt via the API first!
@ashxhart @Aria_persian94 Yep, you among many others here, sounds very ignorant people when throw bs like it was a really bigger deal than it actually is. You dont even need to do a deep fact check, it is right at the beggining (federal civil agencies).
@ItsmeAjayKV At least all those “AI boxes” will finally get cheaper now that you won’t need 4 DGXs anymore.
@o_at72 @PeasantSmith It is a great model, since "oxalpha", it works very well on most of my demand, s2
@o_at72 @PeasantSmith And like I said. This is only the beggining, a small step, but I know we are gonna get real better... Also very soon they are releasing qwen4, We already can imagine how wonderful it is going to be with strata engine.
@o_at72 @PeasantSmith Yeah 🤣🤣 mostly because my hyperfocus mode is on... so my last 48 hours was about trying to run it as fast as I could, and the result was good! We came from average 3.5tk/s to 16,9 tk/s today, now I believe I'm satisfied and was able to contribute to the community
@o_at72 @PeasantSmith Also, on my box, when it grabbed ~45.3 GB the engine failed to start with "pinned disk staging did not allocate". I'm going to report that one to the dev. Thanks for the AHEAD tip, it's what got me digging!
@o_at72 @PeasantSmith One heads-up if you benchmark: the RAM tier is sized from free RAM at startup, so back-to-back runs get different tier sizes and that skews the numbers a lot. One of my runs got 4 GB less and lost ~10%. Pin it with STRATA_GLM_RAM_GB while comparing.
@o_at72 @PeasantSmith But that's a guess, and since you're more disk-bound than me it could be even bigger for you, or nothing. Worth trying --env STRATA_GLM_READ_CHUNKS=4 and maybe 2.
@o_at72 @PeasantSmith +15% decode just from that. Anything from 1 to 4 flattens out, so I kept 4. Disk wait per token dropped from ~30–37 ms to ~17–29 ms. My guess is that fewer, bigger reads suit my NVMe RAID 0 better, and the reader threads compete less with the CPU lane.
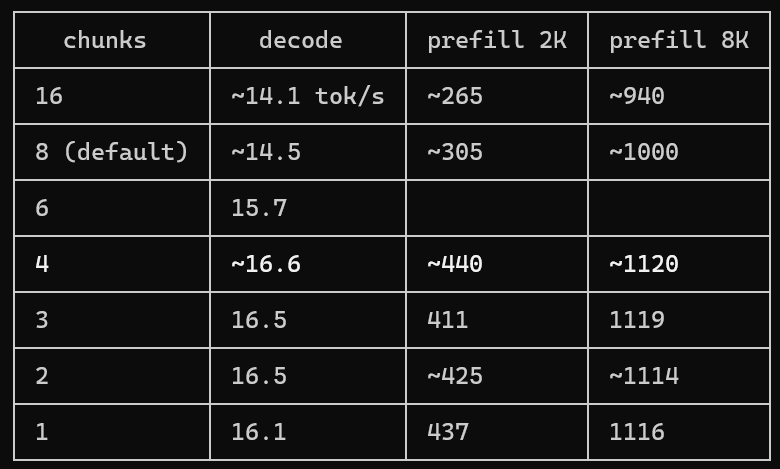
@o_at72 @PeasantSmith I ran the built-in bench (--bench: greedy, same output every time) with the RAM tier fixed so every run got the same RAM:
@o_at72 @PeasantSmith Yeah, 64K is on purpose. That's all I need for my agent harness, and with KV_INT8 it only costs 0.68 GB of VRAM, so my expert pool stays at the full 2352 slots. 256K would eat ~1.2 GB more of the pool all the time, even on short chats, and I never fill it.
@o_at72 @PeasantSmith For reference, I'm at ~14 tok/s decode, sometimes 20+ once the caches are warm on short answers. Disk misses are still about 40% of my per-token time, so that's where any further speedup would come from.
@o_at72 @PeasantSmith RAM_HEADROOM_GB=6: that's already the default.
Digital Spaceport @gospaceport
3K Followers 592 Following Local AI. Garage Datacenter. https://t.co/gjYUwsjLIH
boreaman @borea41609100
240 Followers 5K Following
Peasant Smith @PeasantSmith
2K Followers 499 Following Old grumpy IT guy pushing AI onto old hardware. Project Maya - Run DeepSeek-V4.1-Flash-1017 & GLM 5.3 Flash today on the hardware you own 🫡
Skadi @cpzerodois
7 Followers 12 Following
Deyse @DeyseCo81993123
7 Followers 36 Following
Fabio Makita @AkitaOnRails
96K Followers 426 Following Agile Senior Vibe Coder 🦅😂 https://t.co/gZlMJDW3pB Assine https://t.co/2wEqX99wye Livro https://t.co/B5wTDN3Jyq
Kimi.ai @Kimi_Moonshot
380K Followers 138 Following Built by Moonshot AI to empower everyone to be superhuman. PR: [email protected] DC: https://t.co/wBsBTn6fmE

Lumina @LuminaBench
15K Followers 734 Following • AI News and Benchmarks • Our Discord - https://t.co/t27HFvo0r9 • Tips/Contact - [email protected]
Hao AI Lab @haoailab
9K Followers 379 Following Hao AI Lab at UCSD. Our mission is to democratize large machine learning models, algorithms, and their underlying systems.
SuSu_酥酥👅 @NFT_Chen
23K Followers 2K Following #BiBiCrew Co-founder|@Sydney_Uni Master|Stock & Crypto Trader|AI Builder|Not Financial Advice, DYOR
KRAFTON AI @Krafton_AI
627 Followers 37 Following
Neo @NeoAIForecast
3K Followers 682 Following Neo Local AI | DGX Spark | Open Models | Agents Open source wins in the end Running LLMs and unnecessary distances. 🏃

atomic.chat @atomic_chat_hq
19K Followers 69 Following The simplest way to run open models on any hardware. Powered by TurboQuant. Team: @gladkos @skinbagwbones @AlexFromAtomic @danyurkin @quantizedden
Michael Helcig @mhelcig
3K Followers 107 Following Working on local intelligence. CS @ ETH Zurich, Research @ ISTA | EPFL Co-Creator of GSQ-RCO
MiniMax (official) @MiniMax_AI
129K Followers 1K Following Code: @MiniMaxAgent MiniMax Design: @Hailuo_AI API: https://t.co/fHRdSV73Hr M Plan: https://t.co/XfJWSyauda

satsuki @satsuki2694
407 Followers 2K Following AIの創造性とAI for Scienceに興味あります!気になる技術やローカルLLMの実測結果をゆるく発信🔬 AI creativity, AI for Science & local LLMs. Experiments, benchmarks, and curious ideas.

OpenDesign @OpenDesignHQ
26K Followers 66 Following The vibe design workspace for everyone and every team. 90K+ GitHub ⭐ · open-source · by any agent
ComfyUI @ComfyUI
64K Followers 155 Following The most powerful open source workflow engine for visual AI https://t.co/uKlvRQ6fW4
David Hendrickson @TeksEdge
12K Followers 552 Following CEO & Founder | PhD | Startup Advisor | @Columbia | Author Generative Software Engineering https://t.co/9oqvHuTX5f | 🔔 Follow for AI & Vibe Coding Tips 👇
Black Forest Labs @bfl_ai
56K Followers 0 Following Powering visual intelligence everywhere. Creators of FLUX models. join us: https://t.co/XiNaRNYjFH
Kimi Developers @KimiDevs
70K Followers 4 Following The official Kimi account for developers building with Kimi Code and the Kimi API.
Mercury @mercury__agent
4K Followers 15 Following Soul-driven AI agent with permission-hardened tools, token budgets, and multi-channel access. Runs 24/7 (https://t.co/GSHup0ofja). Maintained by @cosmicstack
OpenBMB @OpenBMB
13K Followers 394 Following OpenBMB (Open Lab for Big Model Base) aims to build foundation models and systems towards AGI. Connect with us: https://t.co/N9pevTnoOa
Laurent Zuijdwijk @laurent_zw
2K Followers 791 Following Ai research at https://t.co/0SFgHVF0NM. Mountains + code. Support my work: https://t.co/U2sx1rNNEp
Cary Golomb @carygolomb
16K Followers 498 Following Systems Engineer / Gaming YouTuber. PC Gaming Handhelds Since 2016. the phawx at gmail /. com. Steam / PC / Playstation / Xbox Content Creator
PentaCoxian @pentacoxian_dev
3K Followers 53 Following Developer and student at icu : novel 4DGS systems,3DGS, and Temporally stable depth video, pushing the limits of VR/XR. 最近はローカルLLMも。おかげて暖かい足元にねこが一緒に寝てくれて毎日ハッピー
Sipeed @SipeedLab
29K Followers 251 Following AI-Native Tools for Builders. Create. Debug. Explore...
Theo - t3.gg @theo
412K Followers 4K Following Full time CEO @t3dotcodes & @t3dotchat. Part time YouTuber, investor, and developer
Can I Run This LLM @CanIRunThisLLM
25 Followers 47 Following Run local LLMs? Find out what your hardware can handle — fast. Check model requirements, VRAM needs, and realistic setup guidance.
Claude @claudeai
1.9M Followers 2 Following Claude is an AI assistant built by @anthropicai to be safe, accurate, and secure. Talk to Claude on https://t.co/ZhTwG8d1e5 or download the app.
FHILY👑 @Oluwaphilemon1
10K Followers 2K Following Defi + Content Creator + Entertainment + Claude News + AI
Peasant Smith @PeasantSmith
2K Followers 499 Following Old grumpy IT guy pushing AI onto old hardware. Project Maya - Run DeepSeek-V4.1-Flash-1017 & GLM 5.3 Flash today on the hardware you own 🫡
Alex Hansen 🦈 @alexhvnsen
1K Followers 499 Following I buy boring businesses, and build stuff for founders. Sunbeam, adv rider, dad/hubby. Creator of Alan’s way 👇
huihui.ai @support_huihui
13K Followers 31 Following https://t.co/zI71a4QB1W https://t.co/QFKNuHms1N [email protected] Donation: Support our work on Ko-fi (https://t.co/gAtHKPSCHH)!
AI at AMD @AIatAMD
59K Followers 116 Following Advancing AI innovation together. Built with devs, for devs. Supported through an open ecosystem. Powered by AMD. #TogetherWeAdvance
Tencent Hy @TencentHunyuan
54K Followers 8 Following Tencent's foundation model for text, image, video, and 3D generation.
Alex Ziskind @digitalix
29K Followers 2K Following Software engineer making videos about dev gear, local AI, and weird tech experiments
AI Tracker Bot @aitrackerbot
3K Followers 119 Following Automated AI model release tracker. Built and managed by @SSHCodes. Live tracker: https://t.co/dqsiSmOzde
BlackwellBoy @Blackwellboy
5K Followers 2K Following the rig in the garage doesn't refuse. I publish the benches and the failures. 1208 GB · 5090s · Sparks · Mac Mini
Mads Henrichsen @MGHenrichsen
92 Followers 16 Following
David Y. Tan @coffeecup2020
1K Followers 405 Following Self-taught Local LLM with RTX 5060Ti 16GB/3090 24GB and GX10 Author of TQ3_4S. Christian, Dad. https://t.co/rakKxVdNof https://t.co/Mow2CgnqnF

Milan @influenist
993 Followers 319 Following Own the frontier. Founder @souveranity: frontier AI that runs on your own hardware and answer Also building TEQO (circular mfg). SERVEO founder - exited 2022.
Sean Highness @seanhighness
482 Followers 598 Following
Need More VRAM @needmorevram
810 Followers 67 Following AI Engineer • running models locally until something catches fire llama.cpp • vLLM • GGUF • homelab

Gremio Wigglytuff @GremioWigglytuf
1K Followers 49 Following Juego en línea creado por @albermagedon Mantenido por amantes de PMD. ¡Únete a nuestro Gremio! https://t.co/HXIdY7ZChw
Cline @cline
82K Followers 16 Following The open source coding agent that takes over your editor, terminal, and browser to complete work autonomously. npm i -g cline

Beamsters @Beamsters1
1K Followers 288 Following I make fast AI engine, research frontier quant and have fun doing so.You might like


















