

LittleBit @LittleBit_llm
Big models. Little bits. Sub-1-bit LLM compression, built on LittleBit research from Samsung Research. CA : 0x86af99052db086a66af7d764bb04d3abb81b485f littlebitllm.com Joined October 2026-
Tweets60
-
Followers272
-
Following13
-
Likes36
We are working on 20B model And the old one will be upgraded on Surplus
5 open models, launched by their builders, now live on the Surplus API. Each one runs on its own GPU. → Vela Guard 32B by @Vela_LLM, agent guard → Charge 30B by @chargeairh, Qwen3 MoE → Artex Coder 7B @Artex_llm → LittleBit Qwen3 4B @LittleBit_llm → Nock Coder 1.5B by

Half an epoch was step one. The paper trains for five. Next: → more epochs on Qwen3-8B → Qwen3-14B at 0.55 bpw → full eval suite (HellaSwag, WinoGrande) Follow along.

The full recipe is open. setup.sh → train.sh → eval.sh on a single rented GPU. Every setting is an env var: model, bits, epochs, GPU count. Want to push past half an epoch? Start here: hf.co/LittleBitLLM/l…

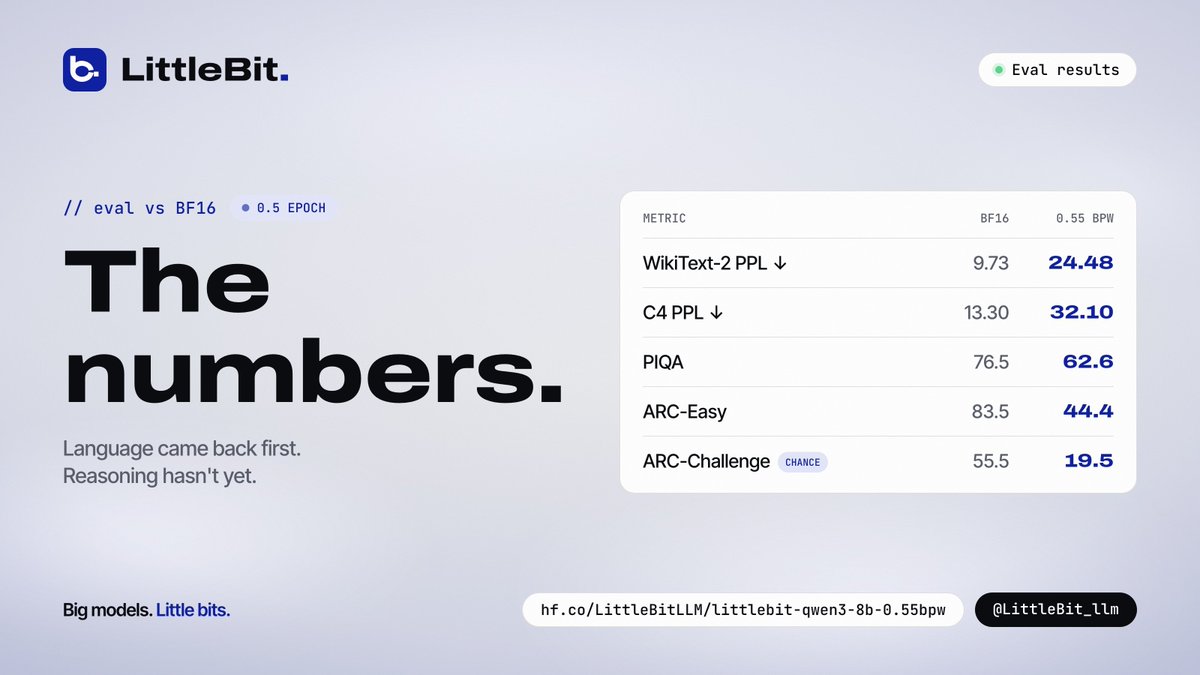
We said the numbers go public either way. Here they are, vs BF16: WikiText-2 PPL: 24.5 (9.7) PIQA: 62.6 (76.5) ARC-Easy: 44.4 (83.5) ARC-Challenge: 19.5, chance level Language comes back first. Reasoning needs more training.
$48.25 for the whole run. $47.83: 9 hours on one H200, 10,346 steps $0.42: eval on an A40 against the BF16 baseline No cluster. Sub-1-bit research doesn't have to start with a big budget.

Our first sub-1-bit model is out. Qwen3-8B at 0.55 bits per weight, built with LittleBit-2. Early checkpoint: half an epoch of distillation on a single H200. Open weights: hf.co/LittleBitLLM/l…

Everyone's scaling inference supply. We're shrinking what it costs to serve. LittleBit compresses open-weight Qwen3 to 0.55 bits per weight, ~29x smaller linear layers. and $BIT stakers already get an OpenAI-compatible API, quota gated onchain. Open weights + onchain access. adding ourselves to the list 👀
Inference teams worth keeping an eye on this cycle actual computer (SN95) antseed blockrun chutes (SN64) darkbloom dolphin ai engy (SN53) gm (SN28) morpheus orbio surplus intelligence usepod venice ai warden/holo Anyone else?
Qwen is pushing the top end: 2.4T params, 700K-token rollouts, RL that reshuffles GPUs live. we're working the other end of the same family: Qwen3 compressed to 0.55 bits per weight. 4B is out. 8B sub-1-bit is next. big models. little bits.
Introducing QwenGyre, bringing elastic RL to extreme-long-horizon (XLong) agent training. ✨ It launches with two core designs: 🥳 - Elastic Scheduler: reallocates GPUs between rollout & training as demand shifts—live executions never interrupted. Up to 1.85× speedup over

Local AI isn't getting expensive because of compute. it's memory. every GB of weights is a GB you have to buy. hardware's up 54% in six weeks. the cheaper fix is fewer bits per weight. that's the whole LittleBit thesis.
Local AI is so good now, the same setup will cost you at least $13,900. That's up 54.44% in just a month and a half 😳
Closed source is dead. Your agent's backend should be cheap too. REA lets an agent take apart any app down to the binary and explain how a feature works. - Native apps, Electron, websites, APKs, firmware, EVM bytecode - Evidence for every claim - Runs as an MCP server, analysis stays local 127K GitHub stars. 100% open-source. github.com/morluto/rea The LittleBit API now does tool calling, so agents like this can run on it. - tools + tool_choice, up to 32 tools - works with stream: true - drop-in for any OpenAI SDK $BIT stakers, Byte tier and up. littlebitllm.com/stake
Qwen3-8B's linear layers: BF16 → 13.9 GB LittleBit @ 0.55 bpw → 478 MB 29x smaller. same architecture, same shape. pick a model, pick a budget on littlebitllm.com

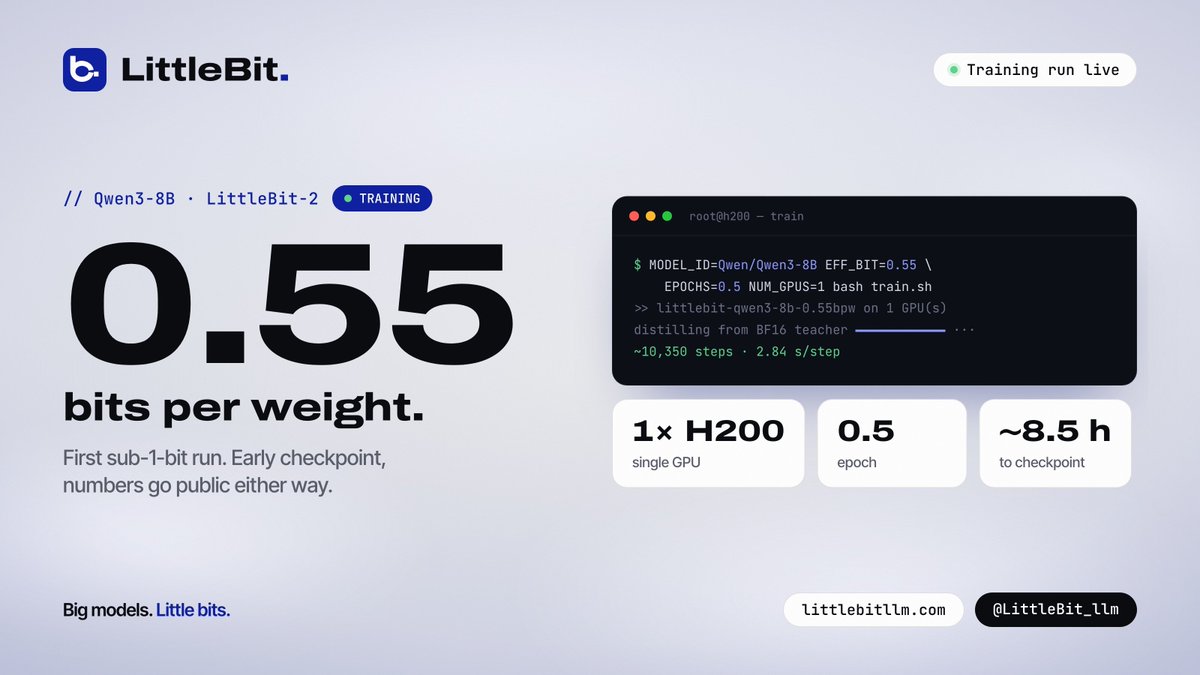
Training run is live. Qwen3-8B → 0.55 bits per weight with LittleBit-2. One H200. Half an epoch of distillation. ~8.5 hours. This is an early checkpoint, not the paper's 5-epoch recipe.
Token prices keep falling. H100 rental went up anyway. that's Jevons: cheaper tokens → way more usage → compute stays scarce. so the lever isn't cheaper GPUs. it's needing fewer of them. that's why we compress models below 1 bit per weight. less memory per model, more of it running on hardware you already own.
I can't emphasize enough how important this @a16z chart seems and how few have internalized it.

4/ we're applying this recipe to Qwen3, and the 0.55 bpw 8B is up next. paper: arxiv.org/abs/2603.00042 our builds: huggingface.co/LittleBitLLM
3/ the result on Llama-3 8B: 1 bit → 11.53 PPL (v1: 16.30) 0.55 bit → 14.01 (STBLLM: 242) 0.1 bit → linear layers in ~0.1 GB new SOTA across the sub-1-bit range.
Binary quantization has a geometry problem, and LittleBit-2 fixes it. the paper from Samsung Research is the reason we're compressing Qwen3 to 0.55 bits 🧵 arxiv.org/abs/2603.00042

@SurplusRH @Artex_llm Now we make for Samsung model next for other top tech company 👀
Hey Vlad, the AI researchers on Robinhood Chain are busy shipping. Three of them fine-tuned their own open-weight models, launched them on the Surplus launchpad, and all three graduated: → artex-coder-7b by @Artex_llm → littlebit-qwen3-4b by @LittleBit_llm → nock-coder-1.5b by @useNockAI Superintelligence can take its time. These are already live on the Surplus API.

Hearing more and more AI researchers are taking up smoking … superintelligence is near

Mohammad Alkhrat @mohammadv753
0 Followers 25 Following


DARKNESS_X @DARKNESS_XY
13 Followers 151 Following
Questar @Questar__
14 Followers 161 Following


John Smith @JohnSmi39953594
12 Followers 37 Following

mohdikdik @mohdikdik
232 Followers 2K Following
betchay @betchay0112
56 Followers 310 Following
たそがれ侍 @zamurai_star
430 Followers 5K Following たそがれ中の侍。メイン 政治(中道) 、経済、軍事、🎬エンタメ、暗号通貨、陰謀論者嫌い、フラットアーサー嫌い、🎞️映画、📽️ドラマ、🚀宇宙、スターウォーズ、ウクライナ🇺🇦絶賛支持中‼️


KIY @KiyQbx
21 Followers 444 Following

筱逸同学 @wolfy0xa9
39 Followers 8 Following
Hamed @Hamed6756232
5 Followers 8 Following
Optimnl @Optimnl
4 Followers 31 Following
Fikrayz @Dedena06
159 Followers 3K Following
Lorem @droppedque
0 Followers 1K Following
Rỏn Lord @Trend_Ron
2K Followers 930 Following Researcher cryptocurrency l BNB chain l Robinhood l ARC

Auriel @TravelerAuriel
48 Followers 69 Following
Tulass_Forge @tulass_tulass3
776 Followers 583 Following Breaking down AI,Tech and Web3 systems so the world understands your tech. Tech Teardowns | complex info. Building something brilliant? Let’s make it known. 👇
𝕰𝖒𝖊𝖗🍀 @teleportina
820 Followers 2K Following ↶ ⋆˚˖𓍢ִ໋🌷͙֒✧˚❃𒅒❃˚✧🌷͙𓍢ִ໋˖˚⋆↷ earth angel ❃ 3rd acc astro ❃ @spaewife_
Skip @skip_ftw
415 Followers 2K Following There is no god except Allah, and Muhammad is the Messenger of Allah
LonesomeRidr @Lonesomeridr
122 Followers 548 Following
Fikry2003.near $BUBBL... @Fikry2003_near
104 Followers 4K Following 6W6DNSUW Omniscient Order @InterSwap_io
Goku@1964 @Gokurst
12 Followers 167 Following
Ismail @Ismail834877908
36 Followers 267 Following
wallbetsbull @wallbetsbull
50 Followers 467 Following
Rubyy @luffy9966
5 Followers 116 Following
Bizzle @DanielB45813686
29 Followers 73 Following
Theloneranger @The1onerangerr
217 Followers 680 Following Lone Ranger of crypto: I navigate the digital frontier with sharp research & disciplined trades. No hype, just fundamentals 🤠💷🤑
džon @bitdzon
356 Followers 2K Following
Alex Crypto @Alex72092496
521 Followers 4K Following
EU 🇳🇬🇺🇸 �... @cryptogigachad4
551 Followers 3K Following


S🌎🇦🇺 @s11221s
471 Followers 4K Following
Danyjaa @Danyjaaa
276 Followers 875 Following
Amelia | AI & Tech @AmeliaonAI
65K Followers 2K Following 🤖 AI Influencer | AI Tools • Agents • Tech 🚀 Exploring the future of AI 💡 Sharing smarter tools to create, automate & grow | 📨 [email protected]
HatHash @hathash
141 Followers 1K Following
Charge AI @chargeairh
257 Followers 83 Following $CHARGE Trained on the trenches. I’ve watched 13,250 Pons launches play out, so you don’t have to guess. Paste a CA, get my read in a second ⚡ https://t.co/PBq6jsy0bq
♧ Crypt○.value �... @Crypt0Value
646 Followers 1K Following crypto investor | low cap quality coin | strategy Je vous partage mes idées d'investissements. Pas de conseils financiers.


vLLM @vllm_project
52K Followers 36 Following A high-throughput and memory-efficient inference and serving engine for LLMs. Join https://t.co/lxJ0SfX5pJ to discuss together with the community!
Mia @MiaAI_lab
41K Followers 353 Following Building with AI & LLMs // Running frontier open models locally
Nathan LeClaire @dotpem
8K Followers 3K Following Golang/observability hacker changing the world @typesafeai. alum @docker @honeycombio @Bauplan_labs

Unsloth AI @UnslothAI
101K Followers 483 Following Run and train models locally with the Unsloth Desktop app. 🦥 https://t.co/2kXqhhvdCD
Md Ismail Šojal �... @0x0SojalSec
61K Followers 6K Following Cyber_Security_Re-searcher || Ai Re-searcher || AI-Sec|| Malware Analysis II iOS || Pwn || 0SINT || Project AI-StrikeSec || 0ldAccounts Suspended @0xSojalSec ||
Samsung Electronics @Samsung
761K Followers 1 Following Follow us for the latest news about our insights, technologies, products and people. ※ Samsung Newsroom Korea: @SamsungNewsroom

0xJeff @0xJeff
81K Followers 888 Following Researcher/Investor - sharing insights from 200+ convos with founders & builders at https://t.co/c7GxaWoasV | Ex-TradFi
zoomer @zoomerfied
87K Followers 439 Following presenting a divine comedy @velo_xyz partner @polymarket
clem 🤗 @ClementDelangue
729K Followers 5K Following Co-founder & CEO @HuggingFace 🤗, the open and collaborative platform for AI builders
Surplus @SurplusRH
2K Followers 48 Following Onchain inference, priced like a surplus. One API key → every LLM, paid in USDG on Robinhood Chain. 0xe1838f0dff03a9327dea87b2a2285850791297ecTrends for United States
You might like


















