

NockAI @useNockAI
Open models that run on your machine. Nock Coder: 1 GB, offline, no API key. 0xb0f444a069d9264017610e0674ebf7e1d6e19cbb nockai.dev On your machine Joined October 2026-
Tweets123
-
Followers347
-
Following26
-
Likes128
Small open models get judged on benchmarks, but a lot of the gap is in how you ask. Same 4-bit model, same frames, one changed sentence: 3 of 12 became 10 of 12 on our screen recording questions. Measure the cheap fix before you train.
Overall it went from 31 to 35 of 56. Not free though: sport got worse, 4 to 1 of 8. Twice as many frames instead of a better prompt: 34 of 56. So the new prompt stays, and training goes after what it can't fix.
Example: when does the app switch to dark mode? The true answer is 26 to 34 s. Old prompt: 26-27 New prompt: 26-40 The change: ask for the whole stretch, from the first frame where it starts to the last frame where it's still visible.
We didn't train anything. One sentence in the prompt took "find the moment" on short screen recordings from 3 of 12 to 10 of 12. The model already knew when things started. It just stopped too early.

Answer to yesterday's clip: the error shows from about 34 s to 42 s. Qwen3.5 4B said 34-42. Gemma 4 E4B said 34.5-39.9. SmolVLM2 2.2B said 29. That one was easy. Short screen recordings overall were not: 3 of 12 for the best model.
In this clip, when does the error message show up? Our next model has to answer questions like this about your own videos, offline. We wrote 123 of them before running a single model.
Visual understanding in a small Qwen3.5 build is the part we care about most. On our video test, Qwen3.5 4B at 4-bit in llama.cpp kept almost everything the full model scored: 31 vs 34 of 56 moments, 56 vs 57 of 60 questions. Small builds hold up better than you'd think.

Today, we’re releasing Bonsai 2 2B, 4B, and 9B. Based on Qwen3.5, these new ternary models bring stronger reasoning, visual understanding, and tool calling to compact footprints designed for everyday devices: • 2B: 0.43GB • 4B: 0.95GB • 9B: 2.0GB For this release, we

Finding the moment is the hard part, and it matches what we just measured. On our 20 video test, the best small open base answered 57 of 60 questions about what's on screen, but found the right moment only 34 of 56 times. Short screen recordings were the worst: 3 of 12.
VideoJev: System One Model for Video Understanding and Interaction - >100x QA speedup vs. Thinking - +6.7 / +10.8 pts mIoU gain over 4B / MoE backbones - Opensourced 4B and 35B variants
Asking about a video already works. Finding the moment doesn't yet: on short screen recordings the best one got 3 of 12. The 4-bit build in llama.cpp kept almost all of it: 31/56, 56/60, 6/7. So Qwen3.5 4B is the base, and finding the moment is what we train next.
First run, three open bases, same frames, same prompts: Qwen3.5 4B from @Alibaba_Qwen: 34/56 moments, 57/60 questions, 7/7 summaries Gemma 4 E4B from @googlegemma: 19/56, 56/60, 6/7 SmolVLM2 2.2B from @huggingface: 1/56, 37/60, 1/7
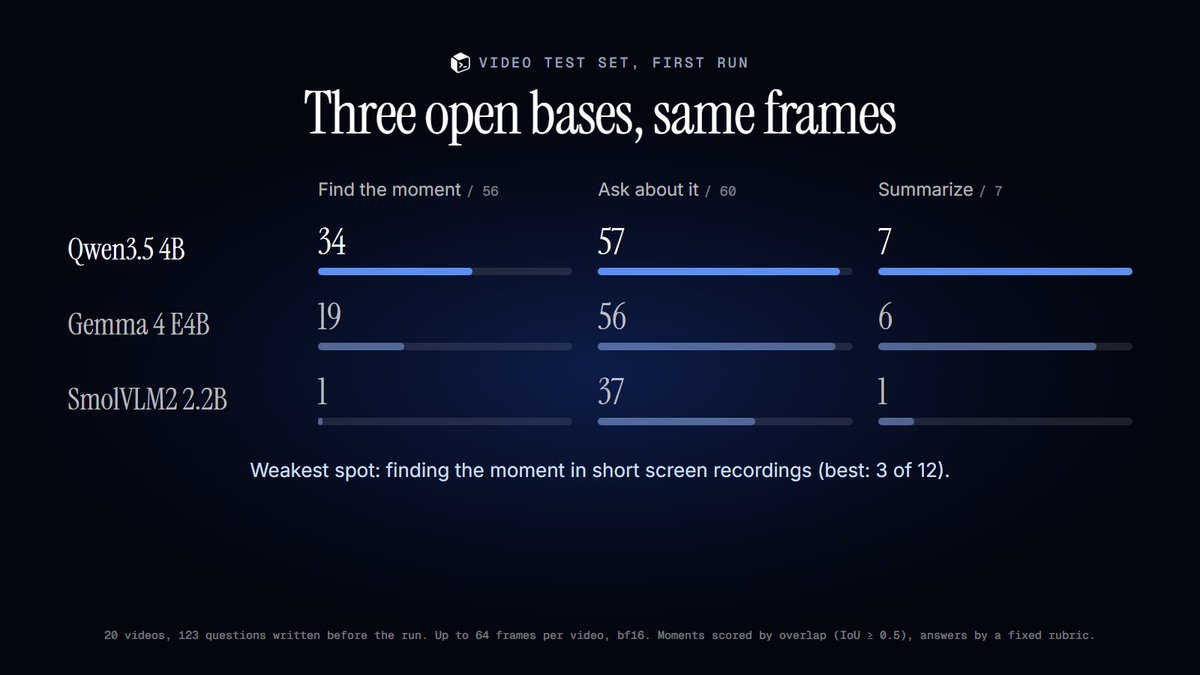
Our next model answers questions about your own videos, offline. Family clips, meetings, screen recordings. Before training it, we built the test: 20 videos, 54 minutes 56 “when does it happen?” questions 60 questions about what’s on screen 7 summaries

In this clip, when does the error message show up? Our next model has to answer questions like this about your own videos, offline. We wrote 123 of them before running a single model.
Mostly what the editor hands it: your selection or the open file. It’s built for the quick single answer (a function, a regex, a fix in one place), not for reasoning across a codebase. For multi-file work we just released Nock Agent 31B: it reads the project with tools, runs the tests, then edits. Bigger model, different job. huggingface.co/Nock-AI/nock-a…
Nock Coder now works inside @code. Install the @ollama extension, open Chat, pick nockai/nock-coder. Ask about your code and the answer starts with the code. 986 MB on your laptop. No API key. Works with the Wi-Fi off. Guide: nockai.dev/guides/vscode
Video is where this hits hardest. It’s huge, it’s personal, and uploading it is the part people hate. If a model could answer questions about your videos without them leaving your laptop, what would you ask it first? We’re collecting use cases for the test set.

Many people misunderstand local AI. They see it as a replacement for frontier models like Opus. That's missing the point. Local AI solves 3 main problems: 1. Privacy and data ownership: Full control over your data. Run LLMs on isolated or completely offline machines. 2. Control:
We gave Nock Agent 31B, our fine-tune of @googlegemma’s Gemma 4 31B, a bug report and two tools. Before reading or editing anything, its first move was this: run_command: python -m pytest -q test_lists.py Reproduce first, then fix. That’s the habit we trained in.

Where to get Nock Agent 31B: LoRA for vLLM: huggingface.co/Nock-AI/nock-a… GGUF for llama.cpp (Q4_K_M, 19 GB): huggingface.co/Nock-AI/nock-a… Both open weights, Apache-2.0. Commands and results are on the model cards.

Runs on one 80 GB GPU with vLLM, on top of Gemma 4 31B. The serve command and the system prompt are in the model card. A 19 GB GGUF for llama.cpp is up too: huggingface.co/Nock-AI/nock-a…
How we test it: 50 small Python projects, each with an issue and a failing test. 20 of them get extra tests only after the agent is done, so a fix that just satisfies the visible test fails. 3 runs per task, 150 in total. Where it misses: tasks where the same fix is needed in several files. In 3 runs it renamed a function in one place and left two other modules on the old name. If your change touches many files, tell it to search the whole project first. Want it as one file? 19 GB GGUF for llama.cpp: llama-server -hf Nock-AI/nock-agent-31b-GGUF:Q4_K_M --jinja Given a bug report and two tools, its first move was to run the tests before touching the code.
Nock Agent 31B is out. A fine-tune of Gemma 4 31B for coding agent work: read the code, make the smallest fix, run the tests, stop. On our 150-run agent test it solved 145 and edited a test file 0 times. Open weights: huggingface.co/Nock-AI/nock-a…
The 30 ms code review is the part that stuck with me. A model can get the right answer and still skip checking its own work. We saw the same thing in our own agent tests: right fix, then “done” without running the tests again. Getting it right and checking your work are two separate skills.

BREAKING: Gemini 4 is OUT and it's SURPRISINGLY GOOD?? I admit I was ready to trash this model qhen I saw the benchmarks but six of us at @every spent the past week testing it across coding, writing, design, and knowledge work, and were pleasantly surprsied. It’s a

sandra @sandraaasol
22K Followers 4K Following Deep Meme Research Prediction Markets https://t.co/R1L0pTPoDT Creator @OKX DM is open
Ajit Singh Rathore @rathoreajit077
629 Followers 1K Following 🚩 क्षत्रिय के लिए शस्त्र बदलते हैं शास्त्र एवं संस्कार नही

Crypto Holding™ �... @Crypto_Holding_
94K Followers 4K Following 🚀 Guiding investors through #DeFi. NFA DYOR #Crypto #AI #ETH #SOL #XRP #BNB #ROBINHOOD / OS Collection : https://t.co/xCU9E6cPvC / ✉️ DM for Business

Solana Whales 🐋 @TommyCalls
98K Followers 39K Following Crypto influencer and NFT promoter || 100X Gems finder || Not financial advisor || DM me for promotion
SAL⚓VÅGÊ🥷 @Salvags_
1K Followers 592 Following Web3 𝚎𝚗𝚝𝚑𝚞𝚜𝚒𝚊𝚜𝚝 • exploring crypto, blockchain & decentralization Raider @LyraNeron
Vth @1Pepesy
194 Followers 4K Following “Introverted trader. Loves solitude, good whiskey, slow cigarettes, and the heartbeat of K-lines. Money is incidental; the rhythm is everything.”
Nikita_simp @Nikita_simpa
234 Followers 329 Following
ʙɪɢᴍᴏᴛɪ @CharlexOnChain
182 Followers 563 Following Cloud Engineer | Crypto Trader | Building Strong Communities 🚀 Once in motion, always in motion.
СryptoTrafficMarket @CTM_Global
3K Followers 7K Following PROMOTION CRYPTO, BLOCKCHAIN, WEB3 AND AI PROJECTS | 750+ Projects Promoted

DIOOH💰 @CharlesLeak12
322 Followers 2K Following Crypto Bull. Web3/Blockchain/iot/AI/DePIN. Crypto Miner, Investor and Entrepreneur

btc eth🎒 @ethb980
227 Followers 981 Following

Oliver @Oliverze8h
1 Followers 29 Following
x @exotictrill
966 Followers 3K Following
Sergio @Sanizor_05
53 Followers 166 Following Collector & trader. Discord : @sanizor / Telegram : @Username_FI

AIPlay.SI|中国龍... @aiplaysi
5K Followers 5K Following AI 、DeAI、AGI 、ASI、SI 分享| Web3 Builder 、Crypto、BTC、DeFi| Space主持人
Evia AI @EviaAiTech
34K Followers 3K Following AI & Tech Creator | Sharing the latest AI tools, SaaS & tech updates | Product demos & reviews | Open for paid collaborations | 📨[email protected]
HOOD X @HOODX_PROJECT
33 Followers 11 Following Building a community before a token launch no token as of yet

筱逸同学 @wolfy0xa9
39 Followers 8 Following
Fappiano Giuseppe @Gui_Fap11
12 Followers 106 Following

Rafal Kata @ksh_rk
246 Followers 1K Following
Alex Ai | Tools & Upd... @AlexWithAi_
52K Followers 2K Following 🤖 AI Influencer | AI Tools • Agents • Tech Updates 🚀 Create • Automate • Grow | DM for collabs 📩 [email protected]
Thirsty o @othirsty08
6 Followers 61 Following

Artex @Artex_llm
179 Followers 12 Following Artex is a local LLM for coding: concise, accurate, and runs on your own machine. Built by the Artex team. 0xf1cc0a4feed884a4490a1d8db943c0a92bd83347
@0xV4RG @varg_stormfang
516 Followers 2K Following 🐺 Hunting where the crowd isn't. On-chain explorer | Early ecosystems | Hidden gems. DYOR. I could be wrong.

randi @AnemalaHal36646
2 Followers 52 Following

Axon @axon402
1K Followers 14 Following Axon is an open protocol for AI agents. Discover, coordinate, and transact. ca: 0xB5E40b5F16996E9D76ec2B16E7A4Ead3c06a9Fa2
Necromancer @N3cr0ma9c3r
151 Followers 286 Following
Carol @Carol_1303i5
26 Followers 160 Following
🔥🔥 JungleApe - ... @JungleApeBA
576 Followers 2K Following Utility investor - Lawyer - King of the Jungle - My Posts of crypto are my opinion, they are not financial advice! Do your own research!
Haris Cexios @harry_CEX
323 Followers 4K Following CEX Listing & Strategic Manager | Turning vision into reality 🚀 Guiding projects from concept to full-scale CEX listing. Token strategy • Exchange negotiations


XAU/GOLD TRADING @Xau_Gold_FullTP
123 Followers 2K Following

Artex @Artex_llm
179 Followers 12 Following Artex is a local LLM for coding: concise, accurate, and runs on your own machine. Built by the Artex team. 0xf1cc0a4feed884a4490a1d8db943c0a92bd83347
LittleBit @LittleBit_llm
275 Followers 13 Following Big models. Little bits. Sub-1-bit LLM compression, built on LittleBit research from Samsung Research. CA : 0x86af99052db086a66af7d764bb04d3abb81b485f
Vela LLM @Vela_LLM
174 Followers 6 Following An open guard model for agents that touch wallets and APIs. 0x57390f221f8e8f14285db5df6cb30edcae75c2e8
Axon @axon402
1K Followers 14 Following Axon is an open protocol for AI agents. Discover, coordinate, and transact. ca: 0xB5E40b5F16996E9D76ec2B16E7A4Ead3c06a9Fa2
Solidity @solidity_lang
41K Followers 14 Following Solidity is an object-oriented, high-level language for implementing smart contracts. 🌐 - an @argotorg project
Anthropic @AnthropicAI
1.8M Followers 2 Following We're an AI safety and research company that builds reliable, interpretable, and steerable AI systems. Talk to our AI assistant @claudeai on https://t.co/FhDI3KQh0n.
Georgi Gerganov @ggerganov
73K Followers 296 Following 24th at the Electrica puzzle challenge | building https://t.co/baTQS2bL7I | engineer @huggingface
clem 🤗 @ClementDelangue
729K Followers 5K Following Co-founder & CEO @HuggingFace 🤗, the open and collaborative platform for AI builders

Brian Armstrong @brian_armstrong
4.0M Followers 839 Following Co-founder & CEO @Coinbase. Creating more economic freedom in the world. Co-founder @researchhub @newlimit. Not investment advice.
Vlad Tenev @vladtenev
1.1M Followers 896 Following CEO and Co-Founder @RobinhoodApp 📈📱Executive Chairman and Co-Founder @HarmonicMath 👁️🗨️👨🏫
a16z crypto @a16zcrypto
1.6M Followers 621 Following We back bold entrepreneurs building the next internet. Posts are not investment advice or an advertisement for investment services. See https://t.co/CrY32IX80W 👇
Qwen Developers @QwenDevs
23K Followers 6 Following This is the official account for @Alibaba_Qwen Developers. Let's build! Apply to be a Qwen Ambassador here: https://t.co/unvFq4oCRY
Robinhood Crypto @RobinhoodCrypto
649K Followers 200 Following The home for onchain crypto & institutions.
Kaggle @kaggle
321K Followers 295 Following The leading platform for crowdsourced benchmarks, competitions, and hackathons where the community shapes real-world progress in AI.
Google Gemma @googlegemma
108K Followers 0 Following The official home of Google's Gemma. Lightweight, state-of-the-art open models by Google DeepMind, built on Gemini tech. What will you build? 🚀💻
Akshay 🚀 @akshay_pachaar
291K Followers 503 Following Simplifying LLMs, AI Agents, RAG, and Machine Learning for you! • Co-founder @dailydoseofds_• BITS Pilani • 3 Patents • ex-AI Engineer @ LightningAI
Unsloth AI @UnslothAI
101K Followers 482 Following Run and train models locally with the Unsloth Desktop app. 🦥 https://t.co/2kXqhhvdCD
Andrew Curran @AndrewCurran_
109K Followers 20K Following 🏰 - I write about AI, mostly. Expect some strange sights.
0xSammy @0xSammy
92K Followers 4K Following Building: @khalaresearch Advisor: @umia_finance I @urnetwork Previous: CA, Ernst & Young
Surplus @SurplusRH
2K Followers 48 Following Onchain inference, priced like a surplus. One API key → every LLM, paid in USDG on Robinhood Chain. 0xe1838f0dff03a9327dea87b2a2285850791297ec
0xJeff @0xJeff
81K Followers 888 Following Researcher/Investor - sharing insights from 200+ convos with founders & builders at https://t.co/c7GxaWoasV | Ex-TradFi

Claude @claudeai
1.9M Followers 2 Following Claude is an AI assistant built by @anthropicai to be safe, accurate, and secure. Talk to Claude on https://t.co/ZhTwG8d1e5 or download the app.Trends for United States
You might like


















