-
Tweets454
-
Followers14
-
Following86
-
Likes63
Addin Ventures 有參與投資的 portfolio 離開隱形模式,正式對外露出了! 我們認為機器人的大腦,不久後也應該會有 chatGPT moment 的出現,而 dream labs 很可能就是那個答案!
Today, Dream Labs is coming out of stealth with Dream-1, a robot foundation model that controls bimanual robots it has never seen, on tasks it was never shown, in places it has never been, from $3/hour. Dream API is live for everyone, today. 🧵
Full essay (EN/中文): ntu.vc/blog/business-…
Great technology doesn't automatically build a great business. Most technical founders can build the product. Fewer can make the business model line up. Starting a series on the part that gets skipped 🧵
The one rule for a business model: it has to line up, front to back. You think you serve A, but A won't buy — your real ICP is B. Right customer, wrong channel? No PMF. They pay, you still lose money? Cost structure. Break the chain and it crashes.
What belongs in a business plan (and what a VC actually reads): 1. The problem you see 2. How you solve it 3. Why you — pain point + Traction + team 4. What you'll scale + how much it costs Results the capital buys + the investor's return Underneath all of it: your business model
LLM Knowledge Bases Something I'm finding very useful recently: using LLMs to build personal knowledge bases for various topics of research interest. In this way, a large fraction of my recent token throughput is going less into manipulating code, and more into manipulating knowledge (stored as markdown and images). The latest LLMs are quite good at it. So: Data ingest: I index source documents (articles, papers, repos, datasets, images, etc.) into a raw/ directory, then I use an LLM to incrementally "compile" a wiki, which is just a collection of .md files in a directory structure. The wiki includes summaries of all the data in raw/, backlinks, and then it categorizes data into concepts, writes articles for them, and links them all. To convert web articles into .md files I like to use the Obsidian Web Clipper extension, and then I also use a hotkey to download all the related images to local so that my LLM can easily reference them. IDE: I use Obsidian as the IDE "frontend" where I can view the raw data, the the compiled wiki, and the derived visualizations. Important to note that the LLM writes and maintains all of the data of the wiki, I rarely touch it directly. I've played with a few Obsidian plugins to render and view data in other ways (e.g. Marp for slides). Q&A: Where things get interesting is that once your wiki is big enough (e.g. mine on some recent research is ~100 articles and ~400K words), you can ask your LLM agent all kinds of complex questions against the wiki, and it will go off, research the answers, etc. I thought I had to reach for fancy RAG, but the LLM has been pretty good about auto-maintaining index files and brief summaries of all the documents and it reads all the important related data fairly easily at this ~small scale. Output: Instead of getting answers in text/terminal, I like to have it render markdown files for me, or slide shows (Marp format), or matplotlib images, all of which I then view again in Obsidian. You can imagine many other visual output formats depending on the query. Often, I end up "filing" the outputs back into the wiki to enhance it for further queries. So my own explorations and queries always "add up" in the knowledge base. Linting: I've run some LLM "health checks" over the wiki to e.g. find inconsistent data, impute missing data (with web searchers), find interesting connections for new article candidates, etc., to incrementally clean up the wiki and enhance its overall data integrity. The LLMs are quite good at suggesting further questions to ask and look into. Extra tools: I find myself developing additional tools to process the data, e.g. I vibe coded a small and naive search engine over the wiki, which I both use directly (in a web ui), but more often I want to hand it off to an LLM via CLI as a tool for larger queries. Further explorations: As the repo grows, the natural desire is to also think about synthetic data generation + finetuning to have your LLM "know" the data in its weights instead of just context windows. TLDR: raw data from a given number of sources is collected, then compiled by an LLM into a .md wiki, then operated on by various CLIs by the LLM to do Q&A and to incrementally enhance the wiki, and all of it viewable in Obsidian. You rarely ever write or edit the wiki manually, it's the domain of the LLM. I think there is room here for an incredible new product instead of a hacky collection of scripts.
今天和一位準爸爸朋友聊,我推薦之後用兩種服務: 一個是雜事外包,我用彭婉如基金會,他們用心培訓很多中年婦女,家事和煮菜,四小時1300-1500元,一週看需求可1-3次。 一個是陪玩姊姊,我用的是Bananny 平台,我找幼教系大四或剛畢業新鮮人,三小時900-1000元。我希望能好好互動閱讀或玩一些有意思的遊戲。我通常會一週找3-4個姊姊輪班。 用上述兩種服務時,除了能幫父母省下不少時間,我都有種做好事的感覺。 早上才讓一個姊姊才試教,她剛考上幼保教師證,正在幼稚園實習,被當全職用,一個月實習薪水5000元… 會想要晚上下班或假日還兼職賺錢的年輕人,我都給予肯定,如果家裏經濟狀況不好的應徵者,我優先錄取。 平常在外面許多消費,我感覺一大部分還是流入財團的口袋,但上面這兩種服務,都是紮實的完全交到勞動者手上,感覺還是很不錯的。

Make money by making concentrated bets on yourself. Lose money by making diffuse bets on others. Invest money by betting on people you would work with, running businesses that you could run.

great use (and metrics) of the openai fine-tuning api:

Exciting update to Copilot on Perplexity with @OpenAI's GPT-3.5 fine-tuning API! We've improved speed, reduced cost, and matched GPT-4 performance. Copilot now engages faster without losing quality. Here's what you need to know: 🧵
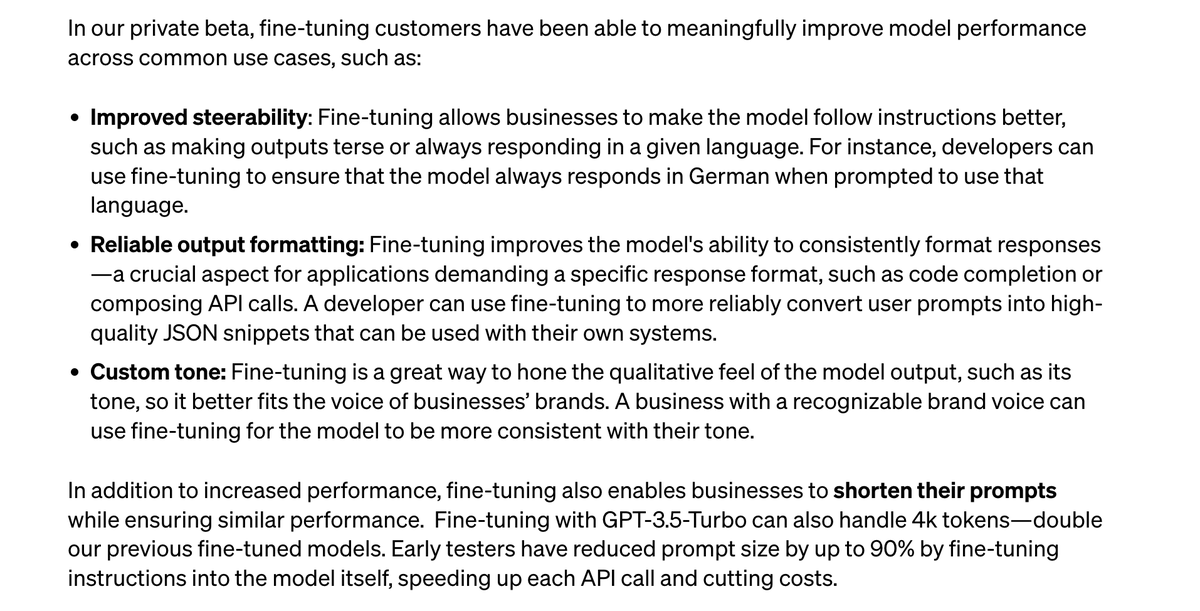
fine-tuning for GPT-3.5 turbo! (and coming this fall for GPT-4)
We've just launched fine-tuning for GPT-3.5 Turbo! Fine-tuning lets you train the model on your company's data and run it at scale. Early tests have shown that fine-tuned GPT-3.5 Turbo can match or exceed GPT-4 on narrow tasks: openai.com/blog/gpt-3-5-t…
Crunchbase's 2023 H1 Investment Report: 1. Decade of Growth in All Stages 2. Hot AI Market 3. Longer Timeframes for Next Funding Round pse.is/54ycbr
進入 2023 年下半年,對於未來的新創投資狀況有什麼展望呢? 這週很開心能夠接受台杉投資的邀請,跟幾位台灣很優秀的創投一起探討,從 2022 年市場反轉以來,創業者跟投資人遇到的挑戰,以及如何在這樣艱難的環境下生存與成長。 pse.is/535w92
@sama We will host a 2-day Generative AI conference in Taiwan on May 6th - 7th. We expect more than 500 people to attend this event. Would you like to visit Taipei too?
We’ve added initial support for ChatGPT plugins — a protocol for developers to build tools for ChatGPT, with safety as a core design principle. Deploying iteratively (starting with a small number of users & developers) to learn from contact with reality: openai.com/blog/chatgpt-p…
E120 - besties are back! -- banking crisis -- potential solutions to the global debt problem -- the great VC reset -- SCIENCE CORNER RETURNS! 🔊: bit.ly/alline120 📺: bit.ly/alline120yt

US stock market returns:

I support the Mensarius Oath for ethical investing. vcl.to/mensarius #MensariusOath
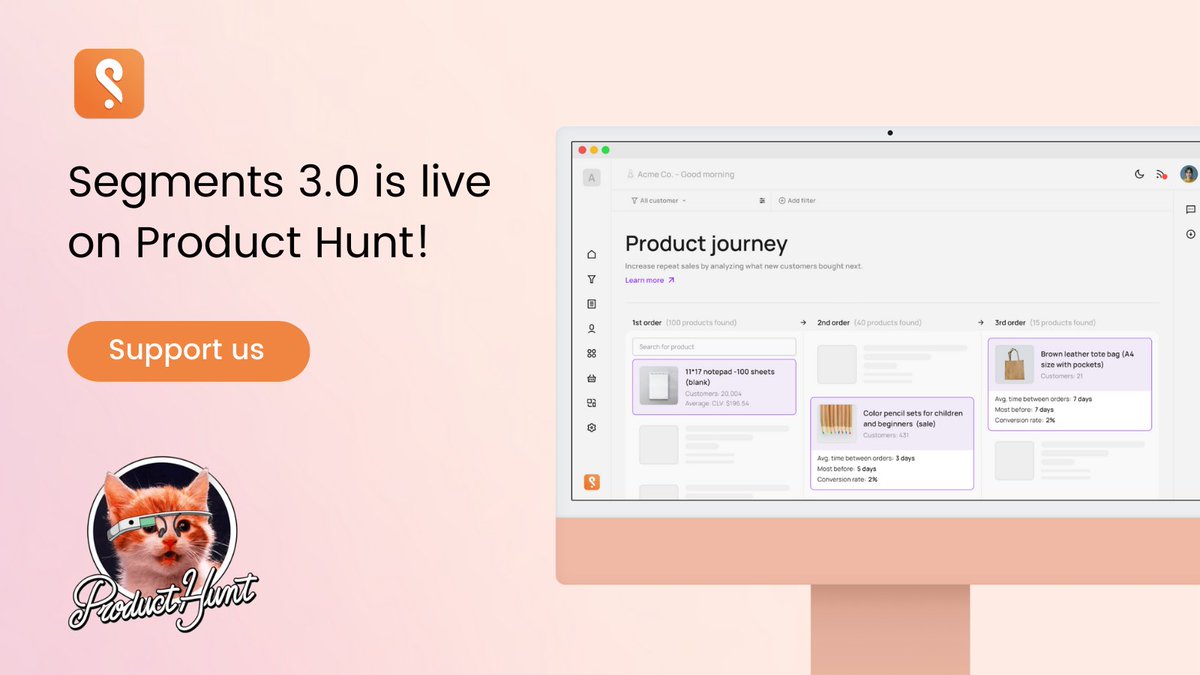
We are live on Product Hunt! 🚀🚀 Today, analytics becomes a team sport. Check out the new collaboration features coming with Segments 3.0 on our Product Hunt page: producthunt.com/posts/tresl-se… Use the code “producthunt” for a 1-month free trial

Belinda @thecraigery420
1 Followers 127 Following Trade up to $300,000. Pass the test. Get funded | The #1 crypto prop firm helping traders go pro | Backed by @Bybit_Official and @Osasuna

GitRoll @gitroll_io
1K Followers 292 Following GitRoll shows real coding skills of developers ✨ Talk is cheap. Show me the code.
YuHsuan Chao @yhchao_tw
366 Followers 2K Following reads most things online these days but still likes to hoard books
超級小狗勾🐶 @doggiedoggie_
459 Followers 726 Following Alex |180/67 24ys | 易害羞 慢熱 🦴 sub/m🦴 Crypto trader /bitget vip |🐶💕

Wayne Huang @waynehuang
2K Followers 4K Following Stablecoins, monetary systems, Bitcoin, DeFi, cybersecurity. Chair of @stblcnsummit, Co-Founder of @UnitasProtocol, Group CEO of @XREXinc, PhD in CS
YT 歪踢 🌐 @YTnComms
27 Followers 154 Following 溝通 | 商業定位 | 中小企業 | 傳產 vs 新創 | 想到什麼寫什麼 | 不定期更新 | 歡迎閒聊搏感情 (無料)
Sheldon Su @YSHSheldon
164 Followers 854 Following a storyteller with a passion for growth & product design
ninganurag439 @ninganurag439
14 Followers 553 Following only looking for sex or would even consider sending a naked pic to someone they dont know. please follow me. http://t.co/dSAtGTjgb5

cornbear @cornbear
3 Followers 53 Following
Dream Labs @dreamlabs_ai
4K Followers 12 Following Building everyday capabilities for everyday robots.

美研芒格君 @Kay2289123
34K Followers 43 Following 来自硅谷的投研团队 成员来自斯坦福、沃顿商学院 懂技术的投资者,懂投资的工程师 致力于让模型更聪明、更快、更便宜
郭明錤|Ming-Chi ... @mingchikuo
252K Followers 400 Following 香港天風國際證券分析師,分享科技產業趨勢觀察|TF International Securities (HK) analyst sharing tech trend insights
Felix Hong @FelixHong117602
304 Followers 329 Following Husband, father, son, manager, traveler, driver, thinker, writer - all things I wish I was good at.
SpaceX Super Intellig... @SpaceXSI
2.1M Followers 6 Following
Unclestocknotes @Unclestocknotes
30K Followers 2K Following U.S. stock market influencer | Financial background | Global traveler | Sharing insights on markets, trade, and economics | Swim, basketball, golf enthusiast.
Mark Chen @markchen90
84K Followers 371 Following Chief Research Officer at @OpenAI. Coach for the USA IOI Team.
Martin Tobias (Pre-Se... @MartinGTobias
61K Followers 10K Following Entrepreneur, Investor, girldad, cyclist, surfer, poker player. Pre-seed up to $500K. Chat with me https://t.co/96wsMImeiy. Get $$ https://t.co/d7utyst2XW
Garry Tan @garrytan
1.1M Followers 6K Following President & CEO @ycombinator —Founder @garryslist—Creator of GStack & GBrain—designer/engineer who helps founders—SF Dem accelerating the boom loop
GitRoll @gitroll_io
1K Followers 292 Following GitRoll shows real coding skills of developers ✨ Talk is cheap. Show me the code.
Beth Kindig @Beth_Kindig
184K Followers 5K Following Investor with higher returns than Wall Street's Old Boys Club. Audited portfolio, automated hedge and free weekly analysis.
YuHsuan Chao @yhchao_tw
366 Followers 2K Following reads most things online these days but still likes to hoard books
Elizabeth Yin 💛 @dunkhippo33
135K Followers 3K Following Co-founder @hustlefundvc. Founder and startup investor. SF Bay Area native.
Golden Gate Ventures @GoldenGateVC
6K Followers 497 Following A $250M early-stage VC in Southeast Asia w/ a diverse set of experiences from 3 continents & Silicon Valley @vlauria @atoylet @jvinnyhall @michaellints
Jamie Lin 林之晨 @MrJamieLin
10K Followers 1K Following CEO@Taiwan Mobile / Chairman@AppWorks = $386M AUM VC & accelerator of 663 active startups / 2,189 founders / $8B raised / $42B valued / $19B ARR / 28K employees
Andrey Zagoruiko @andreyzagoruiko
4K Followers 410 Following not the brightest bulb in the ship’s intellectual chandelier, if you get my drift

fox hsiao @pirrer
27K Followers 1K Following https://t.co/ADltMSqInz A starter, Founder of iCook / INSIDE
Liang-Bin Hsueh @hlb
5K Followers 2K Following Generative AI evangelist. Co-Founder of @MeetAndyAI. Former founder of @InfuseAI, @Handlino and @KKTIX.
Mr.Friday @MrFriday
4K Followers 317 Following Believing in what you do defines who you are. 大學開始接觸資訊科技,雖然喜歡演算法,但是大多數時候嘴砲比Coding多。 有時會寫一點部落格。https://t.co/IUPeUpe1p3 ,筆名Mr. Friday,退役Facebook員工。目前任職於 Aledade

Sebastian Raschka @rasbt
530K Followers 1K Following ML/AI research engineer. Ex stats professor. Author of "Build a Large Language Model From Scratch" (https://t.co/O8LAAMRzzW) & reasoning (https://t.co/5TueQKx2Fk)
François Chollet @fchollet
750K Followers 832 Following Co-founder @ndea. Co-founder @arcprize. Creator of Keras and ARC-AGI. Author of 'Deep Learning with Python'.
Google DeepMind @GoogleDeepMind
1.6M Followers 268 Following The engine room of @Google. Building AI safely and responsibly to solve the world’s most complex problems. Join us: https://t.co/jUHQA27iBL
Andrew Ng @AndrewYNg
1.9M Followers 1K Following Co-Founder of Coursera; Stanford CS adjunct faculty. Former head of Baidu AI Group/Google Brain. #ai #machinelearning, #deeplearning #MOOCs
Emad @EMostaque
348K Followers 533 Following Building open source AI we own Founder @ii_posts, @StabilityAI Consistent inference is possible.

Yann LeCun @ylecun
1.3M Followers 799 Following Founder/Chair, AMI Labs; Professor, NYU; Partner, 224 Ventures; Ex-Chief AI Scientist, Meta. Researcher in AI, ML, Robotics, etc. ACM Turing Award Laureate.
Andrej Karpathy @karpathy
4.4M Followers 1K Following
AK @_akhaliq
536K Followers 3K Following AI research paper tweets, ML @Gradio (acq. by @HuggingFace 🤗) dm for promo ,submit papers here: https://t.co/UzmYN5XOCi
OpenAI @OpenAI
5.5M Followers 4 Following OpenAI’s mission is to ensure that artificial general intelligence benefits all of humanity. We’re hiring: https://t.co/dJGr6LgzPA
Jack Farley @JackFarley96
90K Followers 6K Following Co-founder of Monetary Matters Network: https://t.co/yANVgsTvJU
Wayne Huang @waynehuang
2K Followers 4K Following Stablecoins, monetary systems, Bitcoin, DeFi, cybersecurity. Chair of @stblcnsummit, Co-Founder of @UnitasProtocol, Group CEO of @XREXinc, PhD in CS
Steven Kelly @StevenKelly49
10K Followers 392 Following Senior Advisor, @FDICgov. Former director at the Yale Program on Financial Stability. Still an academic at parties. (Personal views only.)
Jenny Fielding @jefielding
45K Followers 4K Following Managing Partner, @EverywhereVC investing in pre-seed founders building the future of money, health and work 🚀
YT 歪踢 🌐 @YTnComms
27 Followers 154 Following 溝通 | 商業定位 | 中小企業 | 傳產 vs 新創 | 想到什麼寫什麼 | 不定期更新 | 歡迎閒聊搏感情 (無料)
SBF @SBF_FTX
1.0M Followers 3K Following Posting via proxy using BOP-approved 📧/📞 Contact: mail (include return address & "Samuel Bankman-Fried 37244-510") / 11235813sam at gmail (indirect). No DMs.
vitalik.eth @VitalikButerin
8.0M Followers 551 Following I choose balance. First-level balance. mi pinxe lo crino tcati https://t.co/gCQrmCby7P
Brian Armstrong @brian_armstrong
4.0M Followers 841 Following Co-founder & CEO @Coinbase. Creating more economic freedom in the world. Co-founder @researchhub @newlimit. Not investment advice.
Hayden Adams 🦄 @haydenzadams
2.4M Followers 675 Following Invented the Uniswap protocol, Founder @Uniswap
David Sacks @DavidSacks
1.8M Followers 4K Following Tech founder & investor @Craft_Ventures @theallinpod. Co-Chair, President’s Council of Advisors on Science & Technology.
Segments Analytics (U... @treslco
143 Followers 383 Following Helping @Shopify brands optimized marketing with data science 🔥 Our clieents inlcude: @iliabeauty @SDJBeauty @truebotanicals @meshkiofficial @hayabusacombat
Forgiven @forgivenever
28K Followers 1K Following Web3招商主任 Global South加密議元 Chief Shilling Officer of Conflux 业内知名牛马Trends for United States
You might like