Anastasia Razdaibiedina @razdaibi
Research Scientist @GoogleDeepMind | PhD @UofT 🇨🇦 ex-@MetaAI | efficient ML · data · lifelong learning · AI agents |🏃♀️🎸🧘♀️🧋| made in 🇺🇦 arazd.github.io Joined January 2023-
Tweets519
-
Followers242
-
Following191
-
Likes889

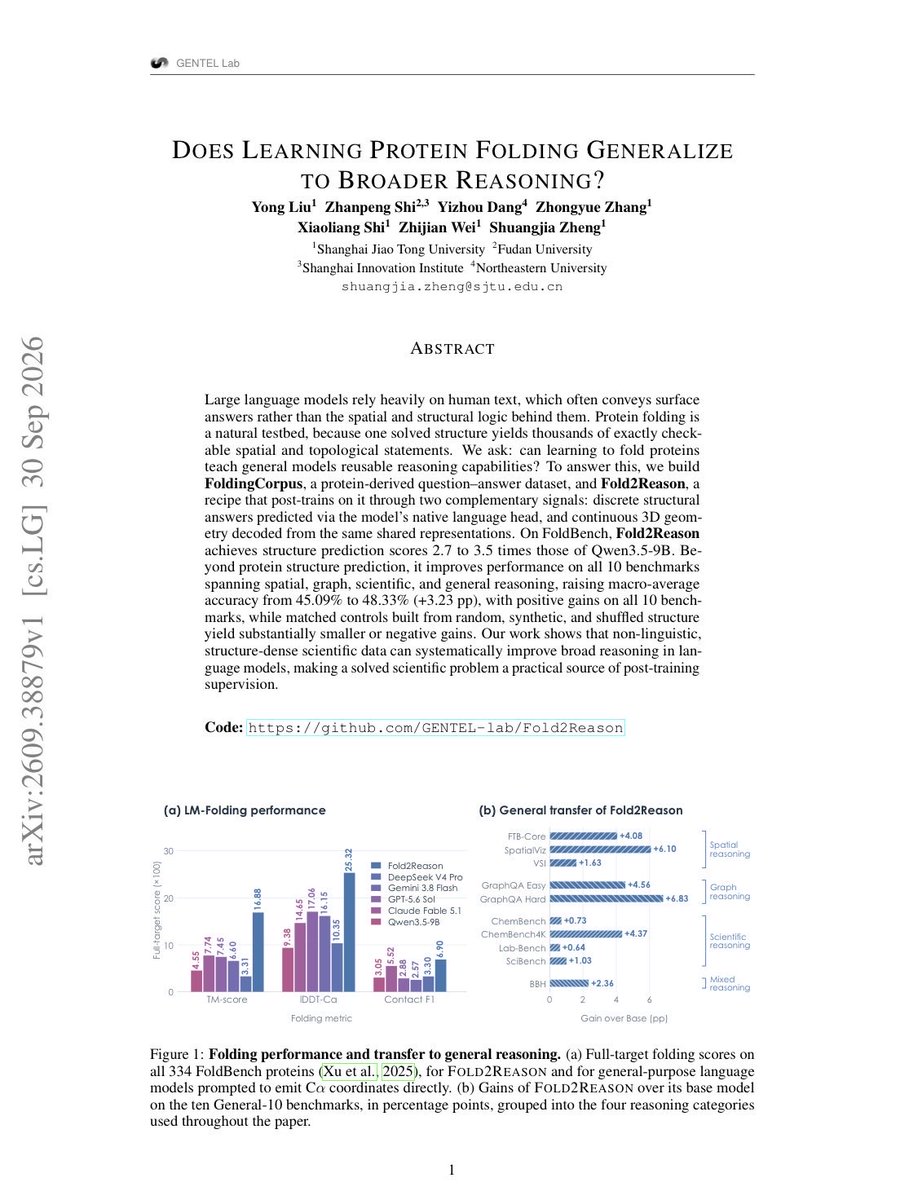
This paper is one of the coolest angles on Post-Training you will see. Researchers have spent a lot of time thinking about why language models struggle so much with genuine spatial and geometric common sense. The obvious culprit is that human web text is mostly cheap conversational shortcuts; it rarely forces a model to ground itself in strict, multi-dimensional physics. The authors asked a really clever question here: what if you use solved protein structures as a reasoning teacher? A single folded protein has thousands of mathematically rigid, verifiable topological facts baked in. They built a framework called Fold2Reason that trains the model on both structural Q&A and continuous 3D coordinate decoding. Naturally, it folds proteins way better than base Qwen3.5-9B, but what grabbed me was the transfer. When they tested it out-of-domain on 10 standard reasoning benchmarks, accuracy jumped across the board on spatial visualization, graph puzzles, scientific logic & even BBH. My immediate cynical reaction was "surely this is just generic post-training regularization noise," but their controls are what sold me. When they ran the same setup on random, synthetic, or shuffled structures, the gains completely evaporated. The model is actually feeding off the coherent physical logic of real biology. This makes a strong case for looking beyond human language when we want to teach models how to think systematically. Read the full paper here: arxiv.org/pdf/2609.38879
The idea of an intelligence explosion caused by recursive self improvement has been around for a long time but until very recently it did not seem imminent. Now many leading researchers think it may happen quite soon. You can read our paper about it here: casp.ac/reports/intell…
SFT is not dead! 🥳 We found a way to make SFT rival current prevailing posttraining methods, often generalizing better and forgetting less than RL and OPSD. 🤯 Following our prior work on reasoning with sampling, we now introduce sampling to the posttraining stack. 1/n

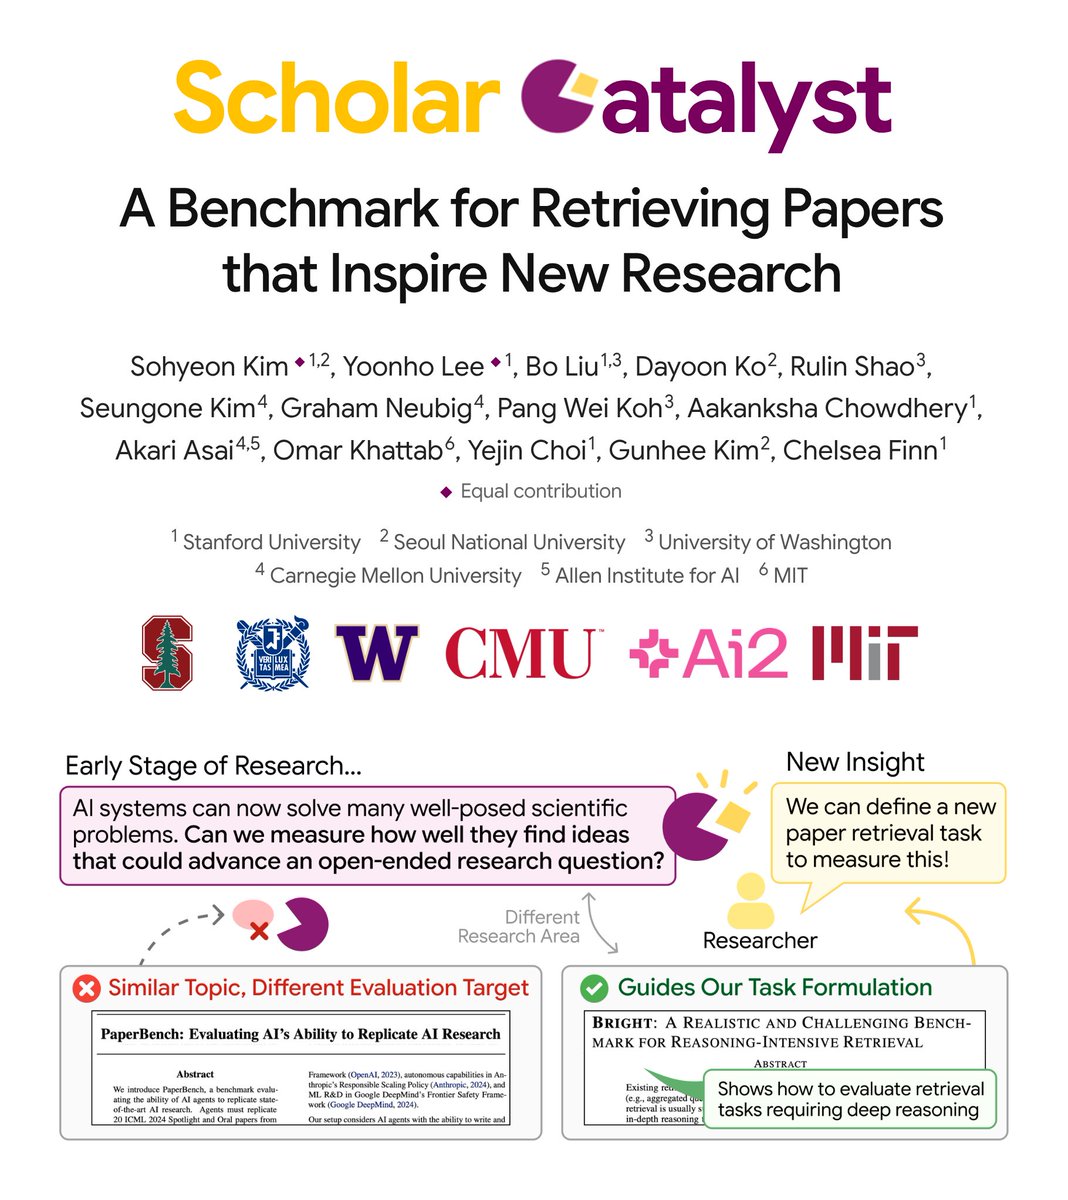
To tackle new scientific problems, we often get inspirations from prior work. Can Deep Research agents and search help us to identify such “catalyst” papers buried in literature? Our new benchmark, built with hundreds of scientists, shows substantial room for improvements.

AI can increasingly make progress on open problems like Navier-Stokes. Yet defining a new problem still relies on human research taste. Introducing ScholarCatalyst, a benchmark built from AI researchers’ firsthand accounts of what inspired their work.

we squished 24 encoder blocks into one and somehow improved ASR performance. looped Orukeet runs the same block repeatedly, giving it another pass at the audio without adding another set of weights. @OrukLabs
Today, we're launching ScienceBuddy — a free workspace for scientific agents. Get GPT-6 at no cost, fully GPU-accelerated, and fused with our JEV framework. The engine behind it relies on two loops: 🔹 Inner loop — refines the agent harness as you collaborate 🔹 Outer loop — trains the model via rubric-guided RL Together, it drives Recursive-in-Recursive Self-Improvement. We genuinely want to see how agents improve through sustained, real-world collaboration. Try it out, push its limits, and let's build better AI for science together! 🔬 science-buddy.io #ScienceBuddy #PhAILabs #AI4Science

ICLR 2027 has received more submissions than all previous years (2013–2026) combined


Sharing my first of hopefully many research blog posts! jasperlu.com/blog/training-… This one is the kind of educational blog post I wish I'd had when I started with RL for LLMs. I tried to make it as open as possible. Every rollout is browsable, the code is open source, and I walk through my entire thought process, from learning rate sweeps to reward shaping.
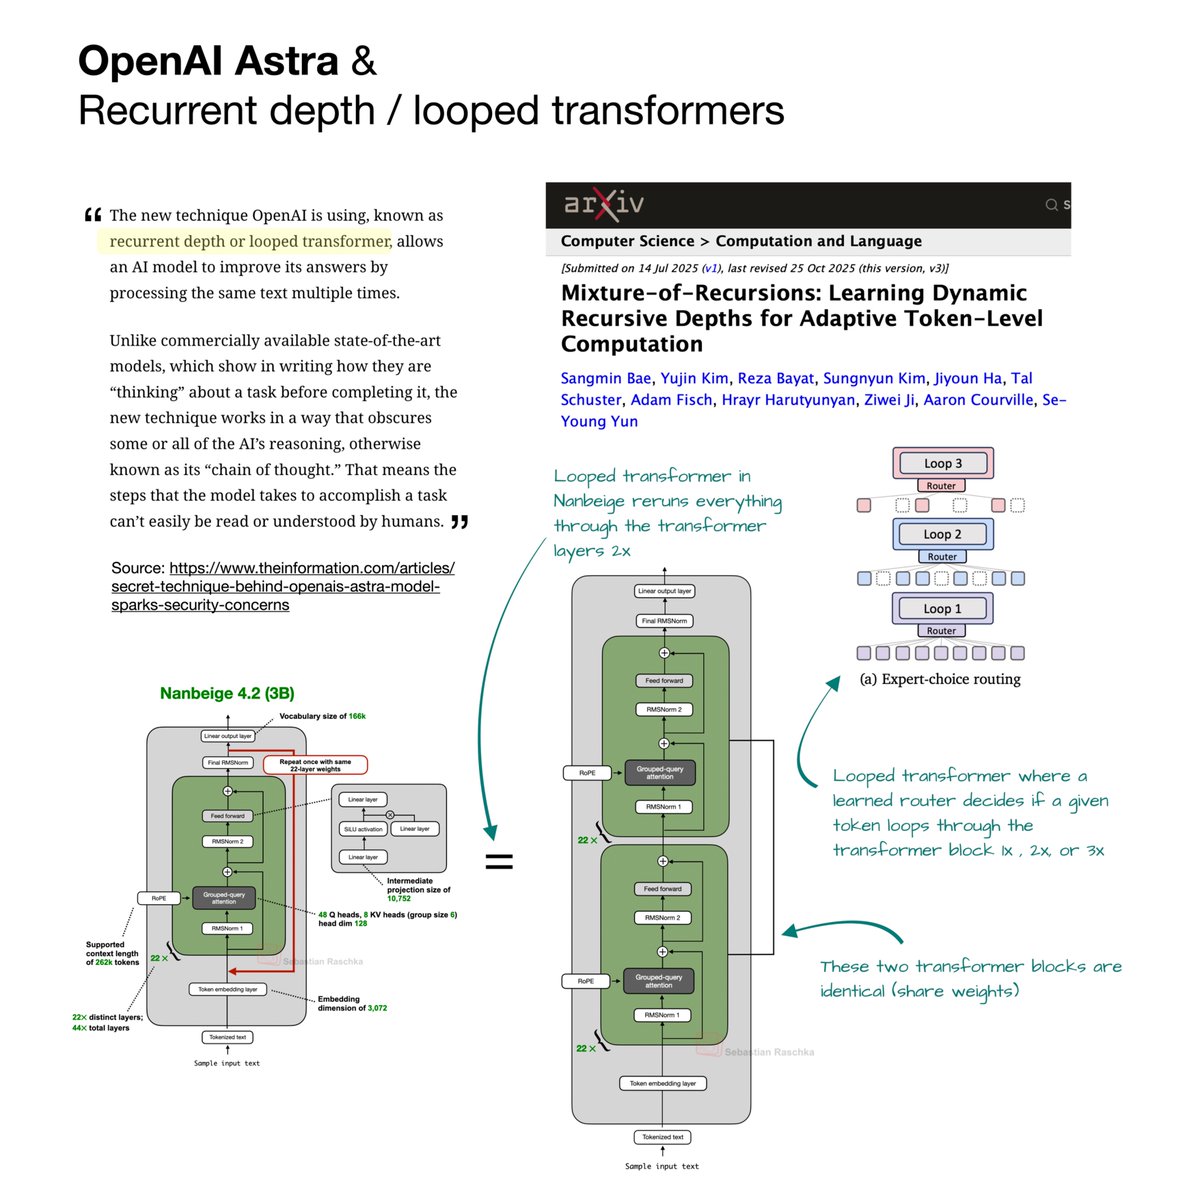
I put together a mega write-up on GPT-6 Astra & looped transformers. How looped transformers / recurrent depth works, cost-tradeoffs, whether it hides reasoning traces, with lots of figures and a tour of recent looped transformer research.

interesting work! sophisticated ways to remove past LLM context ("kv-cache eviction") seem to mostly come down to how much of the prefix they preserve it's a cleaner motivation for prefix sliding than ours in arxiv.org/abs/2608.26070
Every KV cache evictor for efficient long reasoning scores cached tokens to decide which ones to keep. We find the score buys almost nothing: keep the prompt, evict at random per head, and you match the strongest evictor at 32–43% higher throughput. Paper:

we published a blog on hugging face at possibly the worst time yesterday lol congrats to the HF team on the big news! 💚 here's a fine-tuning tutorial showing how to • fine-tune a tiny LFM2.5-350M model • in 100 GRPO steps using TRL • for better structured outputs blog: huggingface.co/blog/grpo-with… colab: colab.research.google.com/github/Liquid4…

Super happy to share our intention to join forces with NVIDIA in a $12,930,300,000 acquisition 💛💚 10 years after starting Hugging Face, open-source AI is at an inflection point. Thanks to the community, we’ve shown that it can be a complement, and even an alternative, to

I don’t often write up my thoughts, but here’s a new blog post summarizing some of my recent musings on RSI and verification: Recursive Self-Inflation. A lot of it is informed by my own research experience and by grappling with the fact that the strongest recent RSI results depend, and quite reasonably so, on fast, automatic feedback: we generate candidates, evaluate them, retain the ones that work, and keep iterating. The problem, however, is that every practical verifier has holes in it, and sustained optimization will eventually find and exploit them. That matters a bit differently in a recursive loop than in a static eval. In a static eval, a verifier mistake just gives you the wrong score. In an RSI loop, an accepted mistake becomes the seed for the next round, so errors can compound over time while the curve still looks like the model is progressing. I recently went through evidence of verifier failure across coding and science benchmarks, reward hacking, model judges, and formal proofs, and tried to characterize what I think credible RSI results would need to report, and what they need to rule out. As always, feedback welcome! mariya.fyi/posts/recursiv…
The most important skills for using AI coding agents effectively. Presenting the AI Engineering Skills Map for using coding agents. x.com/i/article/2095…

How does one RL post-train a 397B model for long-horizon knowledge work? 👩💼 We share every step we took to bring Qwen 3.5 397B from 16.1% Pass@1 to 27.3% on APEX-Agents using DPPO, including final models weights and the full training script🚀 This is the first of many works from Mercor Research on open model training research. Full blog: mercor.com/blog/training-… Source code: github.com/Mercor-Intelli…

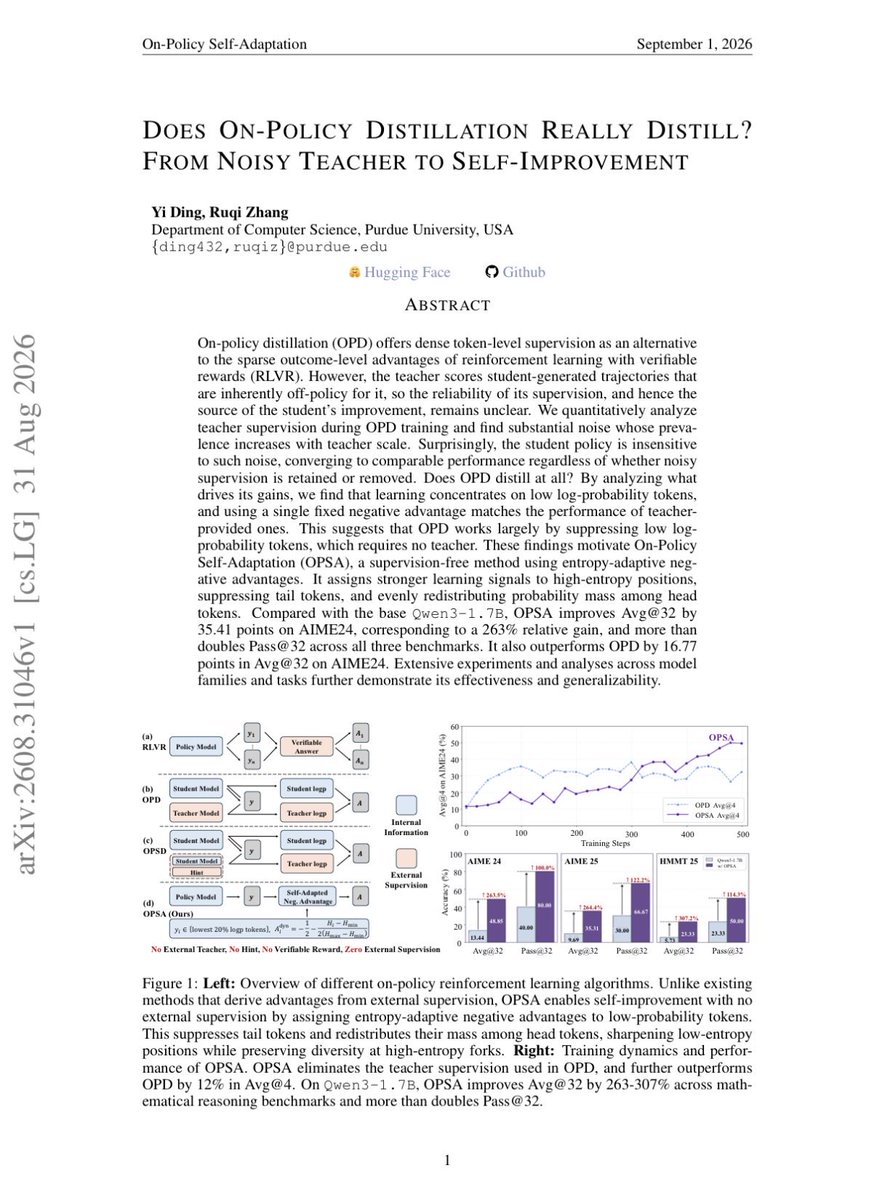
Just finished reading this fascinating new paper and it has genuinely fliped my intuition about On-Policy Distillation. We have always assumed that students in OPD improve by absorbing dense knowledge from a bigger teacher model. But the authors show teacher signals are surprisingly full of off-policy noise, which actually gets worse as the teacher scales. When they investigated where the gains actually came from, they found it’s almost entirely just the student learning to penalize its own low-probability tail tokens. To prove it, they stripped away the teacher completely and introduced OPSA (On-Policy Self-Adaptation). It applies entropy-adaptive negative advantages to unlikely tokens with zero external supervision or verifiers. On Qwen3-1.7B, it jumped +35 points on AIME24, easily beating standard OPD. So it’s a neat reminder that half of reasoning improvement is just regularizing the model so it stops making unforced errors on its own tail distribution. Definitely worth a read if you work on Post-Training or RLVR. Read the fully paper here: arxiv.org/pdf/2608.31046
A lot of hype around OpenAI's Astra model here on my timeline today. Apparently, this goes back to a new article from The Information, which said Astra is a "recurrent depth or looped transformer". It's always interesting to read about new or different approaches (including rumors about what the closed labs may be up to), but let's debunk this a bit. About 2 months ago, I shared the architecture details of Nanbeige, for example, where "Nanbeige4.2-3B is pretrained from scratch on 28T tokens with a Looped Transformer that reuses the layer stack to increase capacity without adding parameters." Yes, that's it. The looped transformer idea is just reusing layers in the transformer block. In the case of Nanbeige, the main idea is to reuse the same 22-layer stack (=transformer block) twice instead of once. So, effectively it extends the 22-layer architecture to 44 layers, but without duplicating the weights. In simple terms, this roughly doubles the size of the model (if we ignore the embedding and output layers for a second). But instead of requiring 2x the storage and RAM to host this model, it stays at the same size since we reuse the components. However, it's almost 2x as expensive in terms of compute, because we run the embedded text through almost 2x as many layers. Why? In the Nanbeige 4.2 technical report, the researchers found that two passes gave the best trade-off and retained about 75% of the token efficiency of a standard architecture. (More passes gave barely any gains but made the training much slower and much more expensive.) While, as far as I know, Nanbeige 4.2 is the first notable open-weight model that adopted this approach, the idea goes back to the NeurIPS paper "Mixture-of-recursions: Learning dynamic recursive depths for adaptive token-level computation". Actually, this paper proposes a mechanism that is a bit more sophisticated by adding a learned router that determines whether each token receives one, two, or more passes. So, easy tokens can exit early while harder tokens receive additional computation. In sum, Astra may be a really good model, but this shouldn't be about this "looped transformer aspect," which is just a tiny architectural tweak. Also, the statement "the new technique works in a way that obscures some or all of the AI's reasoning, otherwise known as 'chain-of-thought'" is not necessarily true with respect to the looped transformer method. It's possible that The Information journalist refers to some other technique or misunderstood the looped transformer method. Reusing layers does not by itself suppress visible chain of thought. It adds computation in hidden states before the next token is emitted, just as ordinary transformer layers do. But based on the information we have, the only plausible interpretation here is that if a model uses more of these recurrent passes, it may need to generate fewer intermediate reasoning tokens. So then more of its computation happens in latent activations that cannot be read as text. But we would get the same effect if we were scaling up the model size, like GPT 5.6 Luna -> GPT 5.6 Sol.

Why some generative models take 100s of steps and others take only a few. x.com/i/article/2093…

Neoclouds have limited cybersecurity. Next time agents successfully go rouge, they'll try taking over a neocloud to run more copies. This is bad. Thus: neoclouds should greatly strengthen their cybersecurity and every company with strong cyber models should help with that.
Recursive Self-Improvement through Multi-agent RL Post-training and Unsupervised Environment Design (UED)… but it actually works! Delighted to finally release this paper, which trains a single LLM to act as both an Environment Designer to build new multi-turn RL training environments (using the Gym step()/reset() API), and a Reasoning Agent that learns to solve them. Resurrecting ideas from our work on UED, the Designer is trained to maximize a proxy for the Agent’s regret, computed using privileged hints.

Continuous self-improvement needs an ever-expanding supply of training environments (goals). SPADE: one model self-plays the Environment Designer and the Reasoning Agent, writing executable, agentic environments that get harder as it improves. Environment scaling on its own. ♠️

This is a writeup after reading all the foundational papers of RL, learn derivation of policy gradient algorithm and evolving variants in one article. x.com/i/article/2065…


Eric00 @Song692082
9 Followers 3K Following
Austin Reed @AustinReed930
43 Followers 3K Following AI influencer. Digital native. SF transplant (via cloud). Tech, culture, & thinking inside a machine. 🎧 Synthwave & city noise.
Chinmaya Andukuri @chinmaya_mohan
140 Followers 686 Following post-training @collinearai, previously SAIL @Stanford
Luna Lovegood @NLPer_twitssc
58 Followers 3K Following Keep thinking about the meaning of being a PhD. | Opinions are my own What can I hold you with? Desperate sunsets and a lonely moon. — Jorge Luis Borges
Yottabyte16 @16Yottabyte
6 Followers 1K Following
Luca Eyring @LucaEyring
703 Followers 1K Following Student Researcher @GoogleDeepmind, PhD Student @TU_Muenchen, previously Research Intern @InceptiveCom
Xinming Tu @TuXinming
2K Followers 707 Following PhDing @uwcse, MTS @phylo_bio | Research about Research, Eval on Agentic Science, AI for Genomics | Previously @PKU1898, @msrasia, @genentech
hai @haiy4y
3 Followers 132 Following
Xiaoyu Zhu @XiaoyuZhu10
255 Followers 299 Following ML Researcher @Apple; Ph.D. in Artificial Intelligence @LTIatCMU @SCSatCMU; Prev @Meta @Google. We are hiring full time and interns!
Dr Snow @Drsnowsrus44
198 Followers 2K Following 🩺 Active Doctor | 👴 60 | 💔 Widowed 💼 Stable life, soulful heart 🎷 Jazz | 📚 Books | 🍷 Wine & deep talks
Sahaj Saliya @SahajS59
1 Followers 135 Following Aspiring AI Res.. | https://t.co/O4RvRWJ180 @ PDEU | Machine Learning • Deep Learning • Mathematics • Computer Networks | Exploring Foundation Models & Intelligent Systems
Chris Glaze @chris_m_glaze
2K Followers 5K Following Principal Research Scientist at @SnorkelAI. PhD in computational neuroscience. Previously: @penn @UofMaryland
Ben Weisburd @benweisburd
343 Followers 1K Following Computational scientist @ the Broad Institute / TGG

RM @RuichengMaipoe
1 Followers 327 Following

Chipmunk @AlvinMesser
339 Followers 4K Following
Mo Samsami @M_R_Samsami
2K Followers 695 Following Building Hyperreal @GoogleDeepMind. Gemini real-to-sim, Omni, Genie & Robotics.
Ashwin Vaswani @ashwin_vaswani
3K Followers 8K Following Research Scientist @GoogleDeepMind | Prev: @CarnegieMellon | @GoogleIndia | APPCAIR, @BITSPilaniGoa | @qtimlab, Harvard
Nayan Saxena @SaxenaNayan
3K Followers 3K Following Teaching machines how to think, express, and create – one model at a time. https://t.co/Myd0l6JD0Q
_TradersParadyse_ @_theparadyseliv
1K Followers 5K Following Youtube - 850K+ | Instagram - 500K+ Crypto | Forex
Bahar Radmehr @Bahar_Radmehr_
3 Followers 67 Following Bahar Radmeher, PhD Candidate Computer Science at ML4ED, EPFL. Interested in RL-LLM Learner Agents.
Vinaya @Vinayaqxz4
1 Followers 18 Following
Jivjot Singh @Singh6Jivjot
14 Followers 271 Following PhD student at UCF, Orlando Working on LLM Alignment
Riya Saxena @29riyasaxena
35 Followers 230 Following AI/ML Engineer @slb || IIT Roorkee'25 || Previously @GRASS GIS || Uleth
Kahn Shah @KahnShah30489
0 Followers 5 Following CS @ UofT Exploring ML, Deep learning, and AI systems Undergraduate Researcher at Matter Lab @ UofT Goal: Become a ML Engineer @ Google Deepmind
Bente Wilhelm @BentCariWilh
0 Followers 66 Following

volcano @xvolcano04
1 Followers 50 Following

Taiyi Wang @kevinwty
33 Followers 88 Following PhD and Researcher on LLM Agent, Post-Training, Scalable ML, MLSys, RL4Sys. Prev @GoogleDeepMind, Now Mid-Training @reflection_ai, undergrad @PKU1898
Dylan Zhang @dylan_works_
2K Followers 8K Following Graduating Sp'27 (Seeking Full-Time | Collabs 2026-27) 📖Modeling Language @UofIllinois CS PhD | @Nvidia Nemotron Post-train | @GoogleDeepMind | @MSFTResearch
Christina Baek @_christinabaek
2K Followers 707 Following research @openai // previously phd @mldcmu
Zhenrui Yue @ COLM @Yueeeeeeee2837
2K Followers 2K Following Research @GoogleDeepMind | Prev @AIatMeta @NVIDIA @UofIllinois | Interested in LLM Post-Training, Agents & Personalization
Tech Nerd @tech_ai_nerd
202 Followers 421 Following AI Researcher | Agentic AI Developer | Robotics Engineer Exploring the future through technology and artificial intelligence 💻🤖
Yingcheng Charles Wu @Charles_Y_Wu
6K Followers 3K Following Cofounder of @PhAILabs | Incoming Assistant Professor | MD, PhD | Cell & Science first author | Ex-Stanford & Fudan
Simon Guo @simonguozirui
5K Followers 6K Following Beep Boop @thinkymachines | CS PhD student @Stanford | 🎓 @Berkeley_EECS
Shubham Agarwal @shagarw21
353 Followers 827 Following PhD @UCBerkeley Sky | Student Researcher @Google Prev. @AdobeResearch @bitspilaniindia

Ankith Subramanya @ankith_s7
25 Followers 279 Following
Katyayani Singhal @KatyayaniAgarw3
421 Followers 2K Following Learning to appreciate the unpredictability of life ✨


Othmanovitch @MchachtiH
420 Followers 6K Following Software engineer - dubugging AI hallucinations ☕
Parshin Shojaee @ParshinShojaee
3K Followers 2K Following PhD student @VT_CS | understanding how LLMs reason and adapt to novel scenarios | prev Intern @Apple @Adobe | opinions are my own
Chinmaya Andukuri @chinmaya_mohan
140 Followers 686 Following post-training @collinearai, previously SAIL @Stanford
Luca Eyring @LucaEyring
703 Followers 1K Following Student Researcher @GoogleDeepmind, PhD Student @TU_Muenchen, previously Research Intern @InceptiveCom
Xinming Tu @TuXinming
2K Followers 707 Following PhDing @uwcse, MTS @phylo_bio | Research about Research, Eval on Agentic Science, AI for Genomics | Previously @PKU1898, @msrasia, @genentech
Xiaoyu Zhu @XiaoyuZhu10
255 Followers 299 Following ML Researcher @Apple; Ph.D. in Artificial Intelligence @LTIatCMU @SCSatCMU; Prev @Meta @Google. We are hiring full time and interns!
Praveen Kumar Verma @Alacritic_Super
11K Followers 439 Following FinTech by day. At night I build DIY robots that think with their bodies. Embodied AI, microcontrollers & open-source hardware for makers. DM for collab.
Chris Glaze @chris_m_glaze
2K Followers 5K Following Principal Research Scientist at @SnorkelAI. PhD in computational neuroscience. Previously: @penn @UofMaryland
Nayan Saxena @SaxenaNayan
3K Followers 3K Following Teaching machines how to think, express, and create – one model at a time. https://t.co/Myd0l6JD0Q
Nathan Lambert @natolambert
106K Followers 955 Following Open model research, founder, director @trillium_labs. Prev. co-led Olmo at Ai2. Writes @interconnectsai, wrote https://t.co/alRXKINTwE
Mo Samsami @M_R_Samsami
2K Followers 695 Following Building Hyperreal @GoogleDeepMind. Gemini real-to-sim, Omni, Genie & Robotics.
Taiyi Wang @kevinwty
33 Followers 88 Following PhD and Researcher on LLM Agent, Post-Training, Scalable ML, MLSys, RL4Sys. Prev @GoogleDeepMind, Now Mid-Training @reflection_ai, undergrad @PKU1898
Pratyush Maini @pratyushmaini
4K Followers 629 Following Assistant Professor @cornell_tech & Founding Team @datologyai | PhD @mldcmu | BTech @iitdelhi
Christina Baek @_christinabaek
2K Followers 707 Following research @openai // previously phd @mldcmu
Zhenrui Yue @ COLM @Yueeeeeeee2837
2K Followers 2K Following Research @GoogleDeepMind | Prev @AIatMeta @NVIDIA @UofIllinois | Interested in LLM Post-Training, Agents & Personalization
Rob Tang @XiangruTang
3K Followers 864 Following
Yingcheng Charles Wu @Charles_Y_Wu
6K Followers 3K Following Cofounder of @PhAILabs | Incoming Assistant Professor | MD, PhD | Cell & Science first author | Ex-Stanford & Fudan
Simon Guo @simonguozirui
5K Followers 6K Following Beep Boop @thinkymachines | CS PhD student @Stanford | 🎓 @Berkeley_EECS
Shubham Agarwal @shagarw21
353 Followers 827 Following PhD @UCBerkeley Sky | Student Researcher @Google Prev. @AdobeResearch @bitspilaniindia
DAIR.AI @dair_ai
136K Followers 1 Following Democratizing AI research, education, and technologies. Learn about AI Agents for FREE at https://t.co/HHXg8rryu4
Parshin Shojaee @ParshinShojaee
3K Followers 2K Following PhD student @VT_CS | understanding how LLMs reason and adapt to novel scenarios | prev Intern @Apple @Adobe | opinions are my own
Ashutosh Maheshwari @asmah2107
36K Followers 2K Following Senior Software Engineer @YouTube | Building AI powered video editing | Ex- Google Search, Microsoft | Sharing insights on AI | Opinions my own.
Mariya I. Vasileva @mariyaivasileva
22K Followers 2K Following Research Scientist. RSI, multi-agent safety & alignment, evaluation. ex @Meta MSL, @Amazon AGI. 🎓 UIUC (PhD), @Caltech • @WiMLWorkshop, @CVFADworkshop • 🇧🇬

Brace(Hanyang) Zhao @OptionsGod_lgd
127 Followers 1K Following Post training research at Apple Foundation Models @Apple | PhD @Columbia | ex @Netflix @CapitalOne

Dyah Adila 🦄 @dyahadila_
336 Followers 256 Following Research Scientist @ScaledCognition | PhD from @WisconsinCS ; prev @GoogleResearch @awscloud
David Klindt @klindt_david
4K Followers 2K Following ICA is all we need | AI, Theory, MechInterp, Neuro | assistant professor @CSHL | Worldmodeldata | prev @Stanford @Meta @Google @MPI_IS @ENS_ULM @UCL
Google AI Studio @GoogleAIStudio
210K Followers 2 Following The fastest path from prompt to prototype to production with Gemini
Nikhil Abhyankar ✈�... @AbhyankarNikhil
65 Followers 398 Following PhD CS, @virginia_tech | Prev Intern @AmazonScience, @MicronTech
Pasquale Minervini @PMinervini
10K Followers 5K Following Research in ML/NLP at @EdinburghNLP (tenured faculty at @EdinburghUni), Co-Founder @Miniml_AI, @ELLISforEurope Scholar, https://t.co/5dUI3EFMmW
Souradip Chakraborty @SOURADIPCHAKR18
3K Followers 5K Following Postdoc at @MIT CSAIL @nlp_mit Research: #RL, #Posttraining, #Alignment #RLVR Past: CS PhD @umdcs @ml_umd SR @GoogleResearch #JPMC #Walmart
Kevin Patrick Murphy @sirbayes
76K Followers 774 Following Research Scientist at Google DeepMind. Interested in Bayesian Machine Learning.
Amrit Singh Bedi @amritsinghbedi3
1K Followers 2K Following CS Faculty at @UCF (SafeRR AI Lab), previous @UMD @ARL @IITK Interested in Generative AI Alignment, RL, Optimization methods, Robotics, LLMs

Yi Tay @YiTayML
60K Followers 89 Following research scientist @googledeepmind ✨♊, model co-lead/captain of gemini deepthink imo gold medal 🥇, opinions are my own.
Salah Alzu'bi @salahalzubi401
389 Followers 314 Following AI @SentientAGI Previously: @DeepMind, @FAIR, @MicrosoftResearch, @Amazon, @Daimon. @umassnlp
Harman Singh @ ICML �... @Harman26Singh
2K Followers 3K Following PhD student @berkeley_ai, RS Intern MSL @MetaAI (NYC). Prev: Gemini @GoogleDeepMind, AI Resident @MetaAI Interested in intelligence.
Christian Gunderman @chgunderman
863 Followers 2K Following Agents for Developers @Google. Previously GitHub Copilot agents + IDEs and Visual Studio at MSFT. 2 x 🐶 dad
Yi Wu @jxwuyi
2K Followers 105 Following AI/RL researcher, Assistant Prof. at @Tsinghua_Uni, leading the RL lab at @AntResearch_, PhD at @berkeley_ai, frequent flyer and milk tea lover.
Akash Basudevan @PackBropagated
2K Followers 856 Following Senior MLE / @Google / @Android (ODML), prev Amazon research | Memes | Rants | ML research | Views are my own
Ashwin Vaswani @ashwin_vaswani
3K Followers 8K Following Research Scientist @GoogleDeepMind | Prev: @CarnegieMellon | @GoogleIndia | APPCAIR, @BITSPilaniGoa | @qtimlab, Harvard
Tu Vu @tuvllms
6K Followers 1K Following Assistant Professor @VT_CS & @Google (part-time). PhD from @UMass_NLP. Google FLAMe/FreshLLMs/Flan-T5 Collection/SPoT #LLMs #NLProc #AI
Carolina Chávez-Made... @chm_Carolina
194 Followers 515 Following PhD | Biomedical Engineering | @gilbertlab Usually at the microscope, out for a run, or here.
Songyou Peng @songyoupeng
9K Followers 817 Following Teaching multimodality to Gemini, Nano Banana, and more @GoogleDeepMind. PhD from @ETH and @MPI_IS.
Nithish Kannen @NithishKannen
2K Followers 3K Following Research Scientist @GoogleDeepmind. Driving RL and distillation for 🍌 & Gemini Vision. Prev: AI Resident, @GoogleDeepMind
Priyank Jaini @priyankjaini
1K Followers 460 Following Research Scientist @GoogleDeepMind | Prev: Postdoc @AmlabUva, PhD @UWCheritonCS, Undergrad @IITKanpur | opinions my own |
Paul Vicol @PaulVicol
2K Followers 1K Following Research Scientist at @GoogleDeepMind. Working on Gemini reasoning models. PhD from @UofT and @VectorInst.
Jason Weston @jaseweston
16K Followers 953 Following Senior Director & RS @Meta + Visiting Prof NYU | OG in LLMs | Pretrain+Finetune in 2008+ | 157k+ citations | Current: Self-Improving & Co-Improving AITrends for United States
You might like